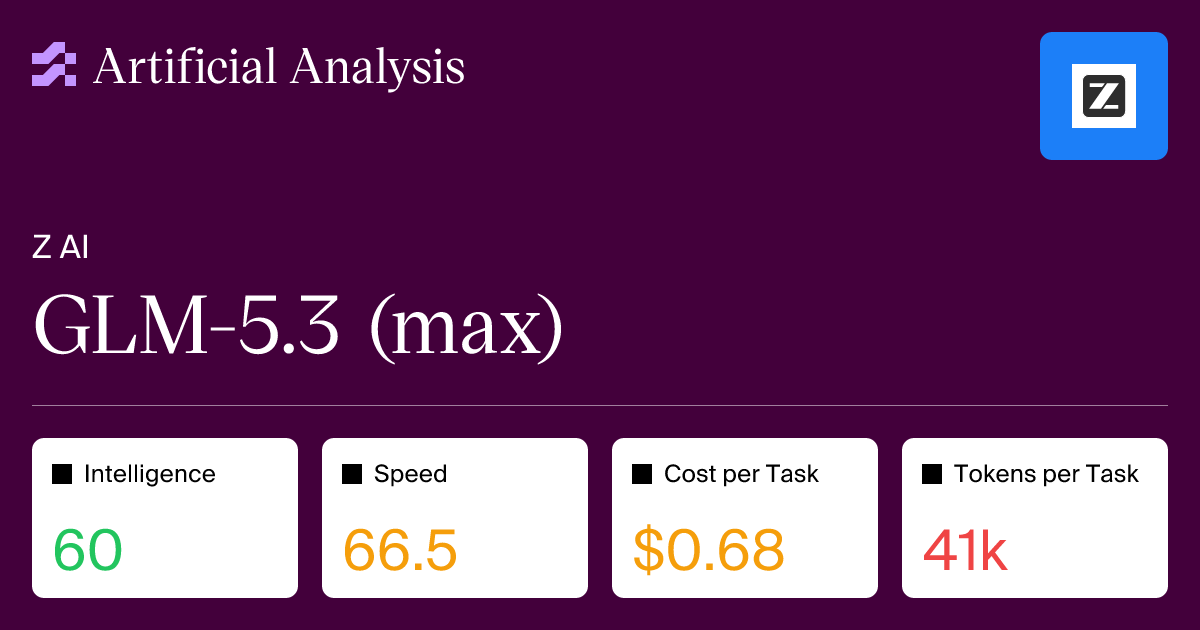
GLM-5.2 (max) API Provider Benchmarking & Price Analysis
Source
ArtificialAnlys
Author
ArtificialAnlys
Date
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Why it matters
Databricks leads on speed (394.6 t/s) and latency (6.08s) while DeepInfra/CoreWeave undercut on price ($0.49/M tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →), a 757% speed gap and 5.2x price gap that should shape which provider you pick for GLM-5.2 workloads.
Key quotes
“For output speed, the top providers are Makora (NVFP4) (303.8 t/s), Baseten (FAST) (195.5 t/s), and CoreWeave (191.2 t/s). Speed varies significantly across providers, with a 831% difference between the fastest and slowest.”
ArtificialAnlys
“For latency, Makora (NVFP4) (7.50s), Nebius (FP4) (11.65s), and Baseten (FAST) (11.90s) offer the lowest time to first answer token.”
ArtificialAnlys
“For pricing, DeepInfra (FP4) (0.49), CoreWeave (0.49), and GMI (FP8) (0.59) offer the lowest blended prices per 1M tokens. Prices vary up to 5.2x across providers.”
ArtificialAnlys
“Composite measure of how much of a model's accuracy a given provider endpoint preserves, from re-running BFCL v4-500, HLE-250 and AA-LCR-25 against that endpoint. Where a self-hosted reference endpoint exists, scores are expressed as a percentage of that reference (100 = matches reference)”