← All IntelIntel / article
Dust: Pretraining Transformers Without Backpropagation
- Source
- qlabs.sh
- Author
- E-Reverance
- Date
Why it matters
Shows a backprop-free route to training language models whose gradient estimates align better as population grows. It points to a possible compute-for-search tradeoff in future .
Terms in this piece · Glossary
- pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Read the source qlabs.sh
Recommended reads
 articlePretraining and adapting a language model on a dependency-free stack: GPT-2 124M from random weights, reproduced against llm.c, and a clinical adapter for Qwen3-0.6BThang Tran (CloudKites AI Lab, New South Wales, Australia), Lan Dang (Monash Business School, Monash University, Victoria, Australia)
 articleExploring Diffusion Transformer Designs Via GraftingLiquid AI
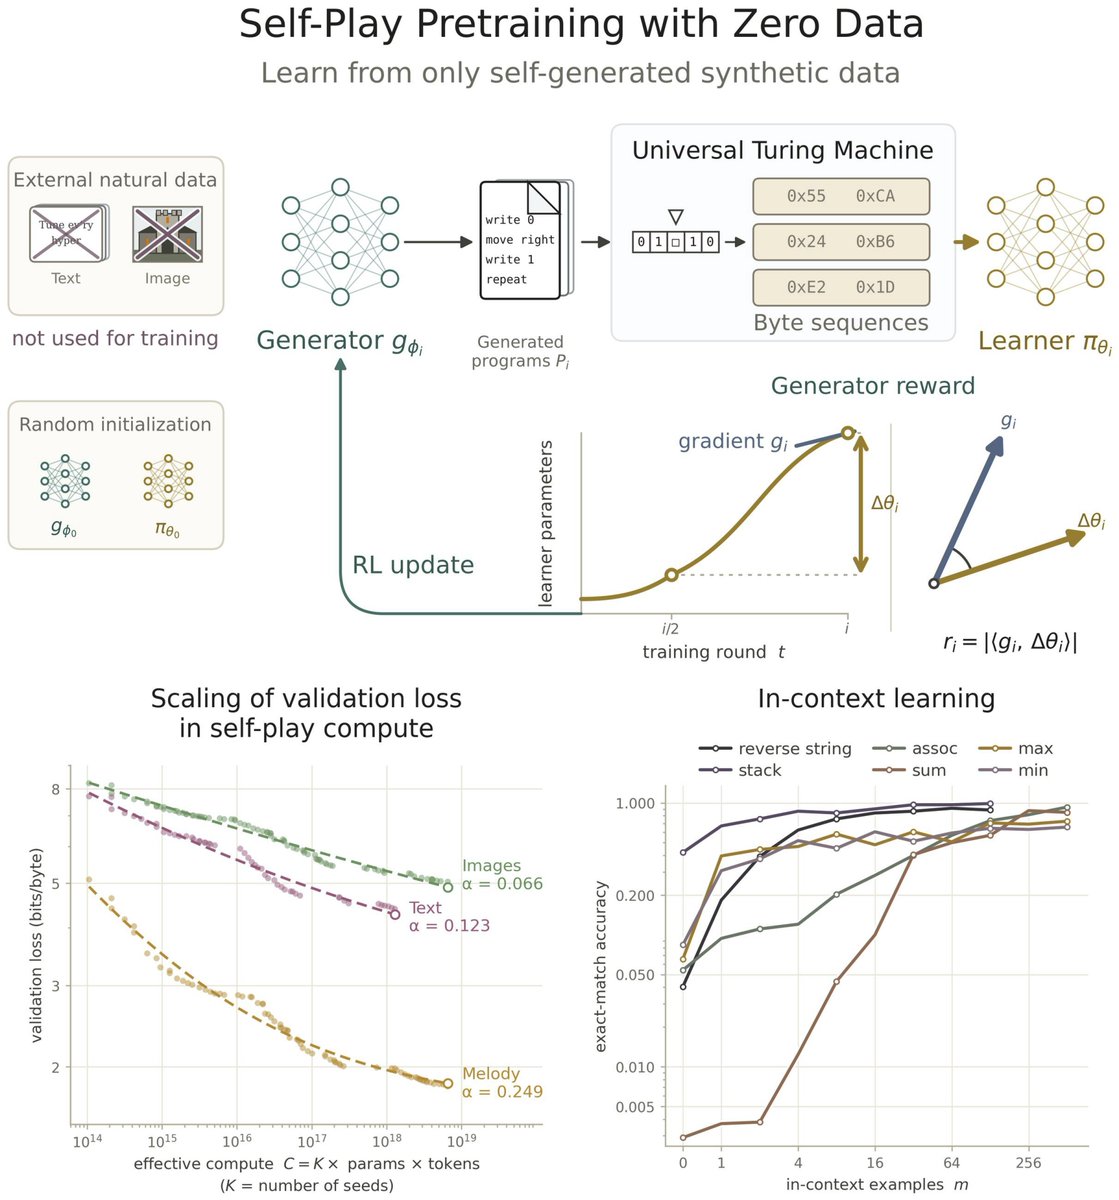 postStanford Researchers Test Pretraining a Model on Self-Generated Data AloneStanford AI Lab
Comments
Checking sign-in…
Loading comments…