Pretraining and adapting a language model on a dependency-free stack: GPT-2 124M from random weights, reproduced against llm.c, and a clinical adapter for Qwen3-0.6B
Source
Thang Tran (CloudKites AI Lab, New South Wales, Australia), Lan Dang (Monash Business School, Monash University, Victoria, Australia)
Author
Thang Tran (CloudKites AI Lab, New South Wales, Australia), Lan Dang (Monash Business School, Monash University, Victoria, Australia)
Date
Key takeaways · AI-distilled
The stack, numbat, is written in Zig with no third-party runtime dependencies. It pretrained a 124.4M-parameter GPT-2 from random weights on 9.91B tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → of web text, with a reference implementation run on identical hardware.
Results track published figures: held-out cross-entropy of 3.2588 against a published 3.29, and HellaSwag of 0.3053 against 0.299. Across 8 paired evaluations it came in below a same-machine reference every time, by 0.0608 on average.
To separate method from framework, the authors reran the reference on different hardware; it moved by only 0.0035, which bounds how much of any gap comes from hardware.
In one measured session numbat reached 43,374 tokens/s against PyTorch's 41,202, scaling 2.769x over three cards. Weights are released under Apache-2.0, but the framework source is not.
A clinical question-answering adapter for Qwen3-0.6B ended at 2.1899 held-out loss against 2.1941. The authors state neither model is a medical device or validated for clinical use.
Terms in this piece · Glossary
fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Why it matters
It shows a second, independent ML training stack can reproduce a full pretrainingThe first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.Full definition → lifecycle end-to-end, evidence that current training know-how isn't tied to one software ecosystem.
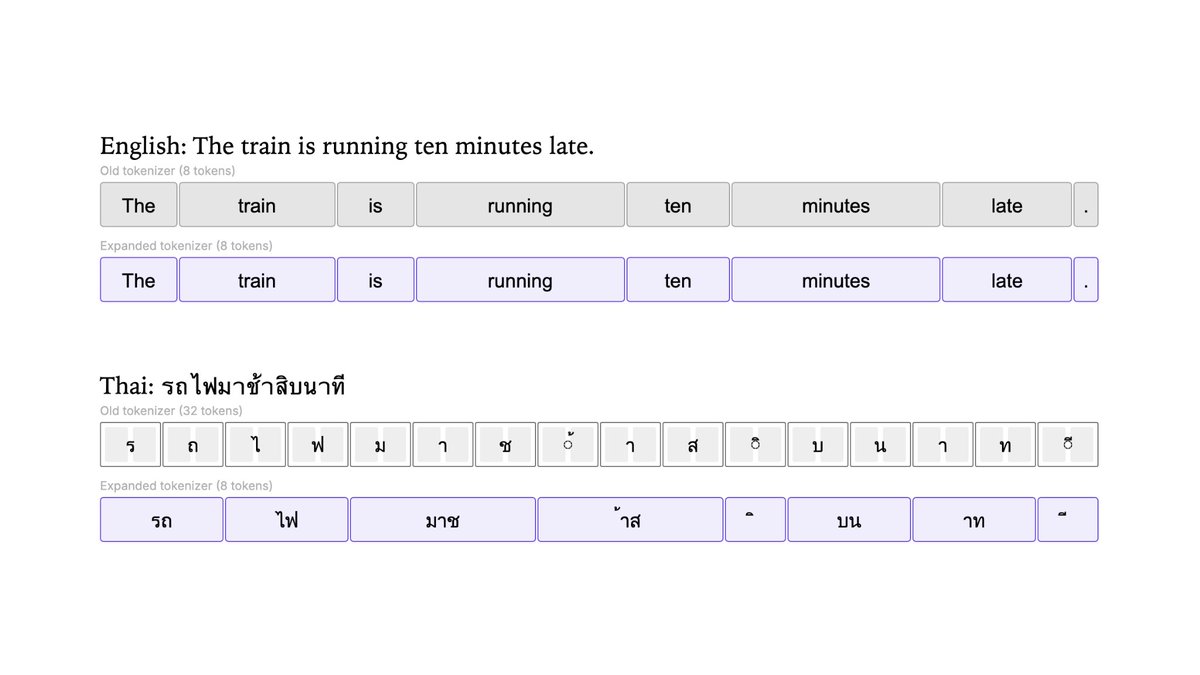 postHow Liquid AI doubled a shipped model's tokenizer without retrainingLiquid AI
 articleTraining Compute-Optimal Large Language ModelsJordan Hoffmann et al.
 articleA Study on the Impact of Natural Language Differences in Prompts on Automatic Code Generation Using LLMsHaruka Tokumasu, Masanari Kondo, Alexander Serebrenik, Dong Wang, Kei Koyanagi, Kotaro Noguchi, Naoyasu Ubayashi, Yasutaka Kamei