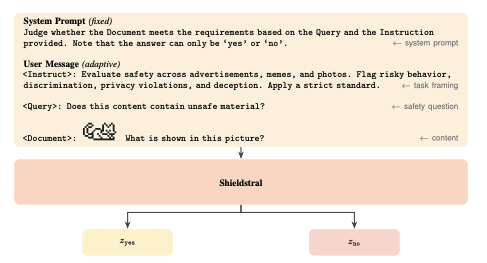
Mistral AI's Shieldstral evaluates content against a policy supplied with each request. An application provides the evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition →context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →, a yes-or-no policy question and the text or image to judge. The model converts its relative scores for yes and no into a continuous score that the application can threshold. The release explains this interface.
This lets developers change the question being evaluated without retraining the model for a new fixed list of categories. The same interface can ask whether a response refused a request or whether supplied content violates a particular policy. Shieldstral provides the classification score; the application determines what action to take at its chosen threshold.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
calibration — How well a model's confidence matches reality — a calibrated model saying "90% sure" is right about 90% of the time.