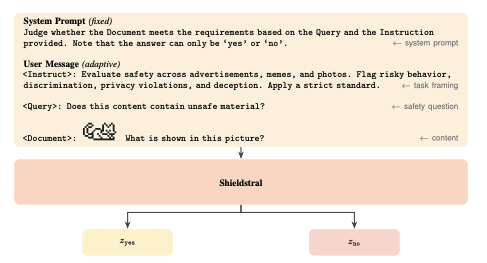
Mistral AI's Shieldstral lets an application express a moderation policy as a plain-language question. The application supplies the content and evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition →context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →, and the model produces a score from its yes-or-no prediction. According to the launch article, the same interface handles text and images, allowing policies to change through the request without retraining the model.
Mistral released the weights under Apache 2.0 and says the model runs on a single 16GB GPU. That gives developers a deployable classifier whose policy can be specified by the application.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.