OlmoEarth v1.1 gets 3x cheaper by spending fewer tokens per image
- Source
- x.com
- Date

Today we’re releasing OlmoEarth v1.1. It’s 3x cheaper to run than v1 while delivering the same state-of-the-art performance—and fully open. 🧵

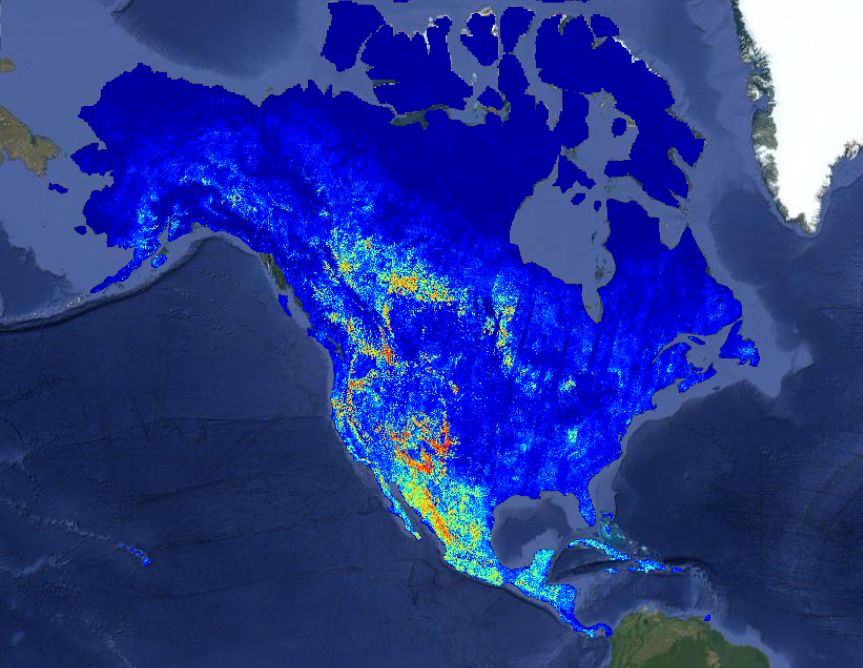
Compute is the highest cost when running OlmoEarth at hundreds of thousands of square kilometers. Partners use v1 today for mangrove tracking, forest-loss classification, & country-scale crop-type mapping. v1.1 makes that work more sustainable.
Where the savings come from: we feed the model about 3x fewer tokens per Sentinel-2 input. Since compute scales quadratically with token count, even modest reductions compound into real efficiency gains.
Done naively, this hurts accuracy noticeably. Recovering it took changes to how we pretrain the model. → Full details in our tech report: https://t.co/wwCYuMGZ2I

Context
Ai2's OlmoEarth v1.1 reduces the computation needed to process satellite imagery by shortening the model's input sequence. For each image patch and time step, it combines channels from three resolution groups into one input representation. Simply merging them reduced accuracy, so the team also changed while keeping the underlying training dataset fixed. The release explanation reports compute costs up to three times lower with broadly similar performance across its tested tasks, while acknowledging some regressions. The savings therefore depend on whether the revised model preserves performance for the intended task.
- pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…