Existing coding benchmarks stop at the first working version. We are releasing Vibe Code Bench 1-100 today, to measure what comes next.
This benchmark asks if models can handle a large number of modifications to a product, without breaking what already works.
Shows that iterative, non-regressive coding, not first-pass code generation, is the harder unsolved problem for coding agents, with concrete pass rates and cost figures across current frontier models.


 articleVibe Coding: Practice, Performance, Productivity, and Risk -A State-of-the-Art ReviewDominik L. Michels, Mutaz Abu Ghazaleh, Francois Lazzari, Nabil Kassem, Jonathan Klein
 videoBenchmarking Coding Agents on New vs Legacy Codebases — Denys Linkov, WisedocsAI Engineer
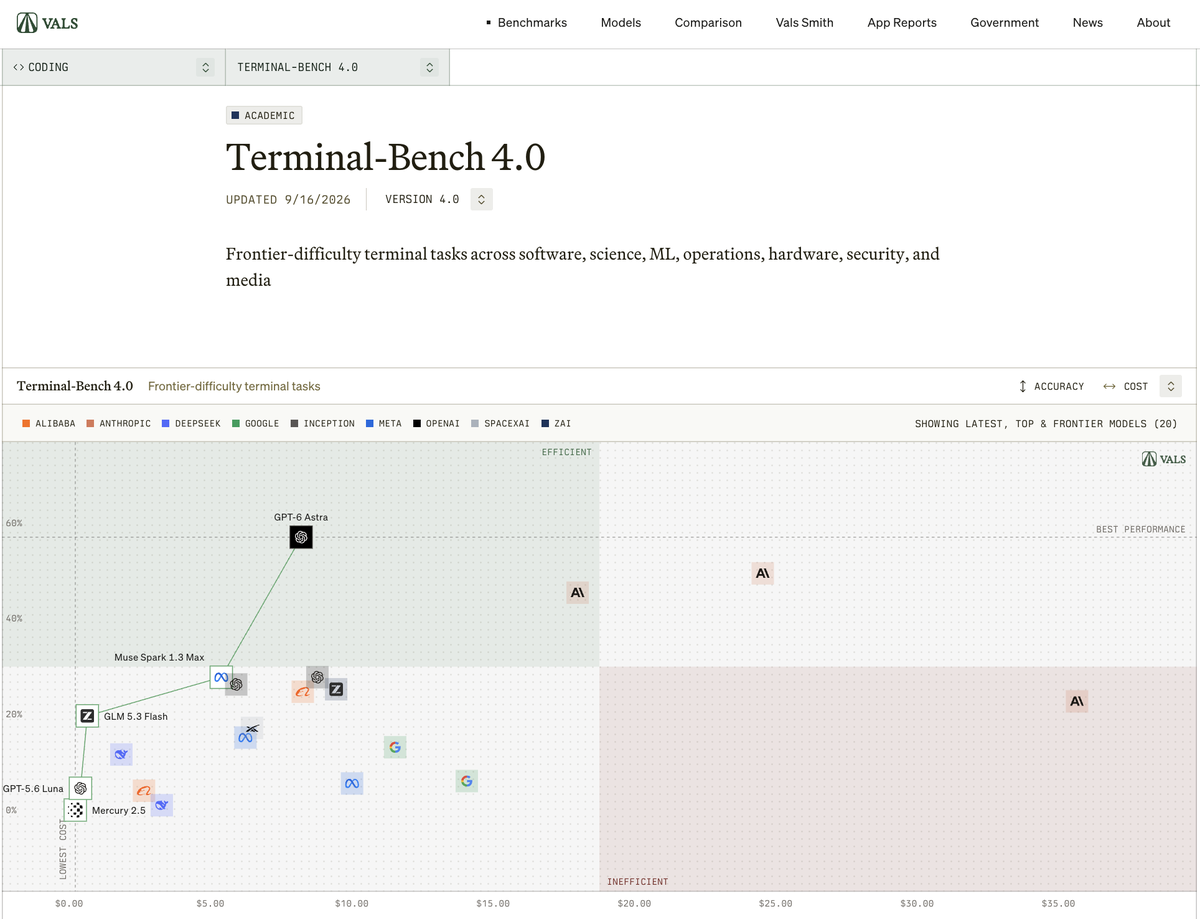 postVals AI Launches Terminal-Bench 4.0 With Stricter Pass/Fail GradingVals AI