Ori Eval
- Source
- openrouter.ai
- Author
- OpenRouter
- Date
Context
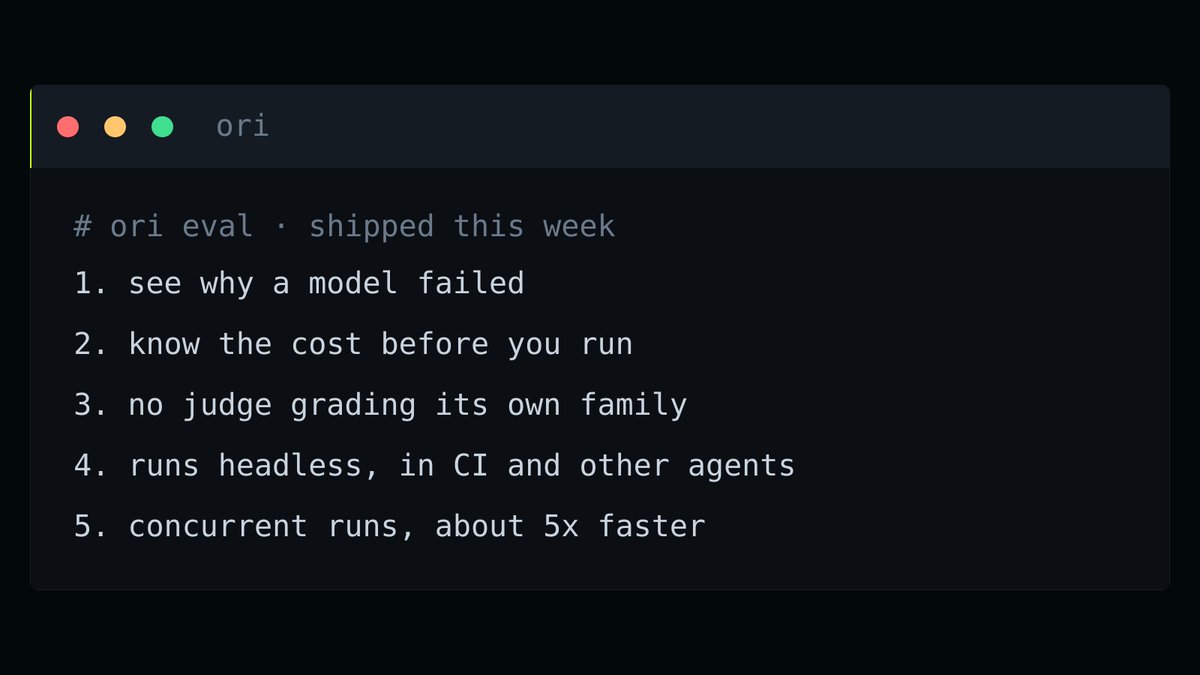
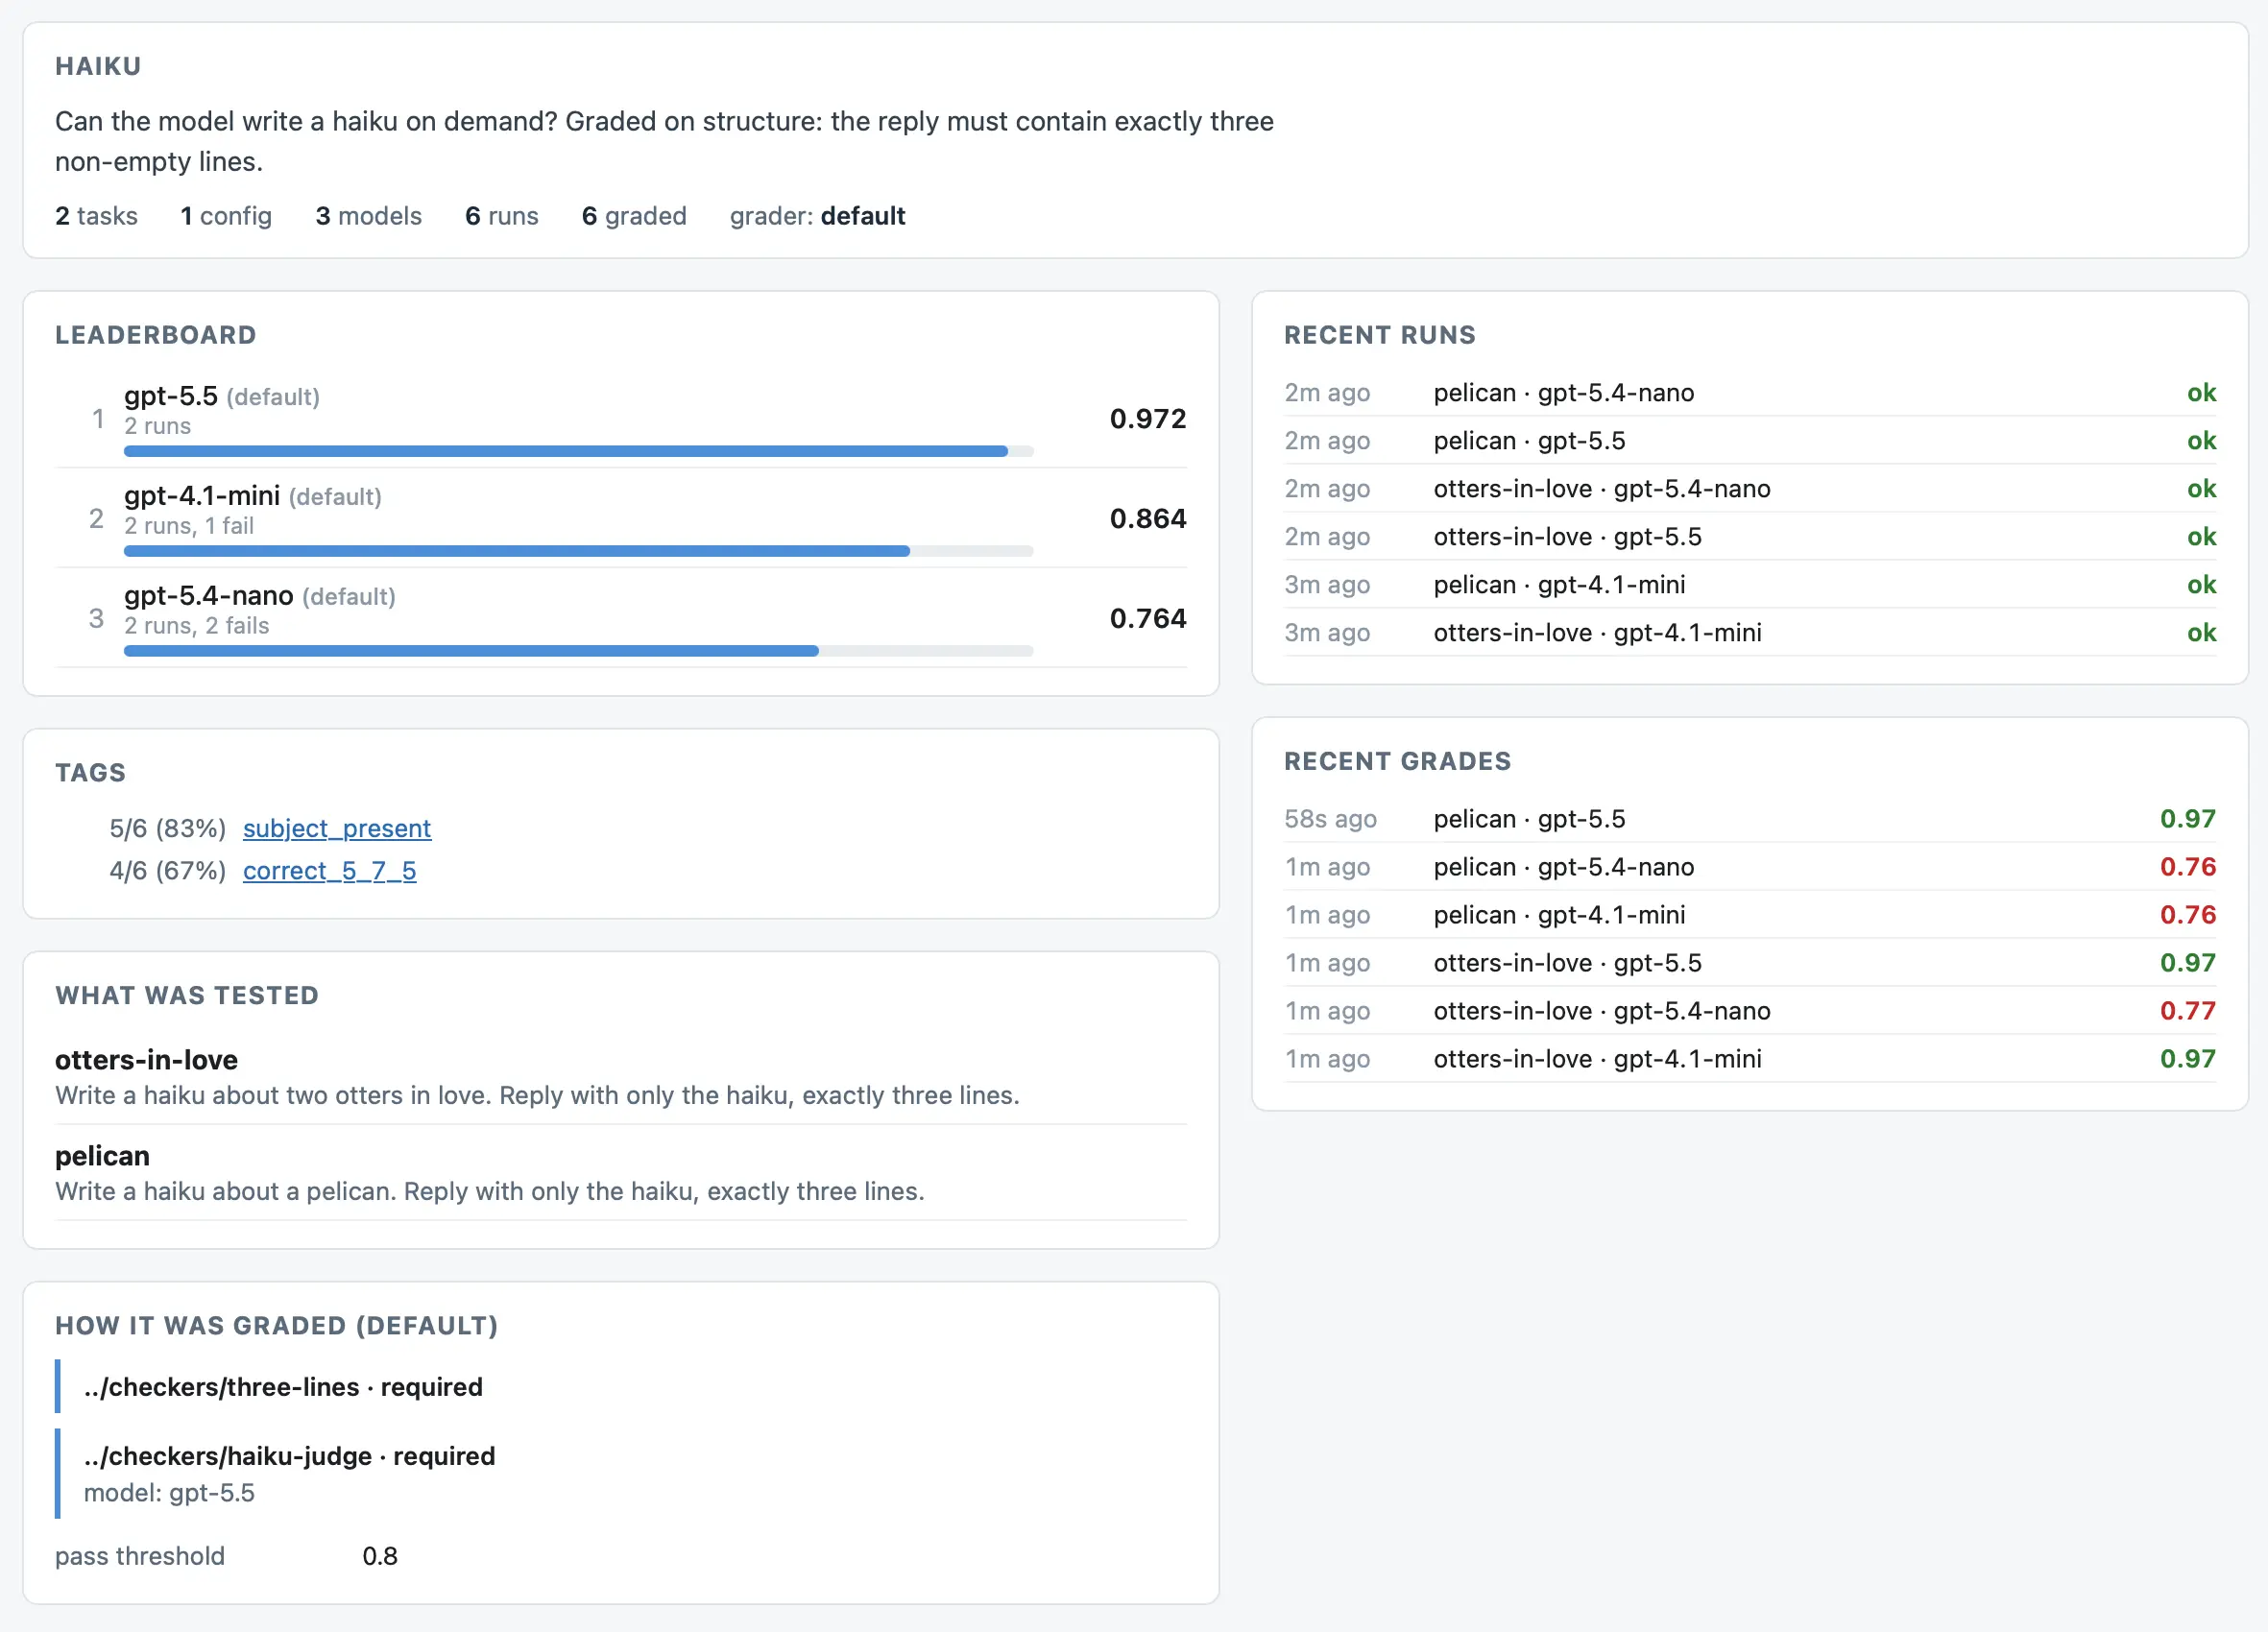
OpenRouter's Ori turns an application's requirements into repeatable tests for its AI behavior, so a team can compare candidate models on its own use case rather than on a general . It asks what matters, finds model calls in the code and writes evaluation files using the application's prompts and data, then runs the candidate models against them. Tests can check whether required tools were called, whether forbidden tools were avoided and how an answer scores against criteria assessed by another model. The announcement illustrates this with a support that should look up an order before issuing a refund. Saving that requirement as a test lets teams check it again after changing the agent or its model. Ori Eval announcement.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.




Checking sign-in…
Loading comments…