Making Knowledge Distillation Cheap Enough to Run at Scale
Source
huggingface.co
Date
Why it matters
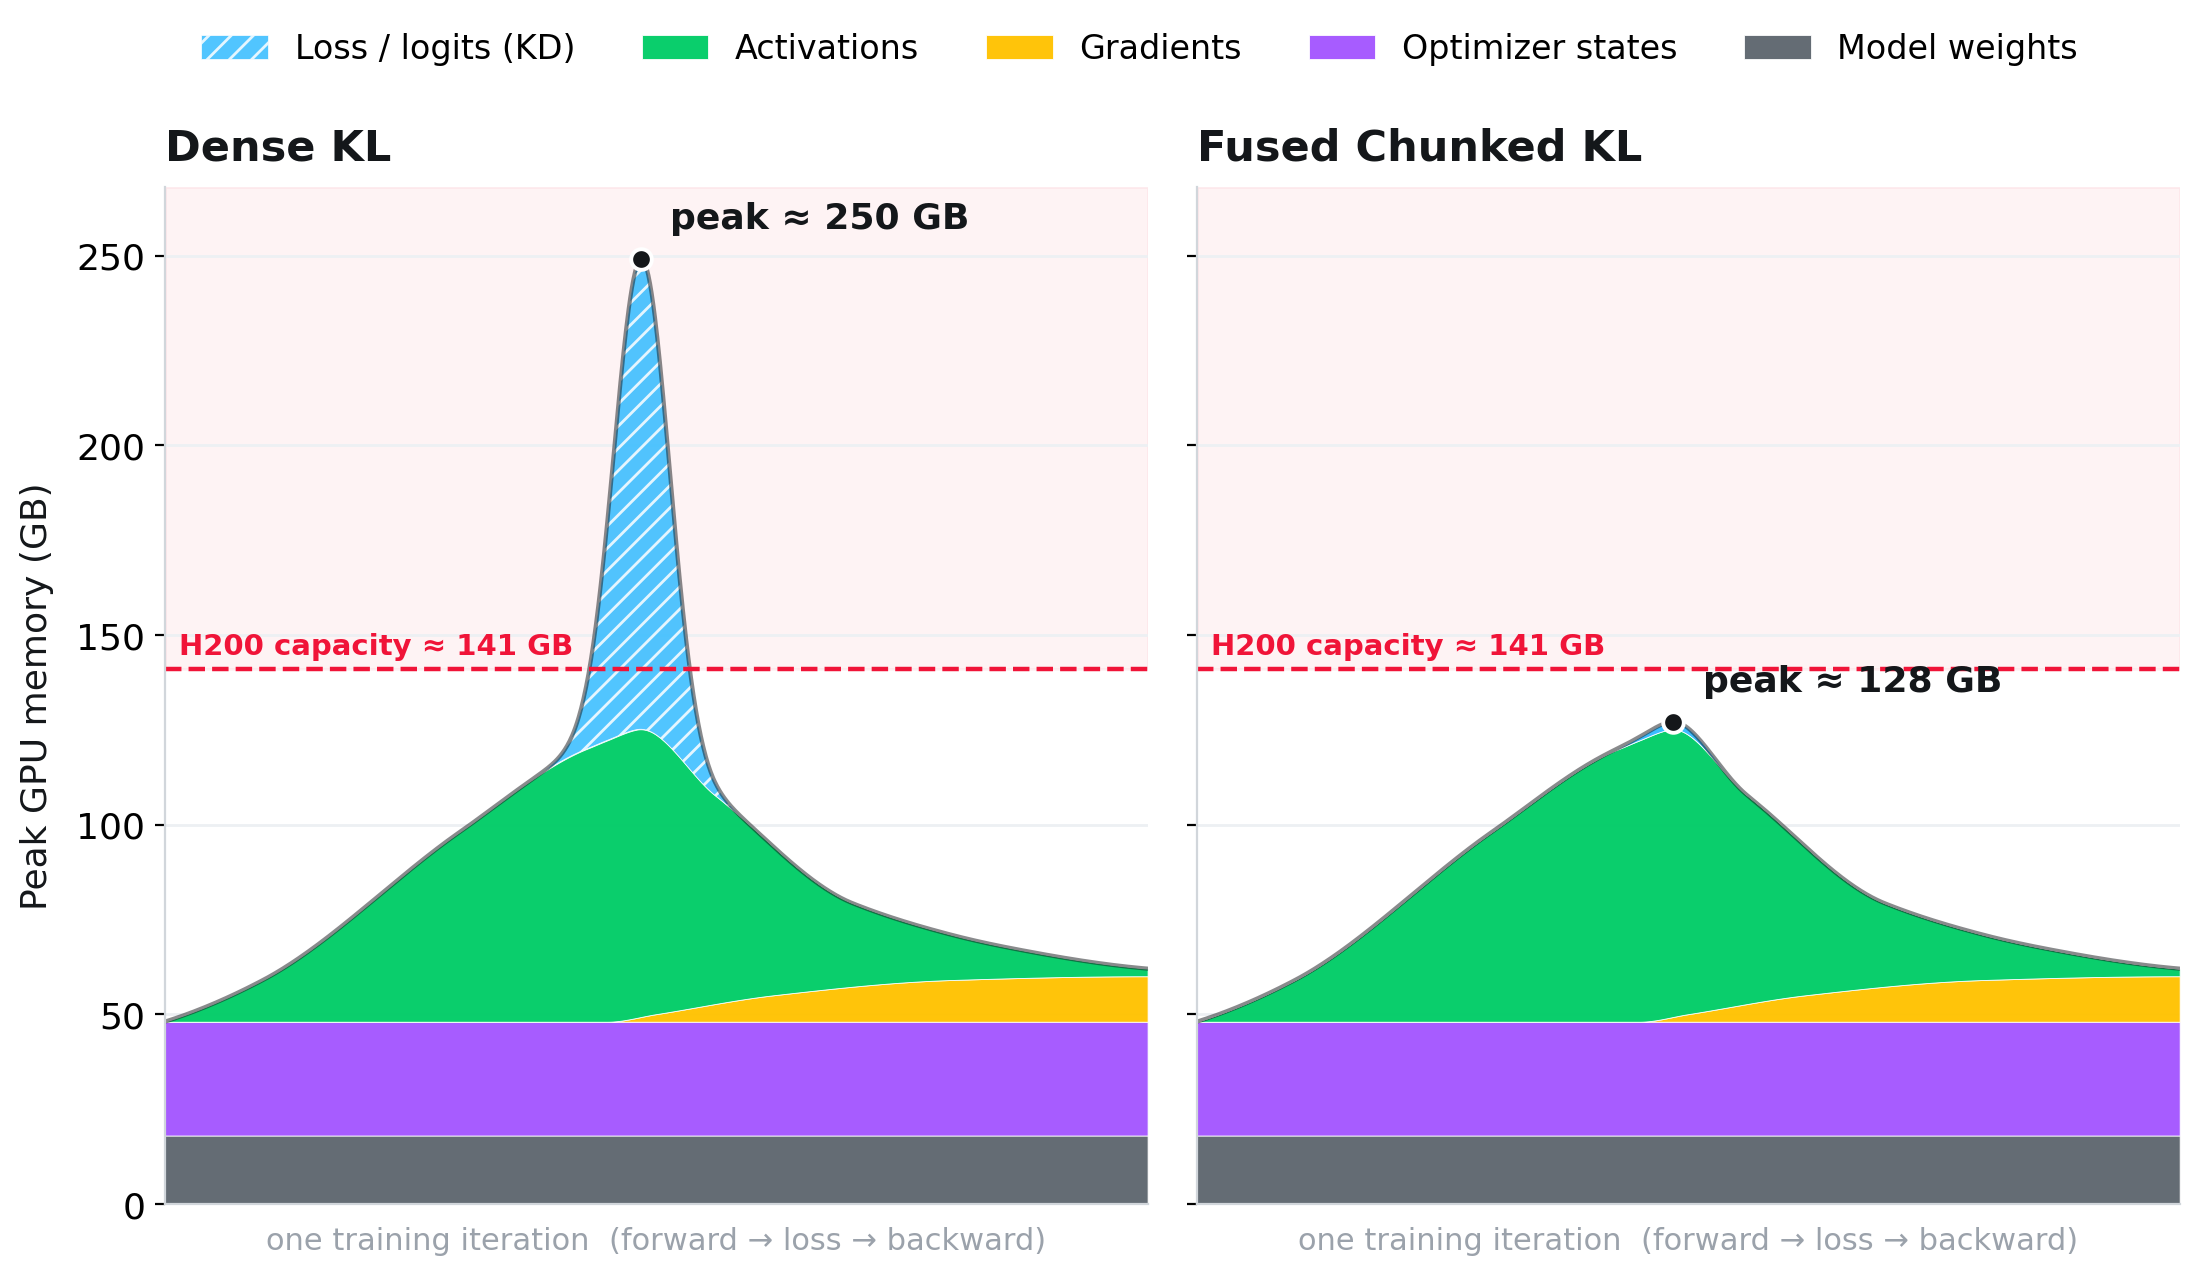
Caching the teacher's top-K logits once removes it from memory during student training, and a fused chunked KL loss never materializes the vocabulary-by-sequence tensor — enough to bring long-context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →distillationTraining a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.Full definition → healing onto a single GPU.
Terms in this piece · Glossary
distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.