A 440MB translation model that runs fully offline on a phone
- Source
- x.com
- Date

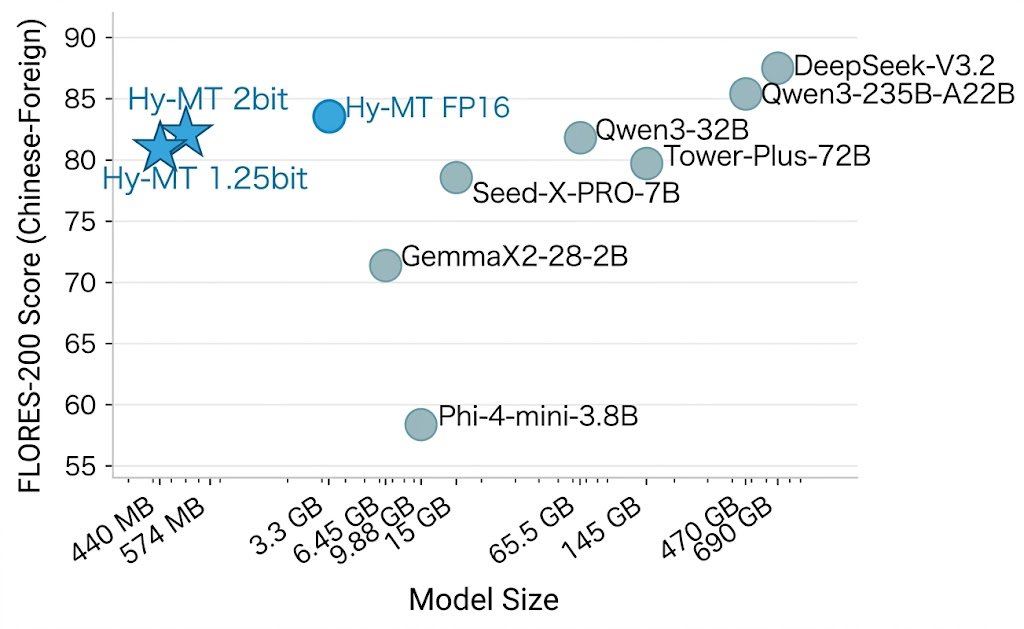
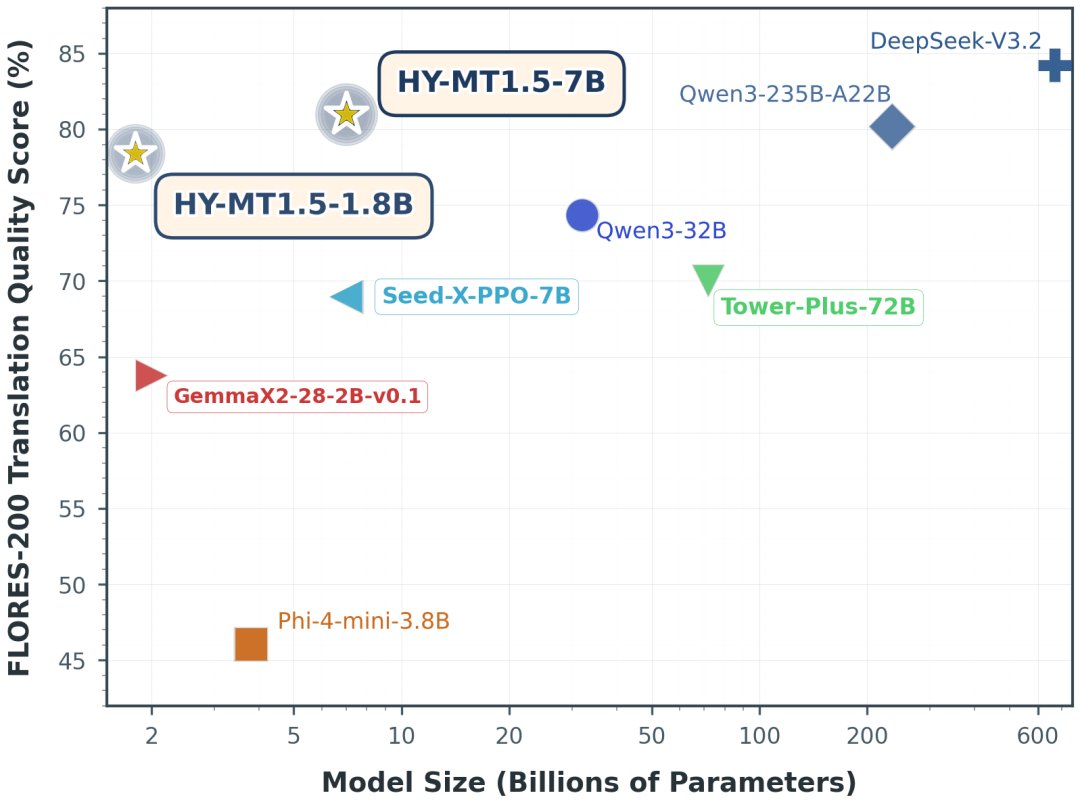
We're open-sourcing Hy-MT1.5-1.8B-1.25bit — a 440MB translation model that runs fully offline on your phone, supports 33 languages, and outperforms Google Translate. At 1.8B parameters, it matches commercial translation APIs and 235B-scale models on standard benchmarks. By quantizing to 1.25-bit, memory drops from 3.3GB (FP16) to 440MB — 25% smaller and ~10% faster than prior 1.67-bit approaches, with no accuracy loss. Covers 33 languages, 5 dialects, and 1,056 translation directions including minority languages like Tibetan and Mongolian. Our translation model has won 30 first-place rankings in international MT competitions and is already deployed across multiple Tencent products.🏆 📲Demo APK (Android): https://t.co/DbcwLBe6vw 🤗Hugging Face:: https://t.co/NgXKeNZz4L 🔗GitHub: https://t.co/b6DqGKDelf 📄Paper:


Context
Tencent's compressed HY-MT1.5 translator is reported at 440 MB, down from 3.3 GB at 16-bit precision. The model card explains the packing scheme behind the reduction: for each group of four weights, the method keeps three as positive or negative values and sets the fourth to zero. The group is encoded in five bits, producing the advertised average of 1.25 bits per weight.
The release includes an Android demonstration for translation without an internet connection. That makes local translation usable where connectivity is unavailable. The 440 MB figure describes the compressed model's size; it is not the total memory consumed by the phone application.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
 postExplorationBench tests how models explore, with exactly verifiable grading
 postHy Image3.5 preview is live. 🚀 Professional-grade image generation, +30% win…
 postTencent Hunyuan's EvolveScaler trips up frontier models on evolving facts
 postTencent Hunyuan open-sources AuK, a unified speech generation and editing model
Checking sign-in…
Loading comments…