Verification has emerged as a new scaling axis 🚀
LLM-as-a-Verifier shows that scaling verification can push performance to SOTA across Terminal-Bench V2, SWE-Bench Verified, RoboRewardBench, and MedAgentBench.
Its fine-grained feedback can also serve as a proxy for estimating task progress and improve RL sample efficiency!
Congrats to @jackyk02 @shululi256 @pranav_atreya @liu_yuejiang @jyx_su @chelseabfinn @drmapavone @istoica05 @Azaliamirh
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
Why it matters
Scaling up verification, not just generation, pushed AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → performance to state of the art across four benchmarks, and its fine-grained feedback also improved RL sample efficiency.

 articleThe reach of a verification tool decides its value: A controlled study of verification surface, artifact quality, and cost in AI coding agentsAchint Mehta
 articleNVIDIA Vera Rubin and Blackwell Set a New Standard for Agentic AI Performance per WattElizabeth Goodman
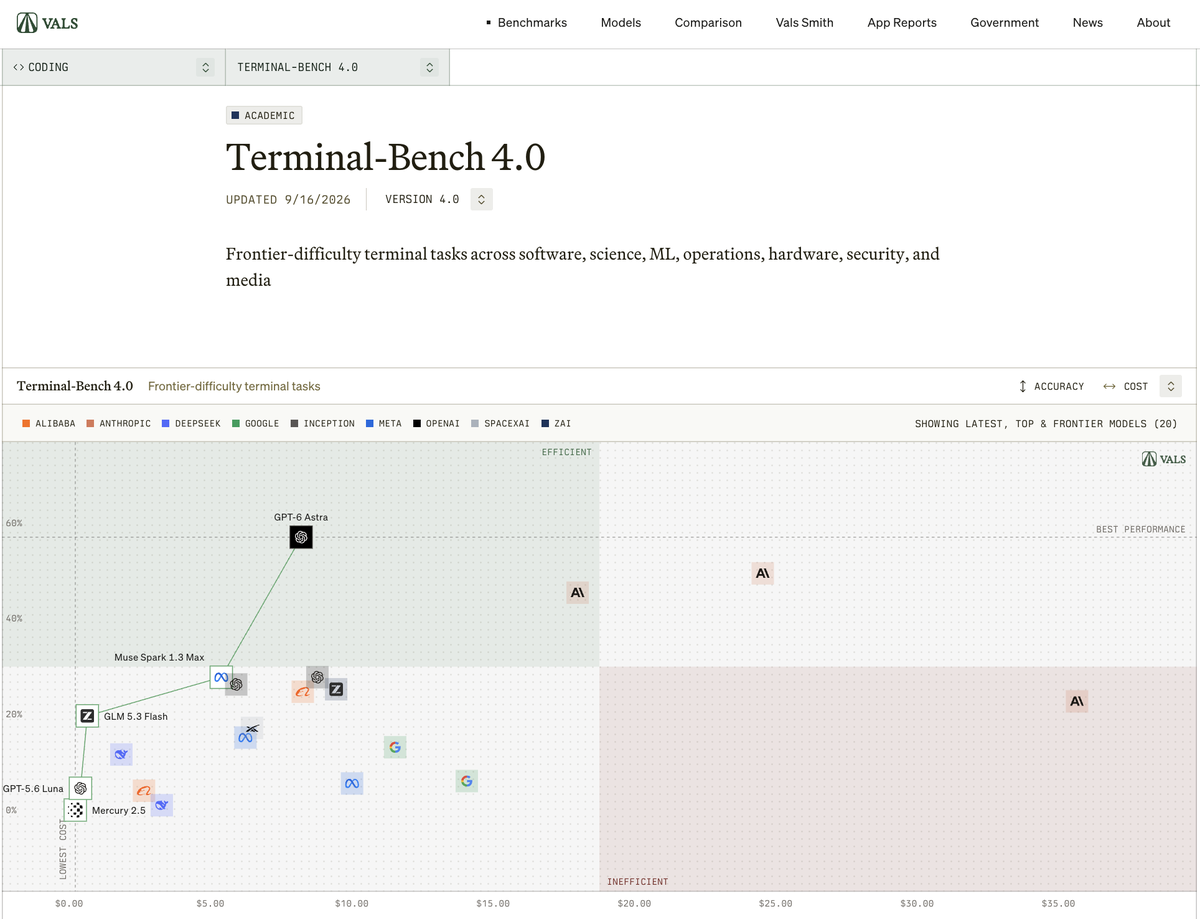 postVals AI Launches Terminal-Bench 4.0 With Stricter Pass/Fail GradingVals AI