AMD deprecates its RIXL fork and upstreams into NVIDIA's NIXL
- Source
- x.com
- Date

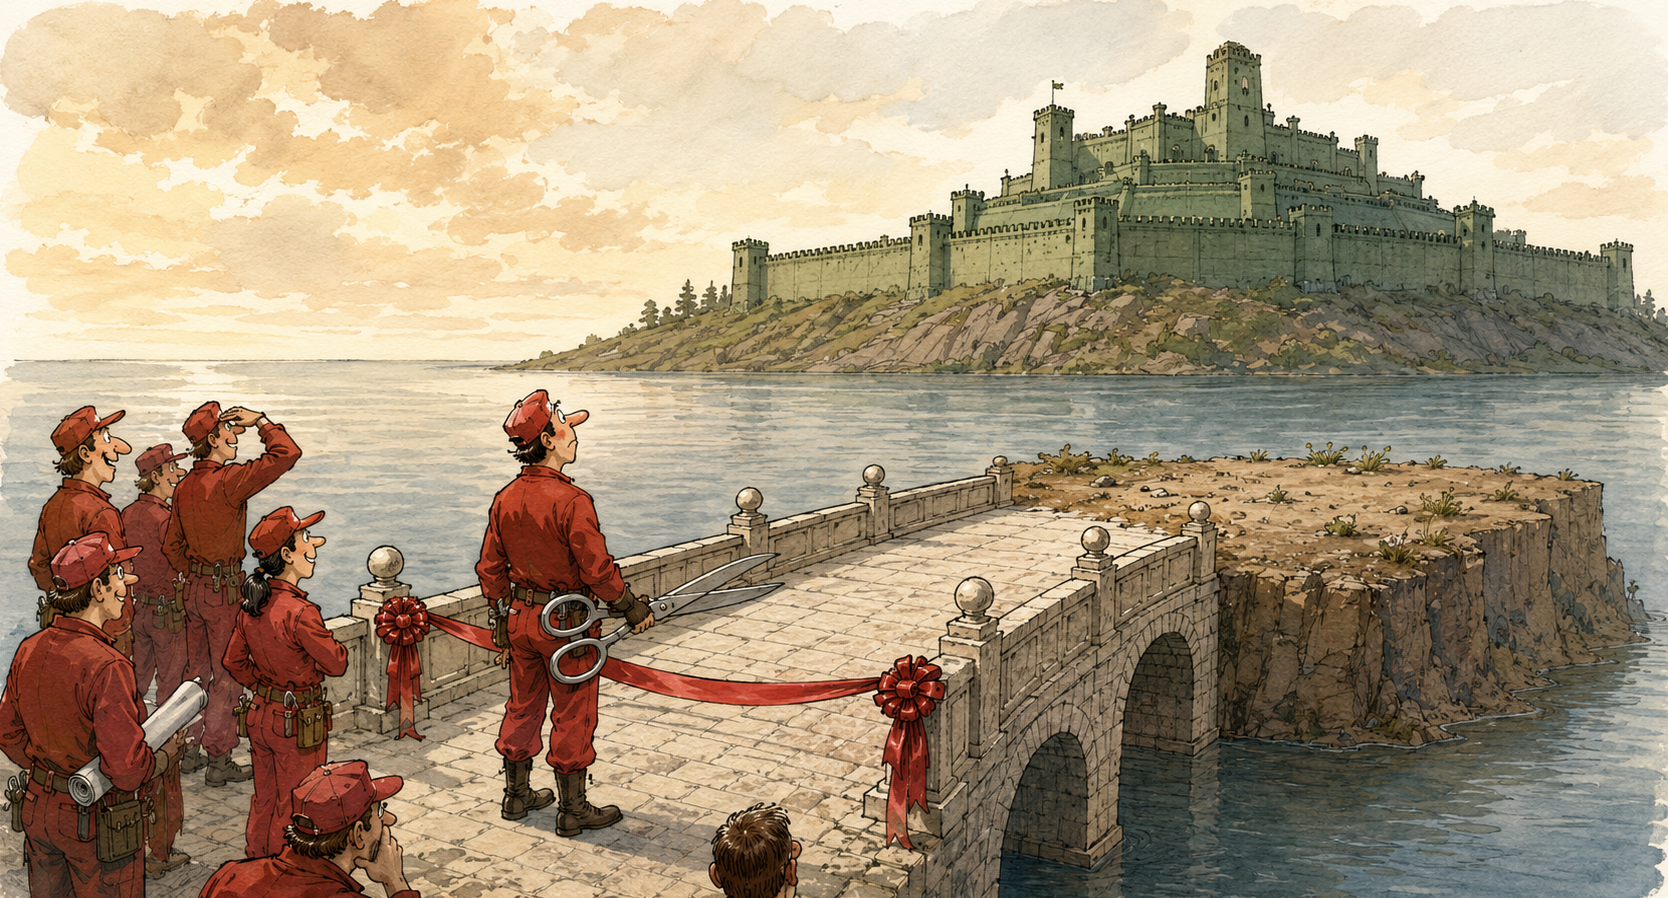
For the past 10 years, NVIDIA prevented AMD from upstreaming its code into NVIDIA’s libraries, but over the past 24 months, SemiAnalysis has squashed the beef, and NVIDIA has started accepting AMD PRs into the ultra-important NIXL Inference communication library. We explain below👇️ 1/6🧵

Context
AMD's support for its Instinct data-center GPUs now lives inside NIXL itself instead of in a separate AMD copy of the code. NIXL is an open-source library for fast point-to-point data transfers in AI systems, such as NVIDIA's Dynamo framework, and it hides the differences between CPU memory, GPU memory and storage such as files and object stores. AMD had maintained RIXL, a port of NIXL to its ROCm software stack. That repository now marks itself deprecated and tells users to switch to NIXL, because AMD GPU support has been contributed there.
The contribution is pull request 1642, submitted in May by an engineer committing from an AMD email address and merged on June 4, 2026. It adds an experimental build mode, off by default, that compiles NIXL with AMD's ROCm/HIP toolchain for the MI300X, MI325X, MI350X and MI355X, leaving ordinary NVIDIA builds unchanged. On an AMD build, several backends work, including the UCX transport, but others are switched off: GPUDirect Storage has no ROCm equivalent, GPUNetIO depends on NVIDIA's networking stack, and the libfabric backend still needs code changes. Testing in the pull request covered builds, a check that NVIDIA builds were unchanged, and single-machine transfer smoke tests on AMD GPUs, with throughput the author described as not optimized.
The practical change is one shared codebase, not equal support. An AMD deployment gets a subset of NIXL's backends under an experimental label, and the pull request lists further work still to come. SemiAnalysis's thread presents the merge as the end of a decade in which, by its account, NVIDIA kept AMD code out of its libraries, and credits its own efforts over the past two years for the change. Neither repository addresses that history, so that part rests on SemiAnalysis's word.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…