AMD MI355X vLLM HAS BEATEN B200 vLLM ON KIMI K2.5 (THE SAME MODEL ARCH AS XAI…
- Source
- x.com
- Date

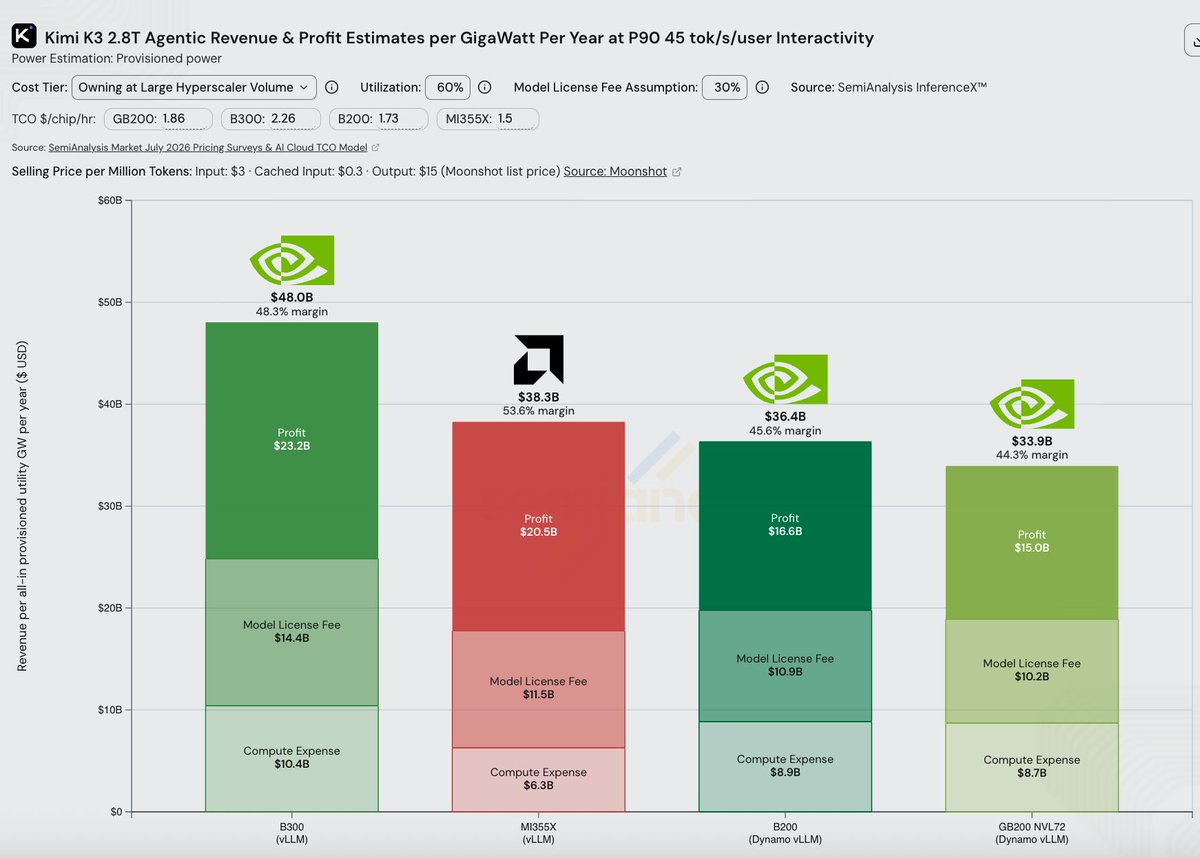
AMD MI355X vLLM HAS BEATEN B200 vLLM ON KIMI K2.5 (THE SAME MODEL ARCH AS XAI CURSOR COMPOSER 2.5)🚀🚨 This uses upstream AMD kernels from the @GPU_MODE community. We explain below 👇 1/6🧵

Context
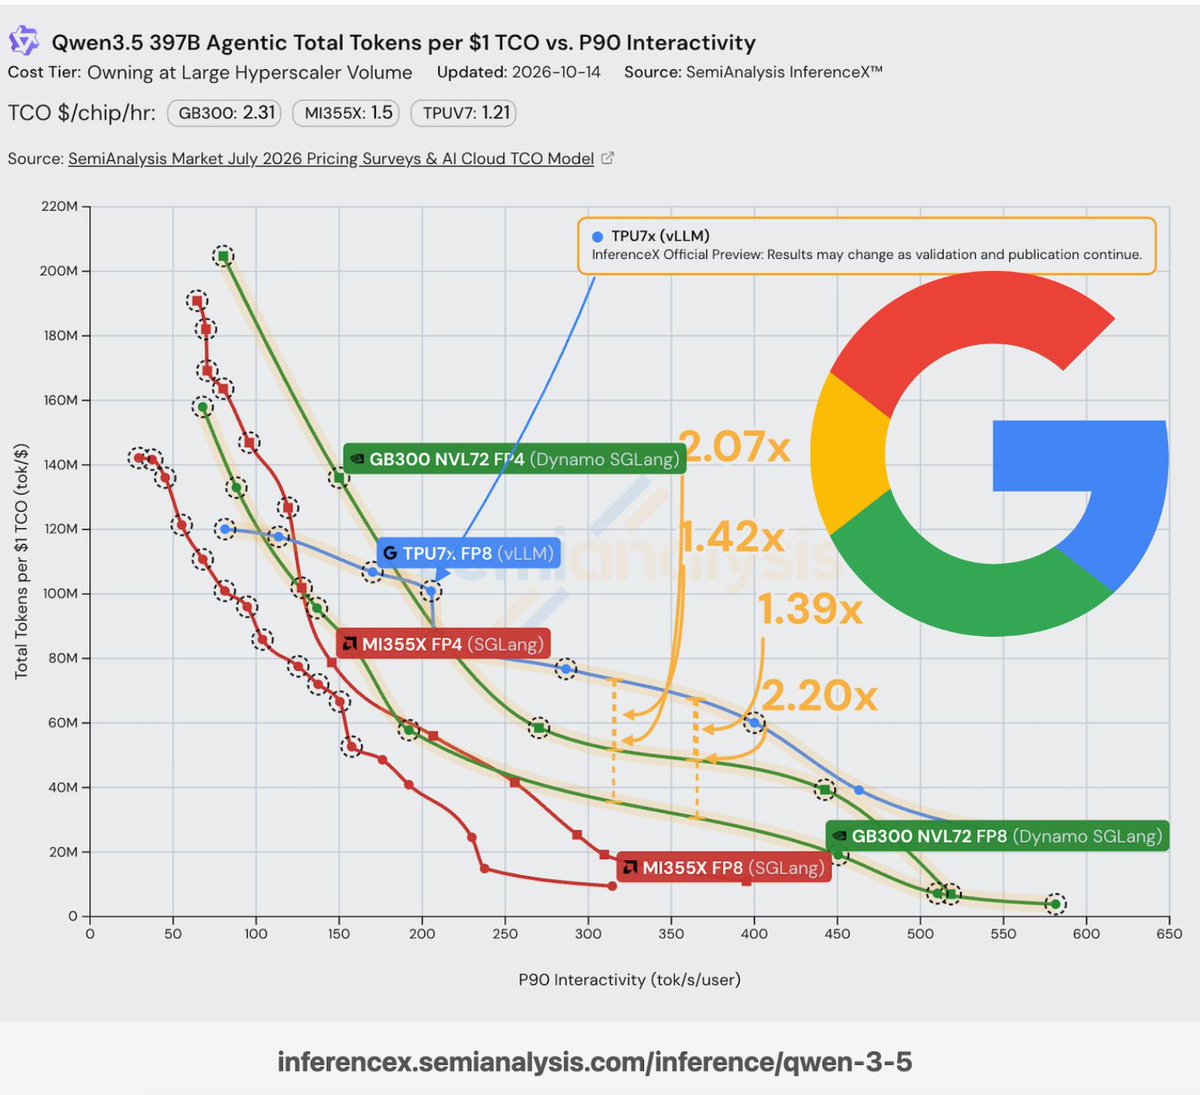
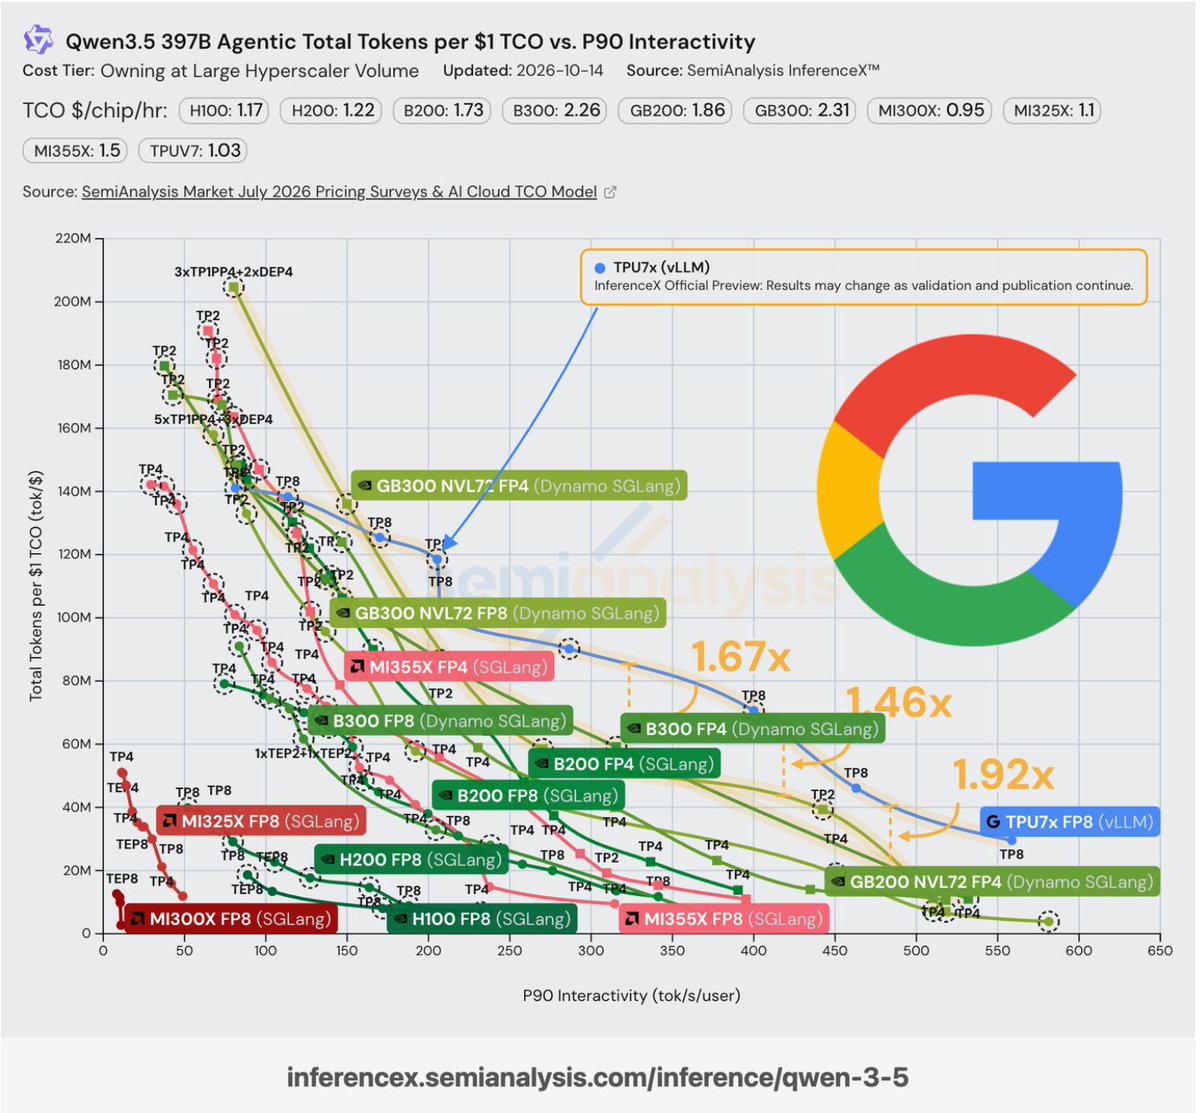
SemiAnalysis's MI355X-versus-B200 post is best understood as a comparison of cost at a chosen response speed. Its attached chart plots modeled ownership cost per million total text against tokens generated per second for each user. The July 30 curves put AMD's MI355X running vLLM below NVIDIA's B200 across much of their overlapping speed range, while the B200 curve extends to higher per-user speeds. The chart specifies FP4 precision, 8,000 input tokens and 1,000 output tokens. Its cost advantage therefore depends on the response speed being compared and the stated ownership assumptions.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…