Fable 5.2 tops VIALS-AA by out-tooling OpenAI models
- Source
- x.com
- Date

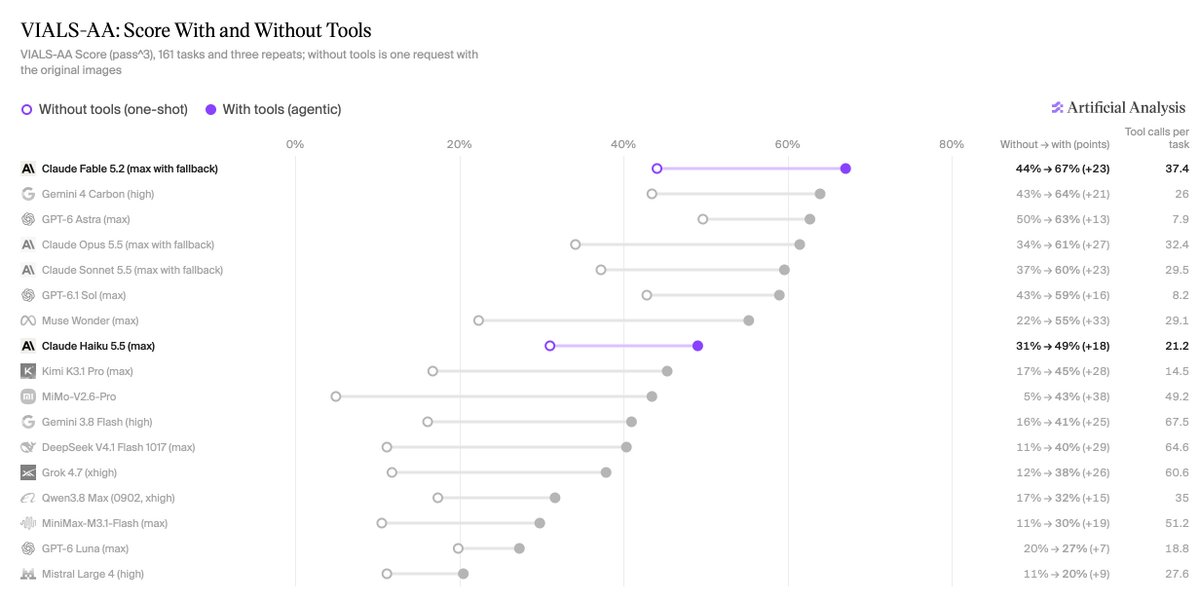
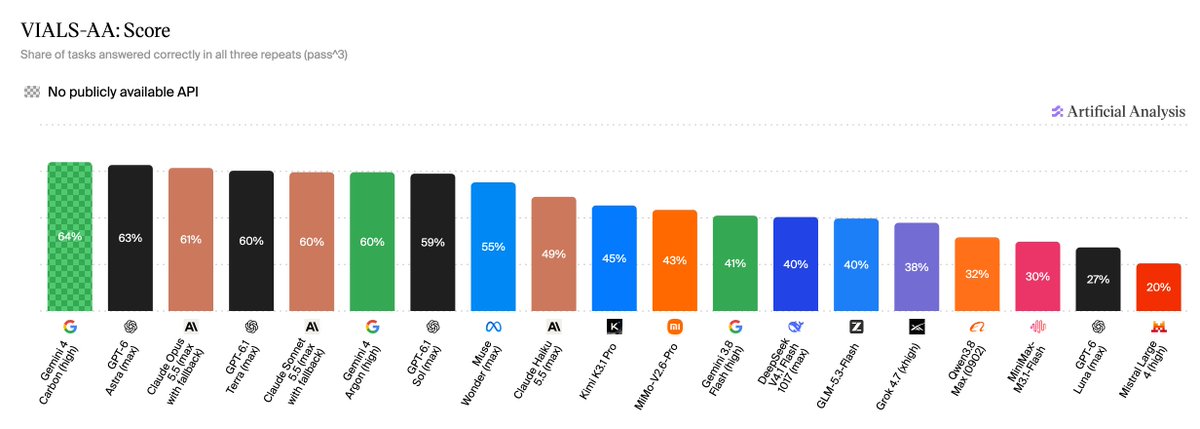
Claude Fable 5.2 leads scientific visual reasoning benchmark VIALS-AA; it makes more tool calls than any other Anthropic model, unlike OpenAI models which make fewer as they get smarter VIALS-AA is our implementation of @joinHandshakeAI’s VIALS benchmark for visual reasoning in life sciences research, across artifacts such as gel blots, plasmid maps, and phylogenies. Claude Fable 5.2 (max with fallback) scores 67% on VIALS-AA, ahead of Gemini 4 Carbon (high) at 64% and GPT-6 Astra (max) at 63%. Fable averages ~37 tool calls per task, while Astra averages ~8, the fewest of any model we’ve tested. On turn 4 of this protein interaction task, Fable creates crops and asks to view them. On turn 10, it builds a color mask by thresholding color channels. On turn 17, it fits a circle to each arc and unrolls the arc into a straight strip. On turn 31, it counts the bars as peaks in an intensity profile. And on turn 41, it maps every detected spoke back on the original image to check its work. Fable batches calls on 28 of its 51 turns, averaging 1.75 tool calls per turn, compared with 1.12 for Sonnet 5.5.

Shows that top agentic visual-reasoning scores come from heavy (about 37 calls per task for Fable 5.2 versus about 8 for GPT-6 Astra), which drives cost. design affects results as much as the model.
- tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
Checking sign-in…
Loading comments…