← All IntelIntel / article
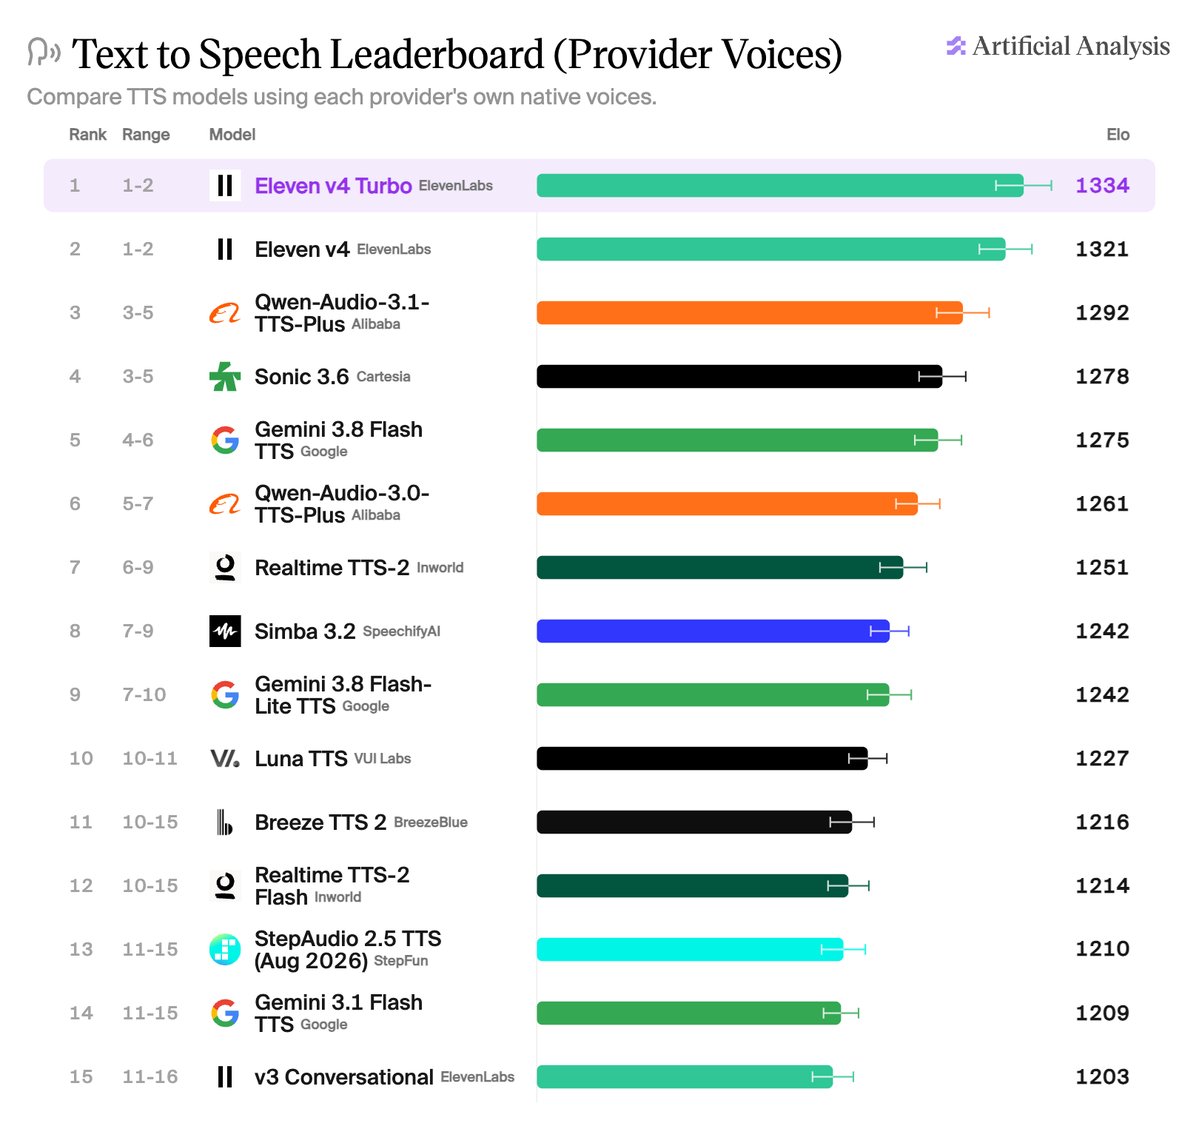
Eleven V4 Turbo In Elevenagents
- Source
- elevenlabs.io
- Author
- ElevenLabs editorial sitemap
- Date
Context
ElevenLabs has integrated Eleven v4 Turbo, the low-latency member of its v4 speech family, into ElevenAgents. Its announcement describes speech delivery that adjusts during a call, such as a more reassuring tone when a caller is frustrated. The model works alongside the platform's transcription and turn-taking models, combining speech generation with the systems that listen and manage conversational timing.
The company reports roughly 100 milliseconds of median model latency. That figure concerns inference, not the complete time a caller waits for a reply. The supported change is an integrated expressive speech option for live agents; improved customer outcomes remain the company's intended benefit.
Terms in this piece · Glossary
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Read the source elevenlabs.io
More from ElevenLabs editorial sitemap
Recommended reads
Comments
Checking sign-in…
Loading comments…