Cost-Effective Automated Judging of Natural-Language Mathematical Proofs
- Source
- arxiv.org
- Author
- Benjamin Grayzel
- Date
Context
Inexpensive language models may reduce the cost of grading mathematical proofs when they receive a reference proof and a human grading rubric. On 200 validation examples, three judges had agreement with human pass/fail decisions that was statistically indistinguishable from the tested expensive models, at up to one-hundredth the cost. Extending the experiment to 1,000 examples, the authors found that requiring all three judges to approve a proof produced the highest precision and pass-agreement. That unanimity rule was identified after examining results, so its reported advantage needs independent replication before being treated as an established default. Study abstract.
- On a 200-instance IMO-GradingBench sample, three cheap open-weight judges (GPT-OSS 120B, DeepSeek-V4 Flash, Gemma-4 31B) agreed with human pass/fail decisions at rates statistically indistinguishable from Claude Opus 4.7 and Gemini 3.1 Pro — at up to 100x lower cost.
- The expected best budget option — majority vote of the three — merely matched the frontier and did not improve on its own strongest member.
- Requiring unanimous agreement (all-three-pass) delivered the highest pass-agreement and precision, plus the smallest run-to-run spread across four replicate runs on the full 1000-instance .
- The deployable default the authors recommend is all-three-pass consensus, with an honest caveat: the rule was identified post-hoc and warrants independent replication before trusting it blindly.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
“On a 200-instance validation sample of IMO-GradingBench, three cheap judges (GPT-OSS 120B, DeepSeek-V4 Flash, Gemma-4 31B) agree with human pass/fail decisions at rates statistically indistinguishable from Claude Opus 4.7 and Gemini 3.1 Pro, at up to $100\times$ lower cost.”
“We had expected a majority vote of the three to be the best budget option; it matched the frontier but did not improve on its strongest member.”
“The headline finding is that cheap judges are competitive with the frontier at one to two orders of magnitude lower cost; as a deployable default we recommend all-three-pass, with the caveat that this rule was identified post-hoc and warrants independent replication.”
 articleAre the Financial Reasoning from LLMs Credible? A Real World Test over Long-Horizon StatementsXinke Tong, Xuanming Zhang, Tianyi Tang, An Yang, Jiatu Hu, Guojie Lin, Zhenzhen Shi, Lingfeng Zeng, Boyu Yang, Bing Zhao, Hu Wei, Lin Qu, Dayiheng Liu
 articleJev Vs Llm As A JudgeOpenRouter editorial sitemap
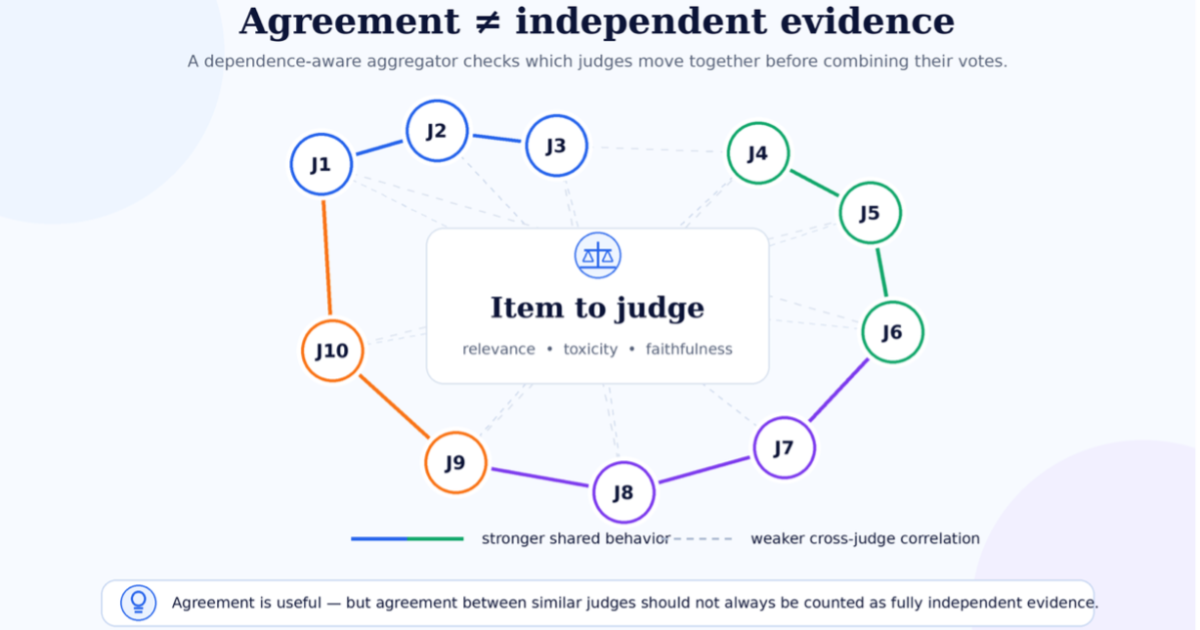 articleWhen LLM judges agree, should we believe them?www.amazon.science
Checking sign-in…
Loading comments…