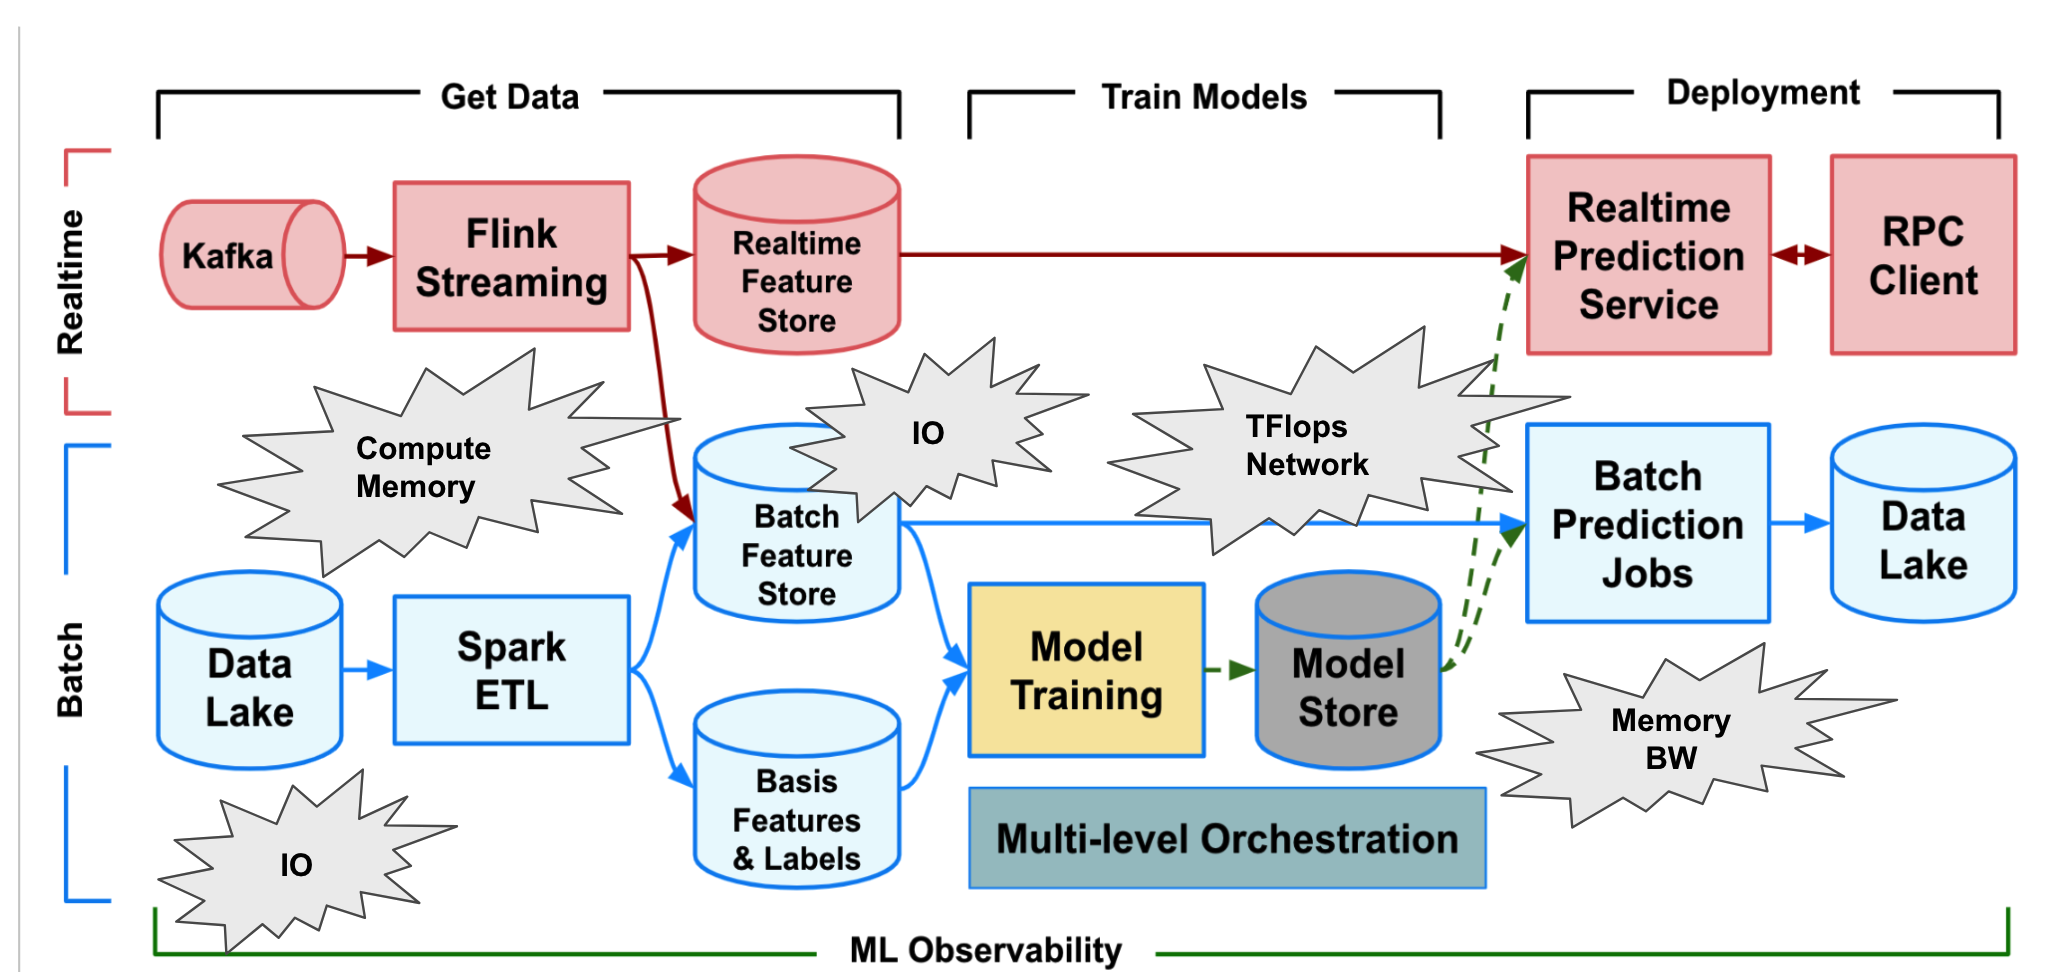
Shows what serving LLMs under compliance and GPU-scarcity constraints actually costs operationally, and why single-provider managed inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → gives way to multi-cloud routing as scale and availability requirements grow.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.