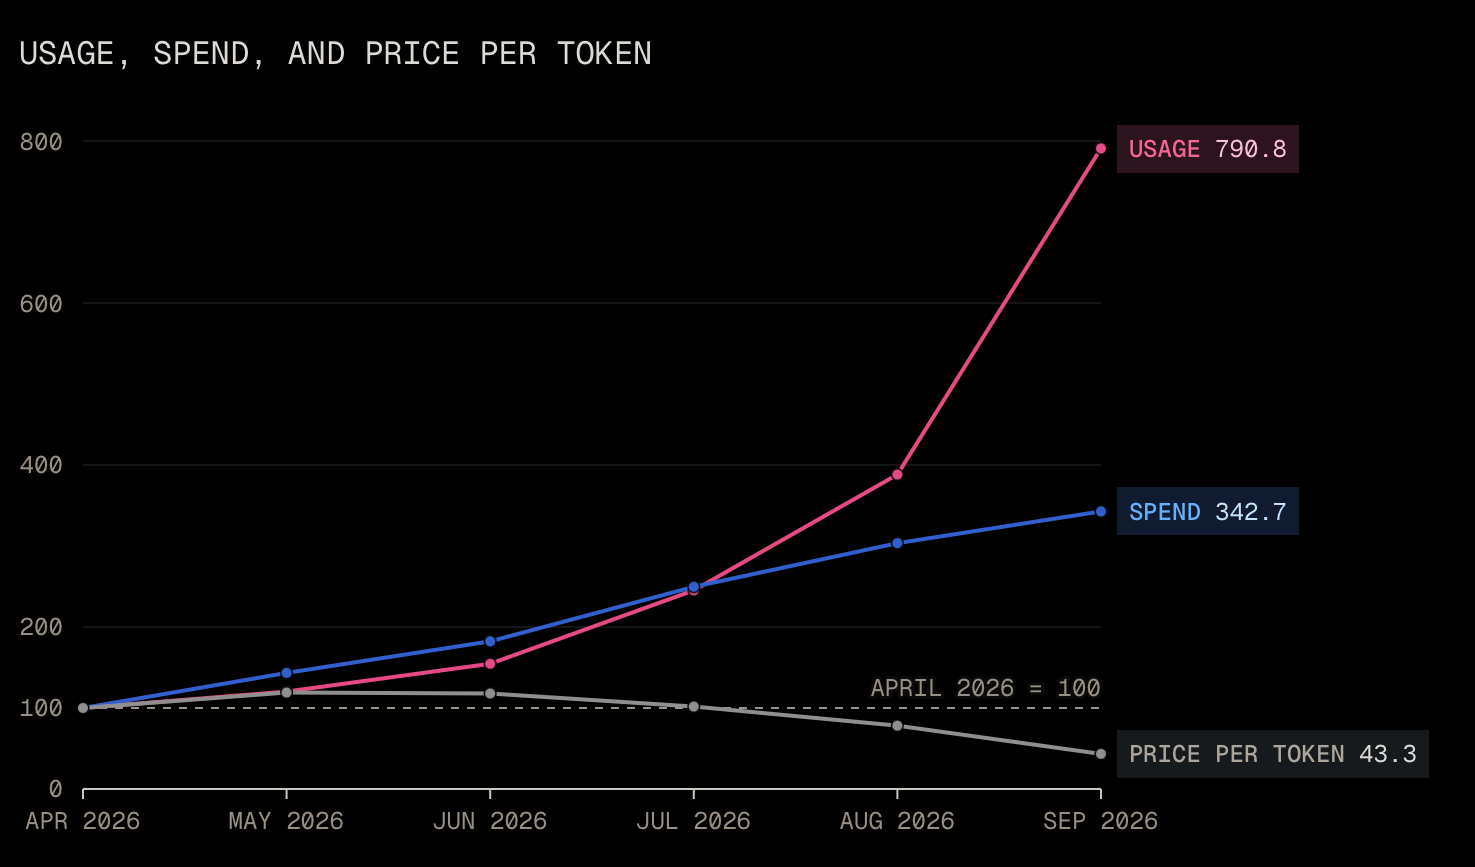
OpenAI and Anthropic cut their LLM prices by up to 80% within a few months. Why?
Source
minimaxir.com
Author
minimaxir
Date
Why it matters
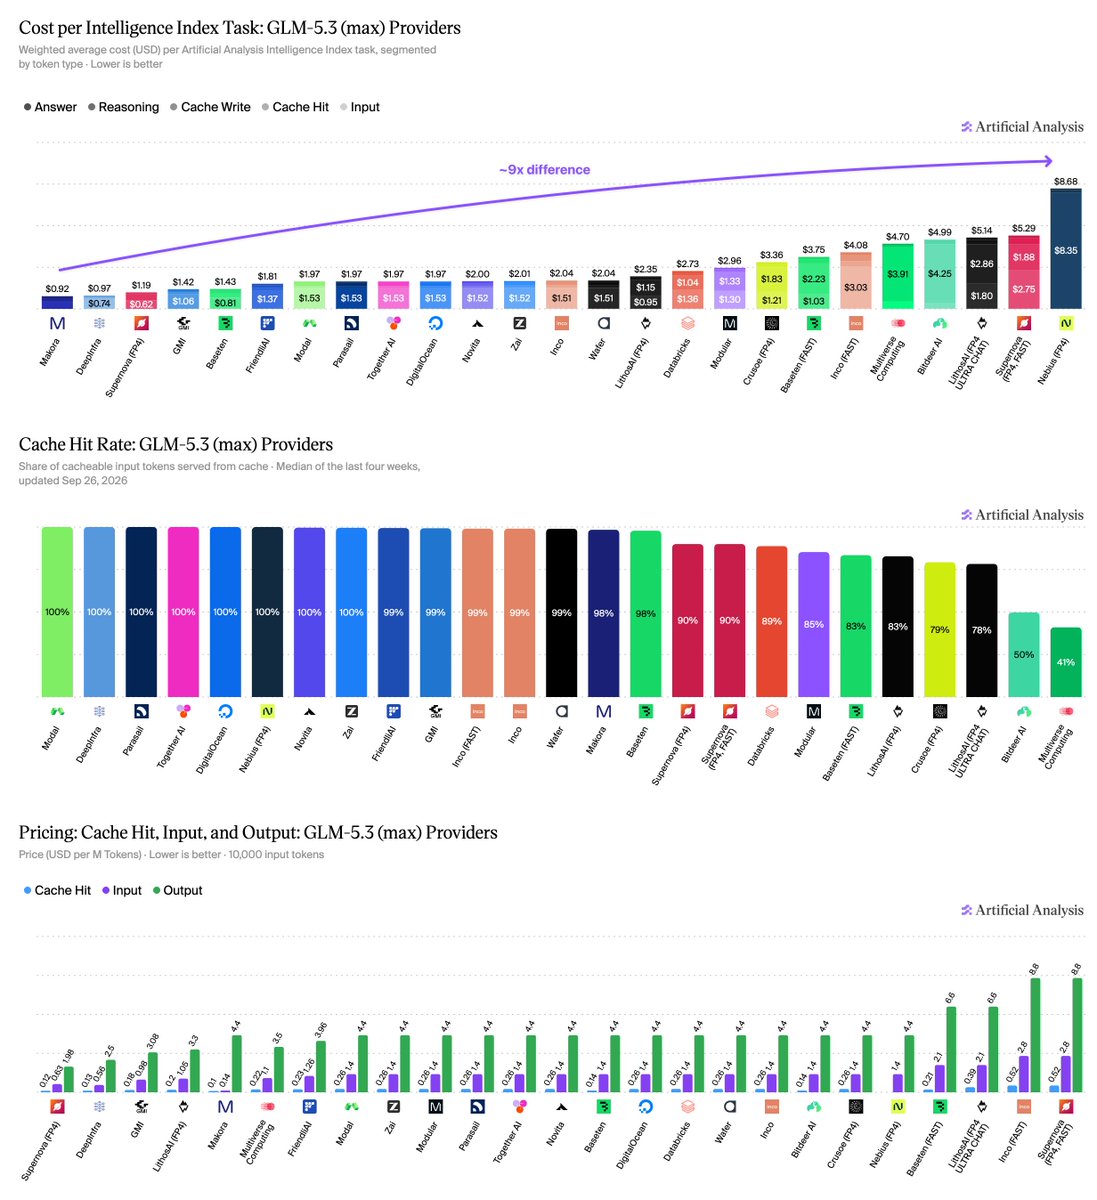
Cache reads make up most agentic coding spend, so a 75% cache-read cut lowers total cost 70 to 75%. Compare models on cache pricing, not just headline input and output rates.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.