StepFun ships Step-DeepResearch, a single-agent research system
- Source
- x.com
- Date

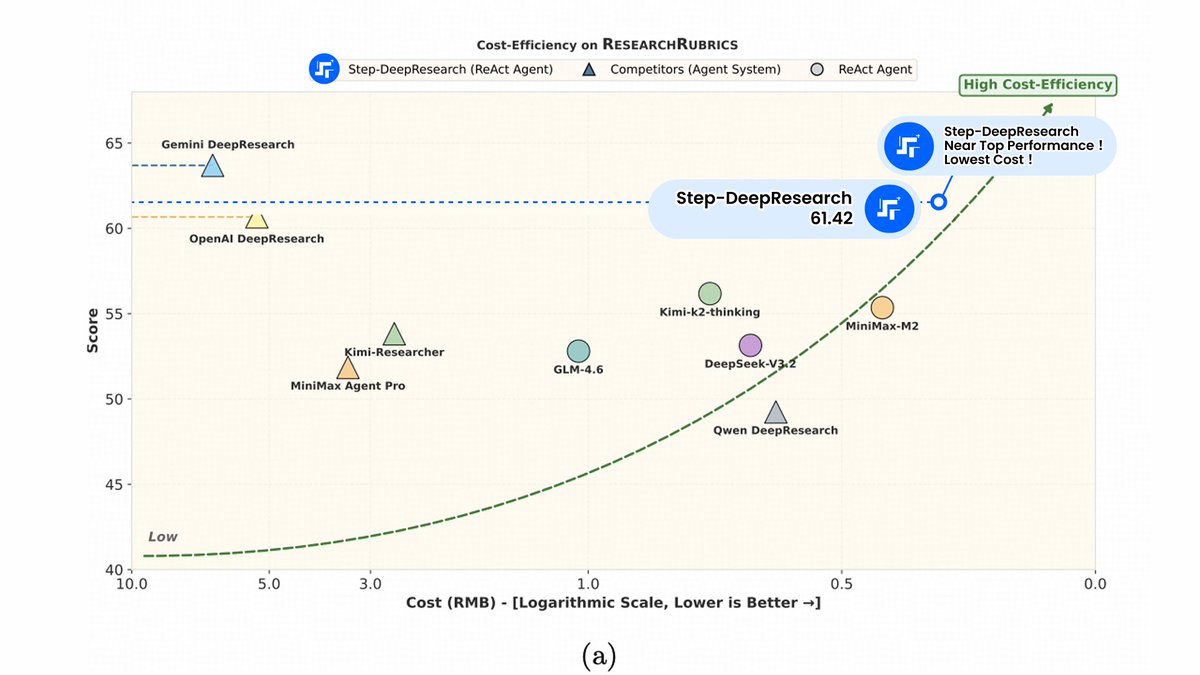
🔍 Meet Step-DeepResearch: our latest end-to-end deep research agent! We realized "search ≠ research". While others build "web crawlers," we built a researcher that internalizes the expert cognitive loop. 🧠 The Tech Stack: ✅Native Atomic Capabilities: We moved beyond "next-token prediction" to "next-action decisioning." ✅Self-Correcting Logic: Built-in adaptive planning & cross-source verification. No multi-agent bloat—just a lean, single-agent architecture. ✅Search API: Grounded in 20M+ high-quality papers and 600+ premium indices. The Stats: 🔥 61.42% on Research Rubrics (Matching Gemini, beating OpenAI). 🔥 67.1% Win/Tie rate on ADR-Bench vs. the giants. 🔥 Top-tier ratings for citation & communication quality. Better performance. Better citations. Better price point. The Beta is officially live. Dive in and let’s push the boundaries together! API Beta Access: https://t.co/yUeRql2eaG Homepage: https://t.co/pddmpXOdk4 Technical report: https://t.co/RnAgy8xhVt Github:
Context
StepFun released Step-DeepResearch, an AI research built around a single decision-making loop with what StepFun calls self-correcting logic: adaptive planning and cross-source verification, meaning the system checks its own findings against other sources as it works, rather than routing tasks between multiple coordinating agents. StepFun grounds it in a search index the company says covers more than 20 million papers and over 600 curated indices.
StepFun reports 61.42% on a called Research Rubrics, which it says matches Gemini's score and beats OpenAI's, and a 67.1% win-or-tie rate against other systems on ADR-Bench. Both figures come from StepFun's own reporting rather than an outside evaluator, and the specific competitor systems in each comparison were not named in the announcement. StepFun published a technical report and code alongside the beta API, allowing outside verification of the architecture claims even though the benchmark numbers themselves remain self-reported.
 postStepFun Open-Sources Step Code, a CLI Coding Agent Benchmarked on Terminal-Bench
 postStepFun Open-Sources onPanda, Its Internal LLM Annotation and Debug Tool
 postStepFun debuts StepAudio 3 voice model family, tops real-time benchmarks
 postvLLM gains an experimental Attention-FFN disaggregation plugin for MoE
Checking sign-in…
Loading comments…