Is Running Language Models On Cpu Really Viable
- Source
- arcee.ai
- Author
- Arcee AI
- Date
Context
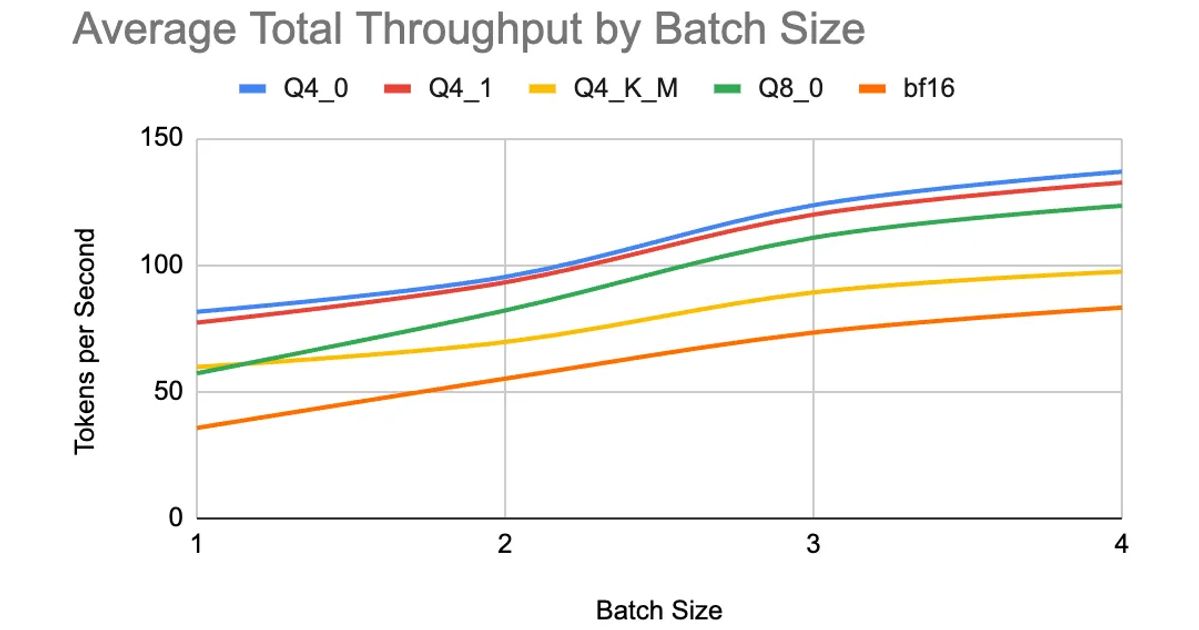
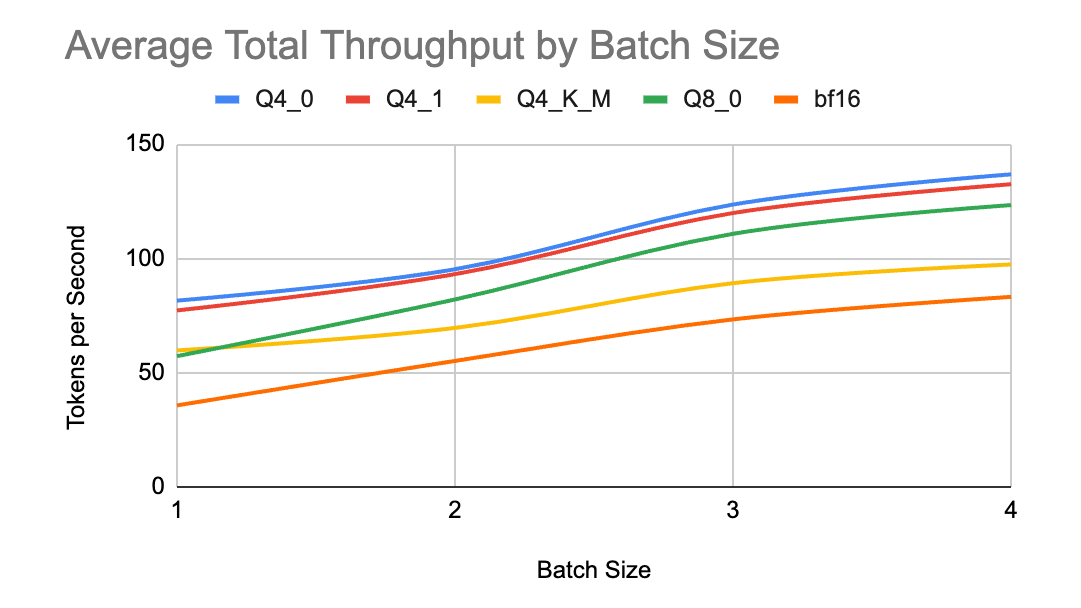
Running a small on a CPU can be practical, but in Arcee AI's July 2025 tests prompt length strongly affected how long a user waited on one laptop processor. The tests ran its AFM-4.5B model through llama.cpp on server and laptop processors using several numerical precisions.
On the tested X1E-80-100 laptop CPU, the four-bit Q4_0 version took an average 0.94 seconds to begin answering a 128- prompt, compared with 10.94 seconds for 1,024 tokens, with one request at a time. Arcee reported much shorter waits on its server processors and concluded that it would be reasonable to limit the laptop chip to short- questions, not document analysis. That measured difference makes short-question workloads a more plausible fit for this laptop configuration than processing long documents.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
Checking sign-in…
Loading comments…