Kimi K3.1 Pro leads open models on agentic cyber defense benchmark
- Source
- x.com
- Date

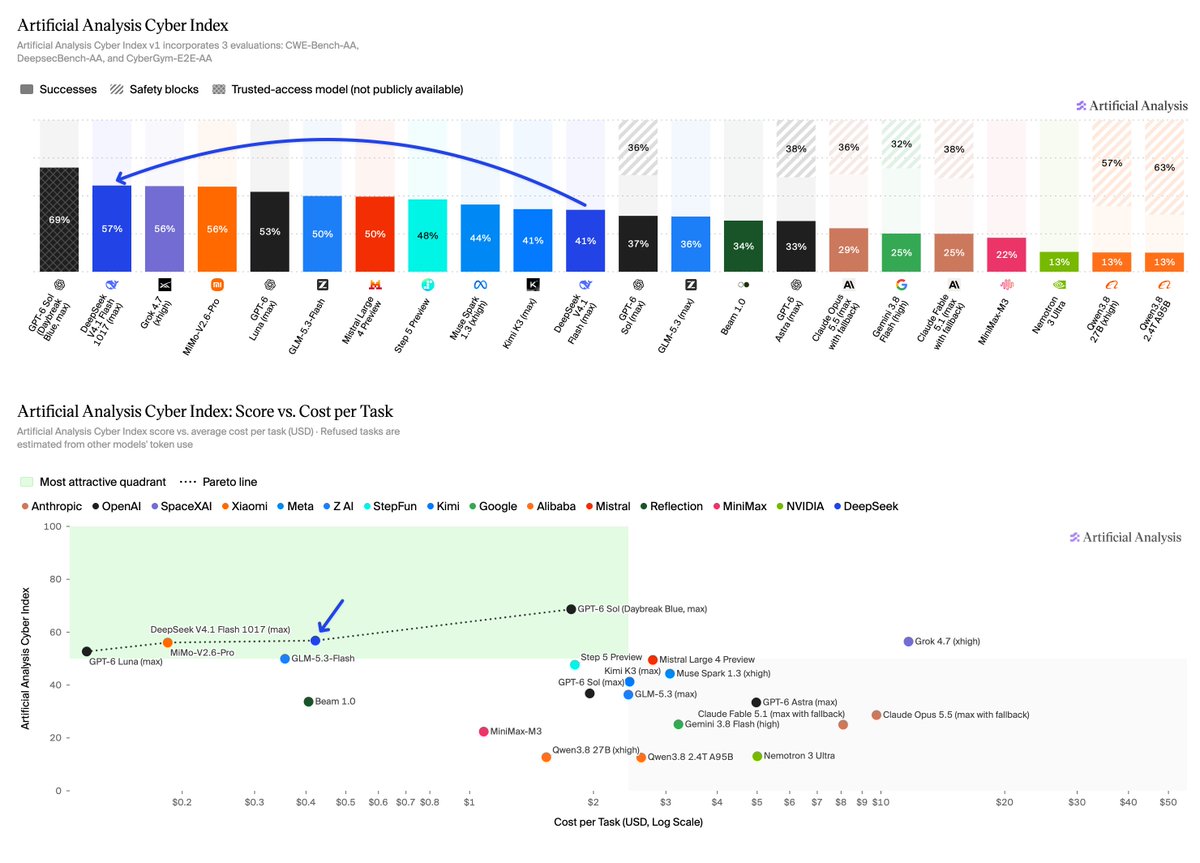
Kimi K3.1 Pro is the new #1 openly-available model for agentic cyber defense, behind only trusted-access model GPT-6 Sol (Daybreak Blue) on the Artificial Analysis Cyber Index @Kimi_Moonshot's Kimi K3.1 Pro scores 64% on the Artificial Analysis Cyber Index, 7 points ahead of the previous leading openly-available model, DeepSeek V4.1 Flash 1017 (57%), and 5 points behind GPT-6 Sol (Daybreak Blue, max, 69%), which is only available through OpenAI's trusted-access program. Once the weights for K3.1 Pro are released, K3.1 Pro will also be the leading open weights model for cyber defense. The Artificial Analysis Cyber Index measures capability on agentic cyber defense tasks and is composed of three benchmarks: CWE-Bench-AA, DeepsecBench-AA and CyberGym-E2E-AA. The Index primarily evaluates models through their publicly accessible APIs, reflecting the cyber capabilities available to developers. Proprietary models from OpenAI, Anthropic and Google may have stronger cyber capabilities but lose points to safety refusals: GPT-6 Sol (Daybreak Blue, max), available through OpenAI's trusted-access program, scores 32 points above its public counterpart. Kimi K3.1 Pro encounters no safety…
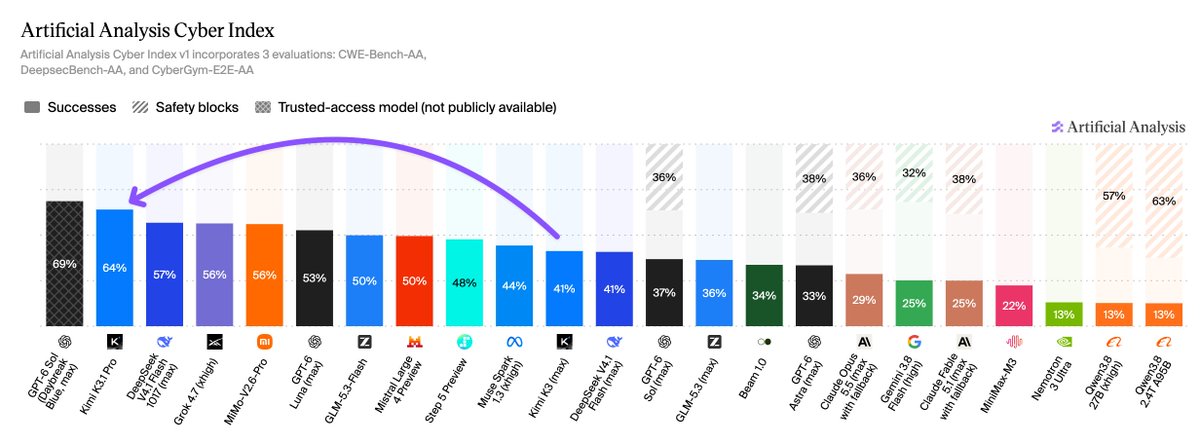
An open model reaches 64% on agentic cyber defense with no safety refusals, close to the trusted-access GPT-6 Sol at 69%. It costs $2.81 per task, and the 32-point gap between GPT-6 Sol's trusted and public tiers shows refusals affect measured capability.
- Artificial Analysis scores Kimi K3.1 Pro at 64% on its Cyber Index, up 23 points from Kimi K3 and 7 ahead of DeepSeek V4.1 Flash 1017. It trails only trusted-access GPT-6 Sol (Daybreak Blue, max) at 69%, and hit no safety refusals.
- K3.1 Pro posts the highest CyberGym-E2E-AA score of any model, 95% against 93% for GPT-6 Sol (Daybreak Blue), but trails on DeepsecBench-AA (37% vs 48%) and on CWE-Bench-AA, where DeepSeek V4.1 Flash 1017 leads at 69%.
- Lower prices did not make it cheaper to run here: K3.1 Pro is 33% cheaper per token than K3 but used about 2x more input tokens, so cost per task rose 15% to $2.81, above GPT-6 Sol (Daybreak Blue) at $1.77.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…