HunyuanVideo 1.5 fits open video generation into 14GB of VRAM
- Source
- x.com
- Date

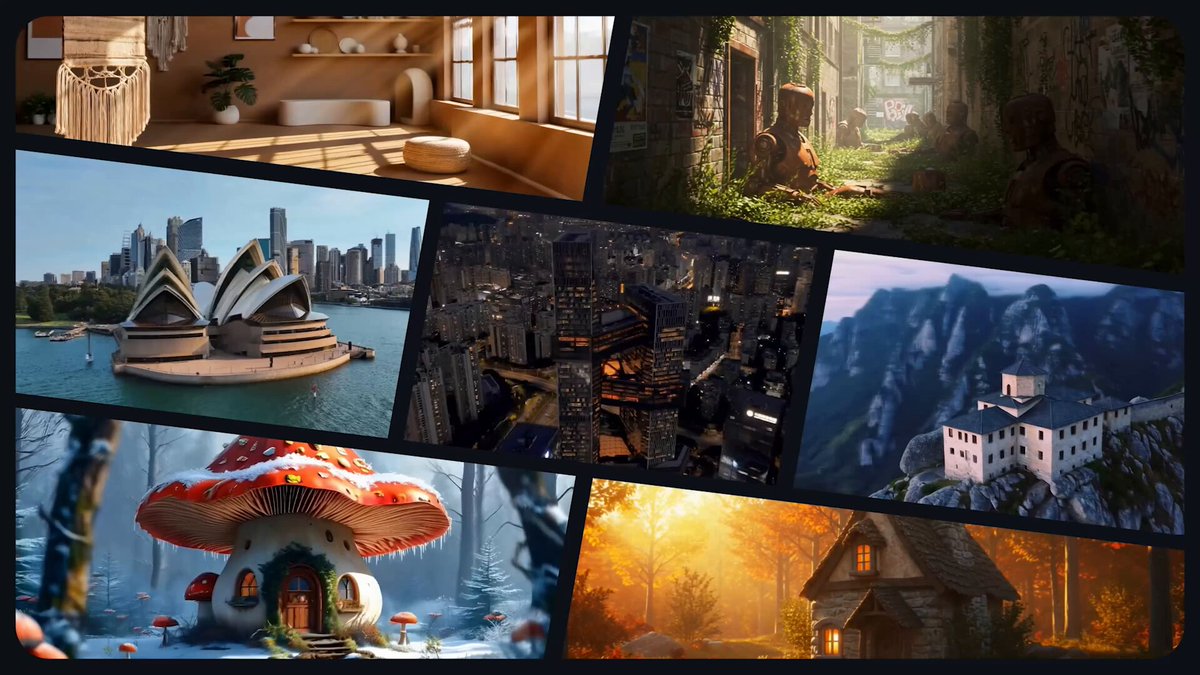
We are excited to unveil HunyuanVideo 1.5, the strongest open-source video generation model. Built upon DiT architecture, it redefines the open-source SOTA for accessibility and performance.🚀🚀🚀 HunyuanVideo 1.5 delivers state-of-the-art visual quality and motion coherence while drastically lowering the entry barrier for developers and creators: ⚡️ Unmatched Accessibility: Ultra-light 8.3B parameters, deployable on consumer GPUs with only 14GB VRAM. 🖥️ HD Cinematic Quality: Natively generates 5–10 second 480p/720p HD videos, with super-resolution support for 1080p cinematic quality. By merging SOTA performance with high hardware efficiency, HunyuanVideo 1.5 sets the new technical baseline for the open-source community. 🌐Project Page: https://t.co/DeKGy8IzaW 🔗Github: https://t.co/7z2aPlERFw 🤗Hugging Face:https://t.co/sCE1KKBwO2 📄Technical Report:

Your amazing creations and feedback following the HunyuanVideo 1.5 launch have been incredible. Jump in and try the open-source SOTA model for yourself! 👇 Project Page: https://t.co/lmBBFoLjDZ T2V: https://t.co/r2MQwdHgDp I2V: https://t.co/D61fwPR36W https://t.co/AjxWqUiVyF
Context
Tencent's HunyuanVideo 1.5 documents a 14GB minimum GPU-memory requirement with model offloading enabled. Offloading moves parts of the model into CPU memory to reduce what must stay on the GPU; the repository says turning it off can speed up when enough GPU memory is available. The 14GB figure therefore describes a memory-saving configuration with a speed tradeoff. Hardware requirements and inference options.
The launch post describes an 8.3-billion-parameter model that natively generates five-to-ten-second clips at 480p or 720p, with super-resolution support for 1080p output. That separates the model's native resolutions from its enhanced output. Launch description.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
 articleExplorationBench: Feedback and Self-Designed Probes Drive Agent Discovery
 postHy Image3.5 preview is live. 🚀 Professional-grade image generation, +30% win…
 postTencent Hunyuan's EvolveScaler trips up frontier models on evolving facts
 postTencent Hunyuan open-sources AuK, a unified speech generation and editing model
Checking sign-in…
Loading comments…