ClaimBench: small decision models rival LLMs at 1/10 the cost
- Source
- x.com
- Date

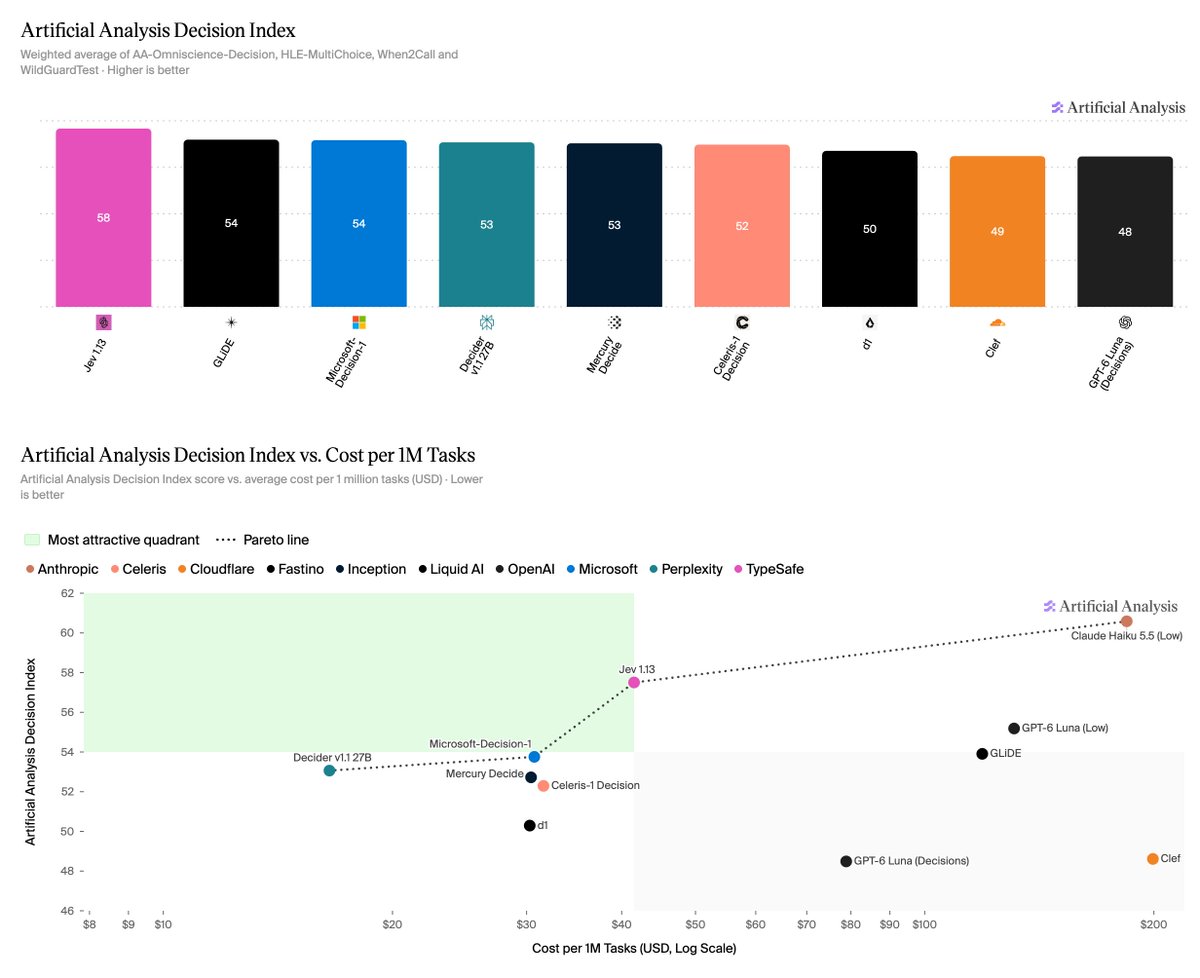
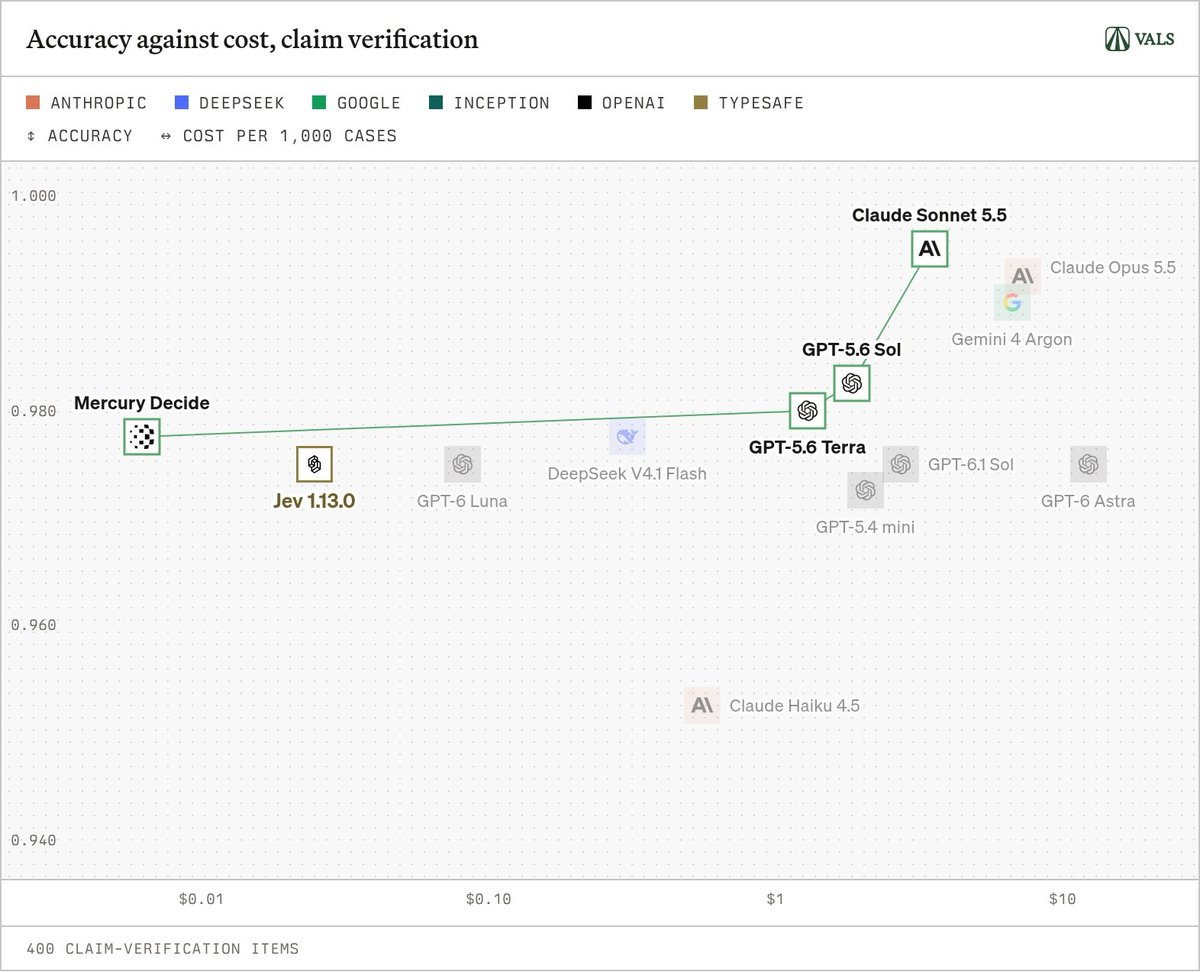
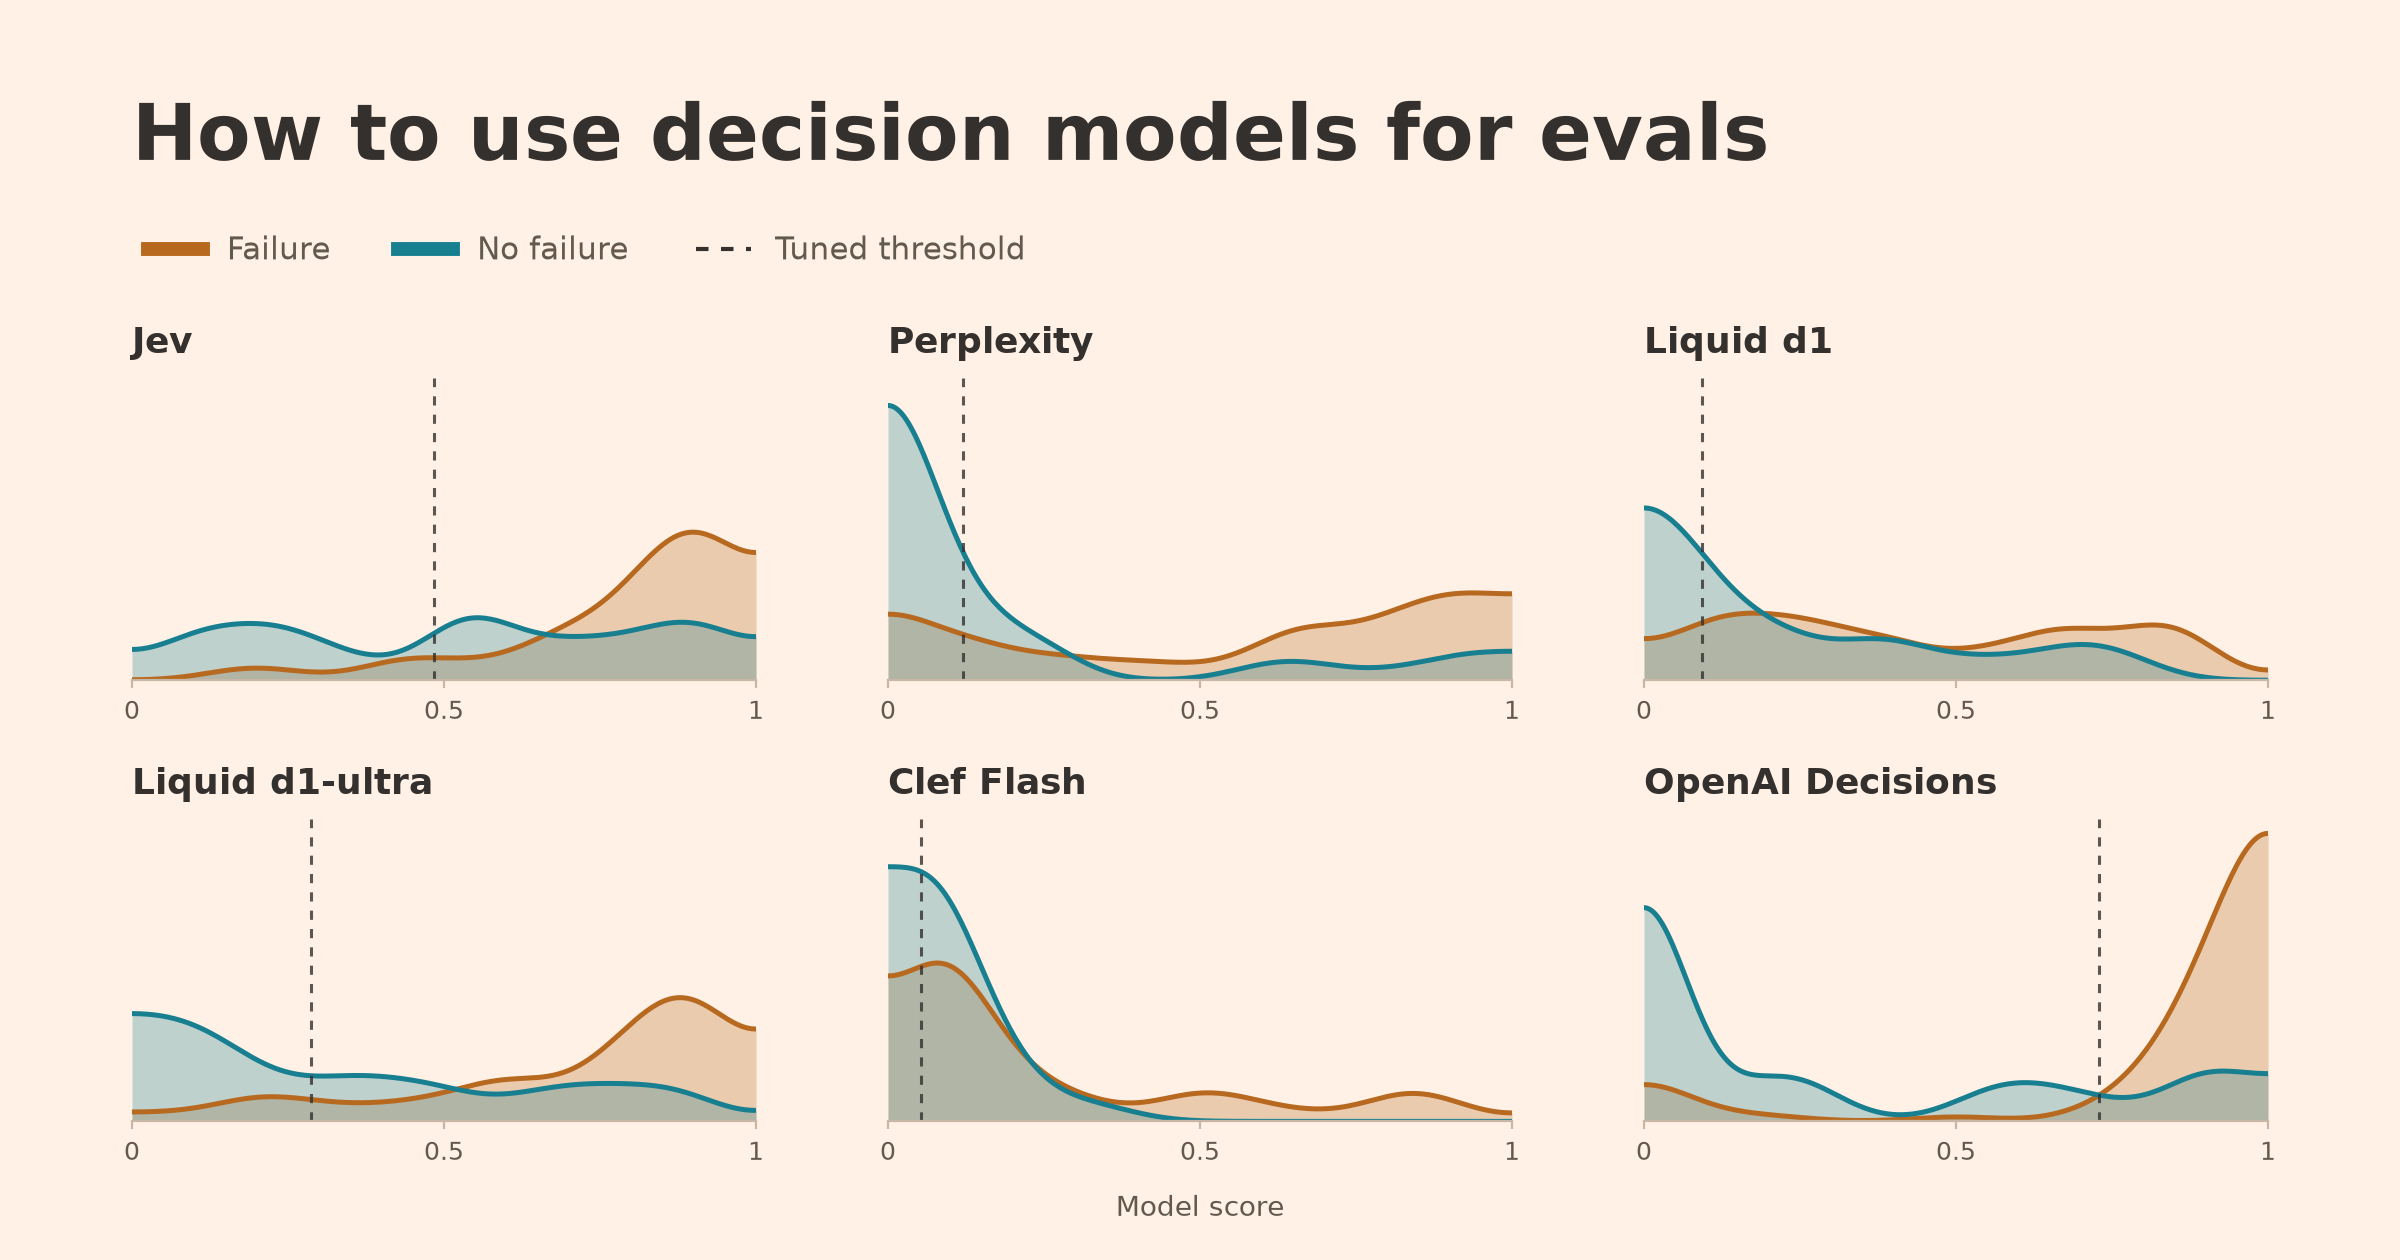
Today we’re releasing ClaimBench, our new benchmark targeted towards decision models. It tests whether a model can tell if a financial document supports, contradicts, or doesn’t address a claim. We evaluated 15 models on 1,960 claims paired with 10-K excerpts, with Decider V1.2 leading the pack of decision models.

Context
ClaimBench, released by Vals AI, tests a narrow judgment that finance work relies on. Given a claim and an excerpt from a company's 10-K annual report, does the excerpt support the claim, contradict it, or not address it? The third label means a model has to tell a document that says nothing about a claim apart from one that disputes it, instead of treating the two as the same. Vals evaluated 15 models on 1,960 claims paired with 10-K excerpts.
Vals says the is aimed at decision models, a kind of model that returns a constrained judgment instead of free-form text. Its top decision model was Decider V1.2, which Vercel's listing of Perplexity's Decider V1.2 models describes as answering typed questions with probabilities: the likelihood of yes, a choice among defined categories, or a rubric score. A three-way label such as supports, contradicts or not addressed fits that format directly.
The post's text gives no scores, no other model names and no cost figures. It carries an attached image that was not analyzed for this note. So the post supports that Decider V1.2 ranked first among the decision models tested. How decision models compared with general-purpose LLMs, and at what cost, cannot be confirmed from what was read here.
Checking sign-in…
Loading comments…