Artificial Analysis launches Decision Index for classifier-style models
- Source
- x.com
- Date
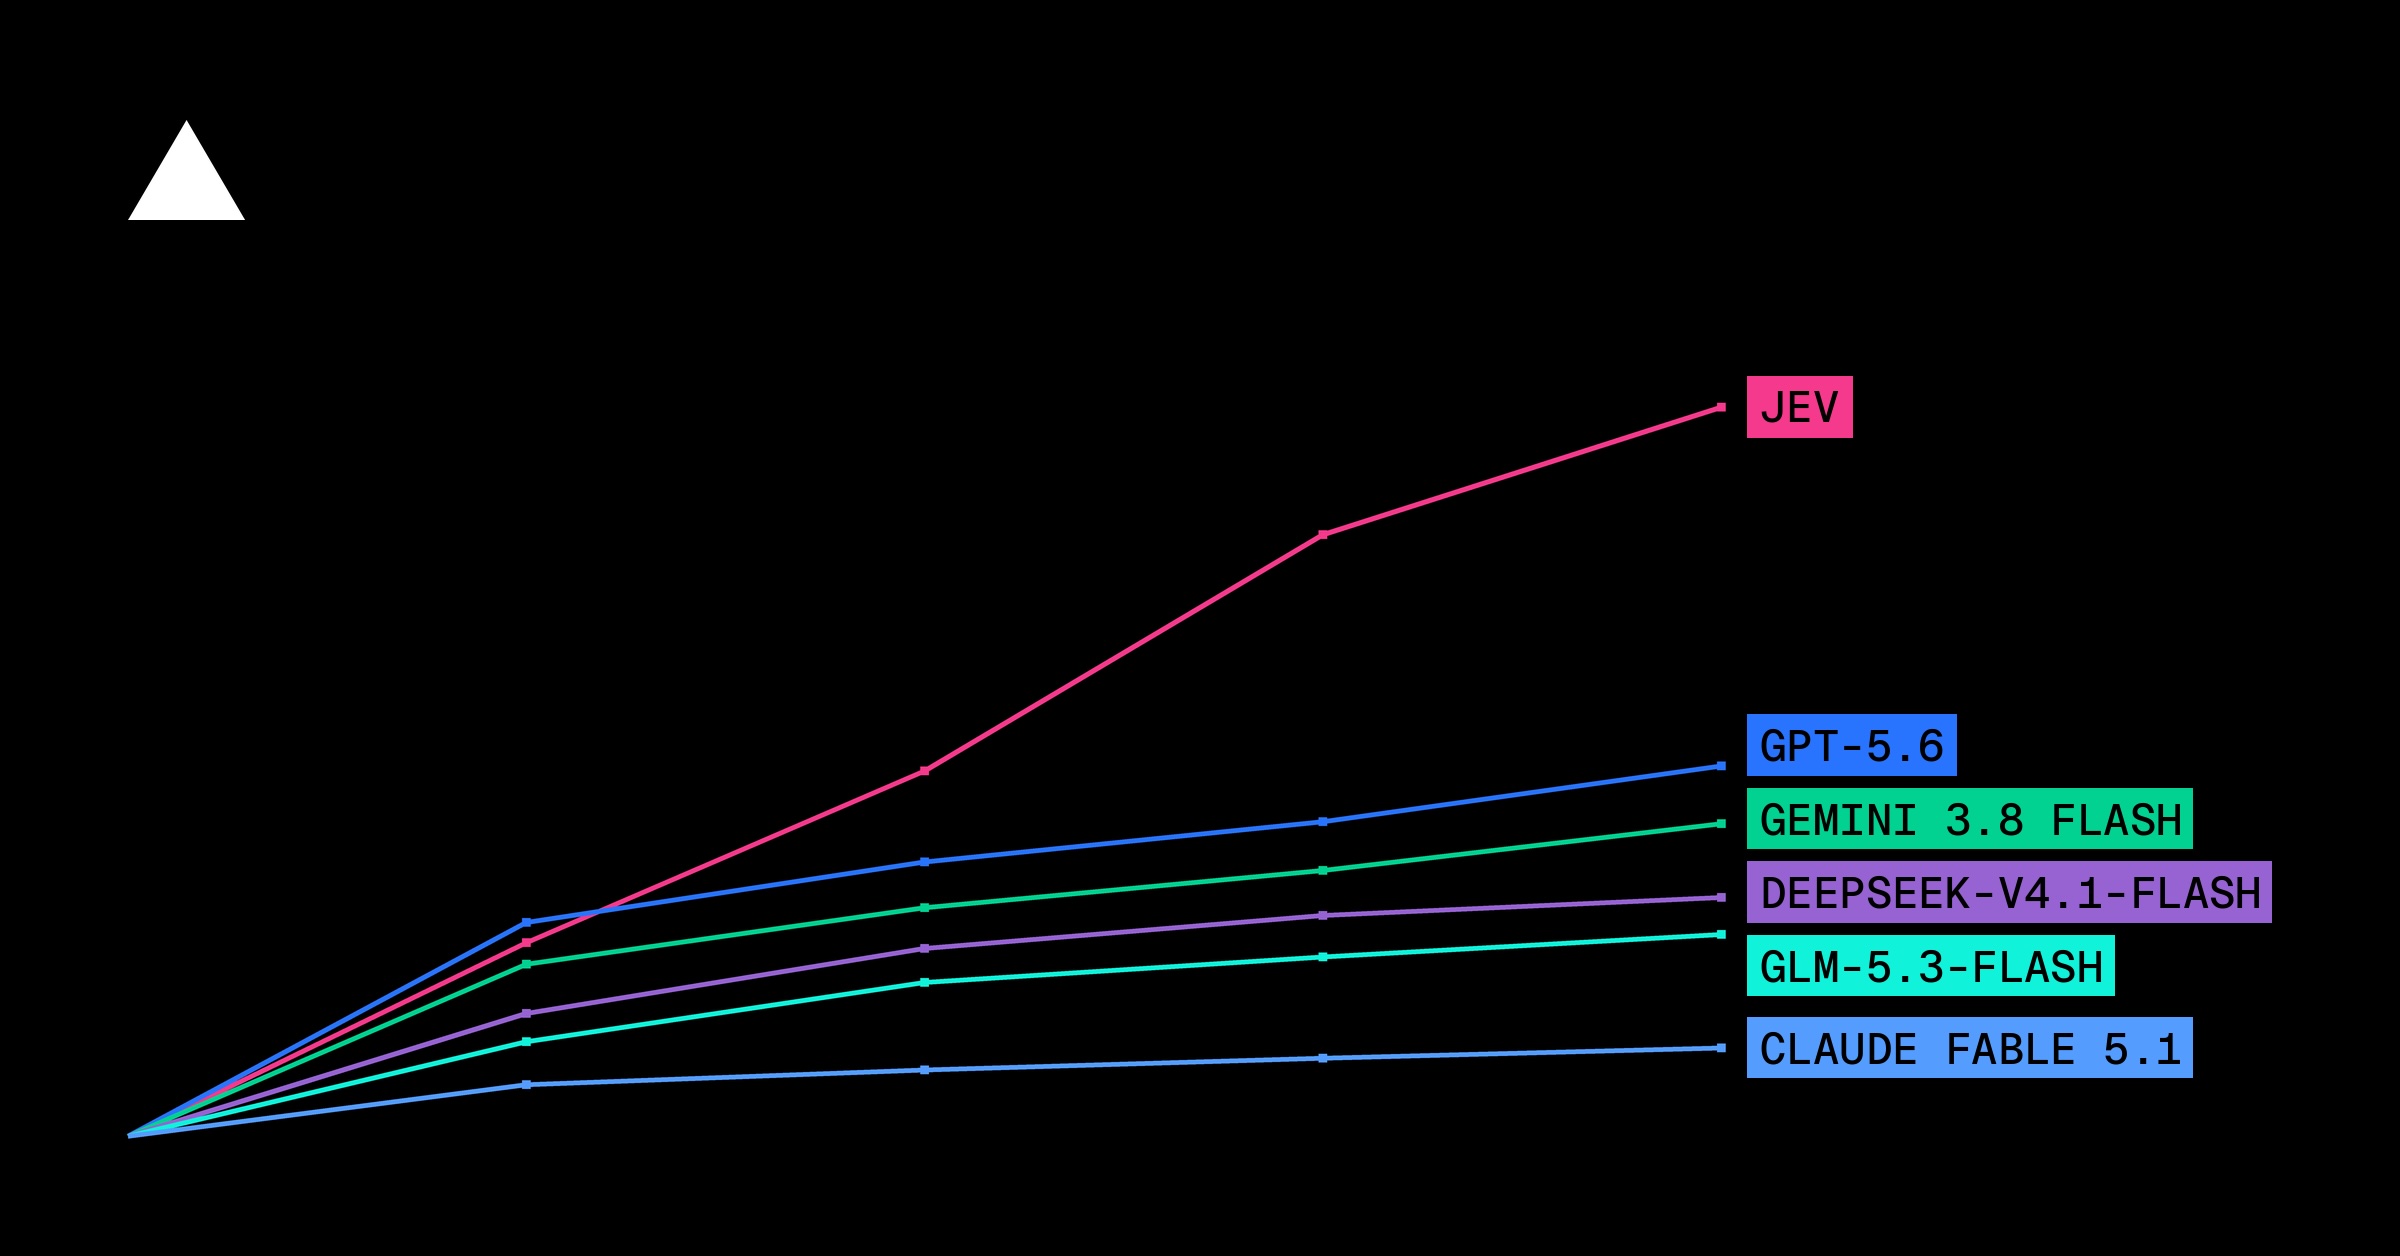
Introducing the Artificial Analysis Decision Index, benchmarking decision models across classification, tool calling, knowledge and reasoning. Jev leads among decision models; language models such as Claude Haiku 5.5 still deliver higher accuracy, but at much higher cost and latency Decision models deliver structured answers or classifications with associated probabilities, offering faster responses and lower costs than using language models. The Artificial Analysis Decision Index v1.0 compares the capability, cost, and speed of decision models and also compares to language models. Benchmarks in the Artificial Analysis Decision Index v1.0: ➤ AA-Omniscience-Decision: A private dataset of 500 questions adapted from the proprietary AA-Omniscience benchmark, measuring decision models’ knowledge and tendency to hallucinate ➤ HLE-MultiChoice: 513 text-only multiple-choice questions from Humanity’s Last Exam, testing decision models’ reasoning capabilities ➤ When2Call: A tool-calling benchmark from NVIDIA, testing whether models can correctly decide to call a tool, request clarification, decline to answer, or respond directly, evaluating capabilities relevant to agentic workflows…

Gives a way to compare cheap classifier-style decision models against small LLMs for tool routing and safety checks. Claude Haiku 5.5 is more accurate but costs more and is slower.
Checking sign-in…
Loading comments…