Epoch found problems in the original Chinchilla parametric fit and produced estimates that better match the paper's other approaches. Anyone choosing model size versus training tokens for a compute budget can rely on a corrected token-to-parameter ratio.
Key takeaways · AI-distilled
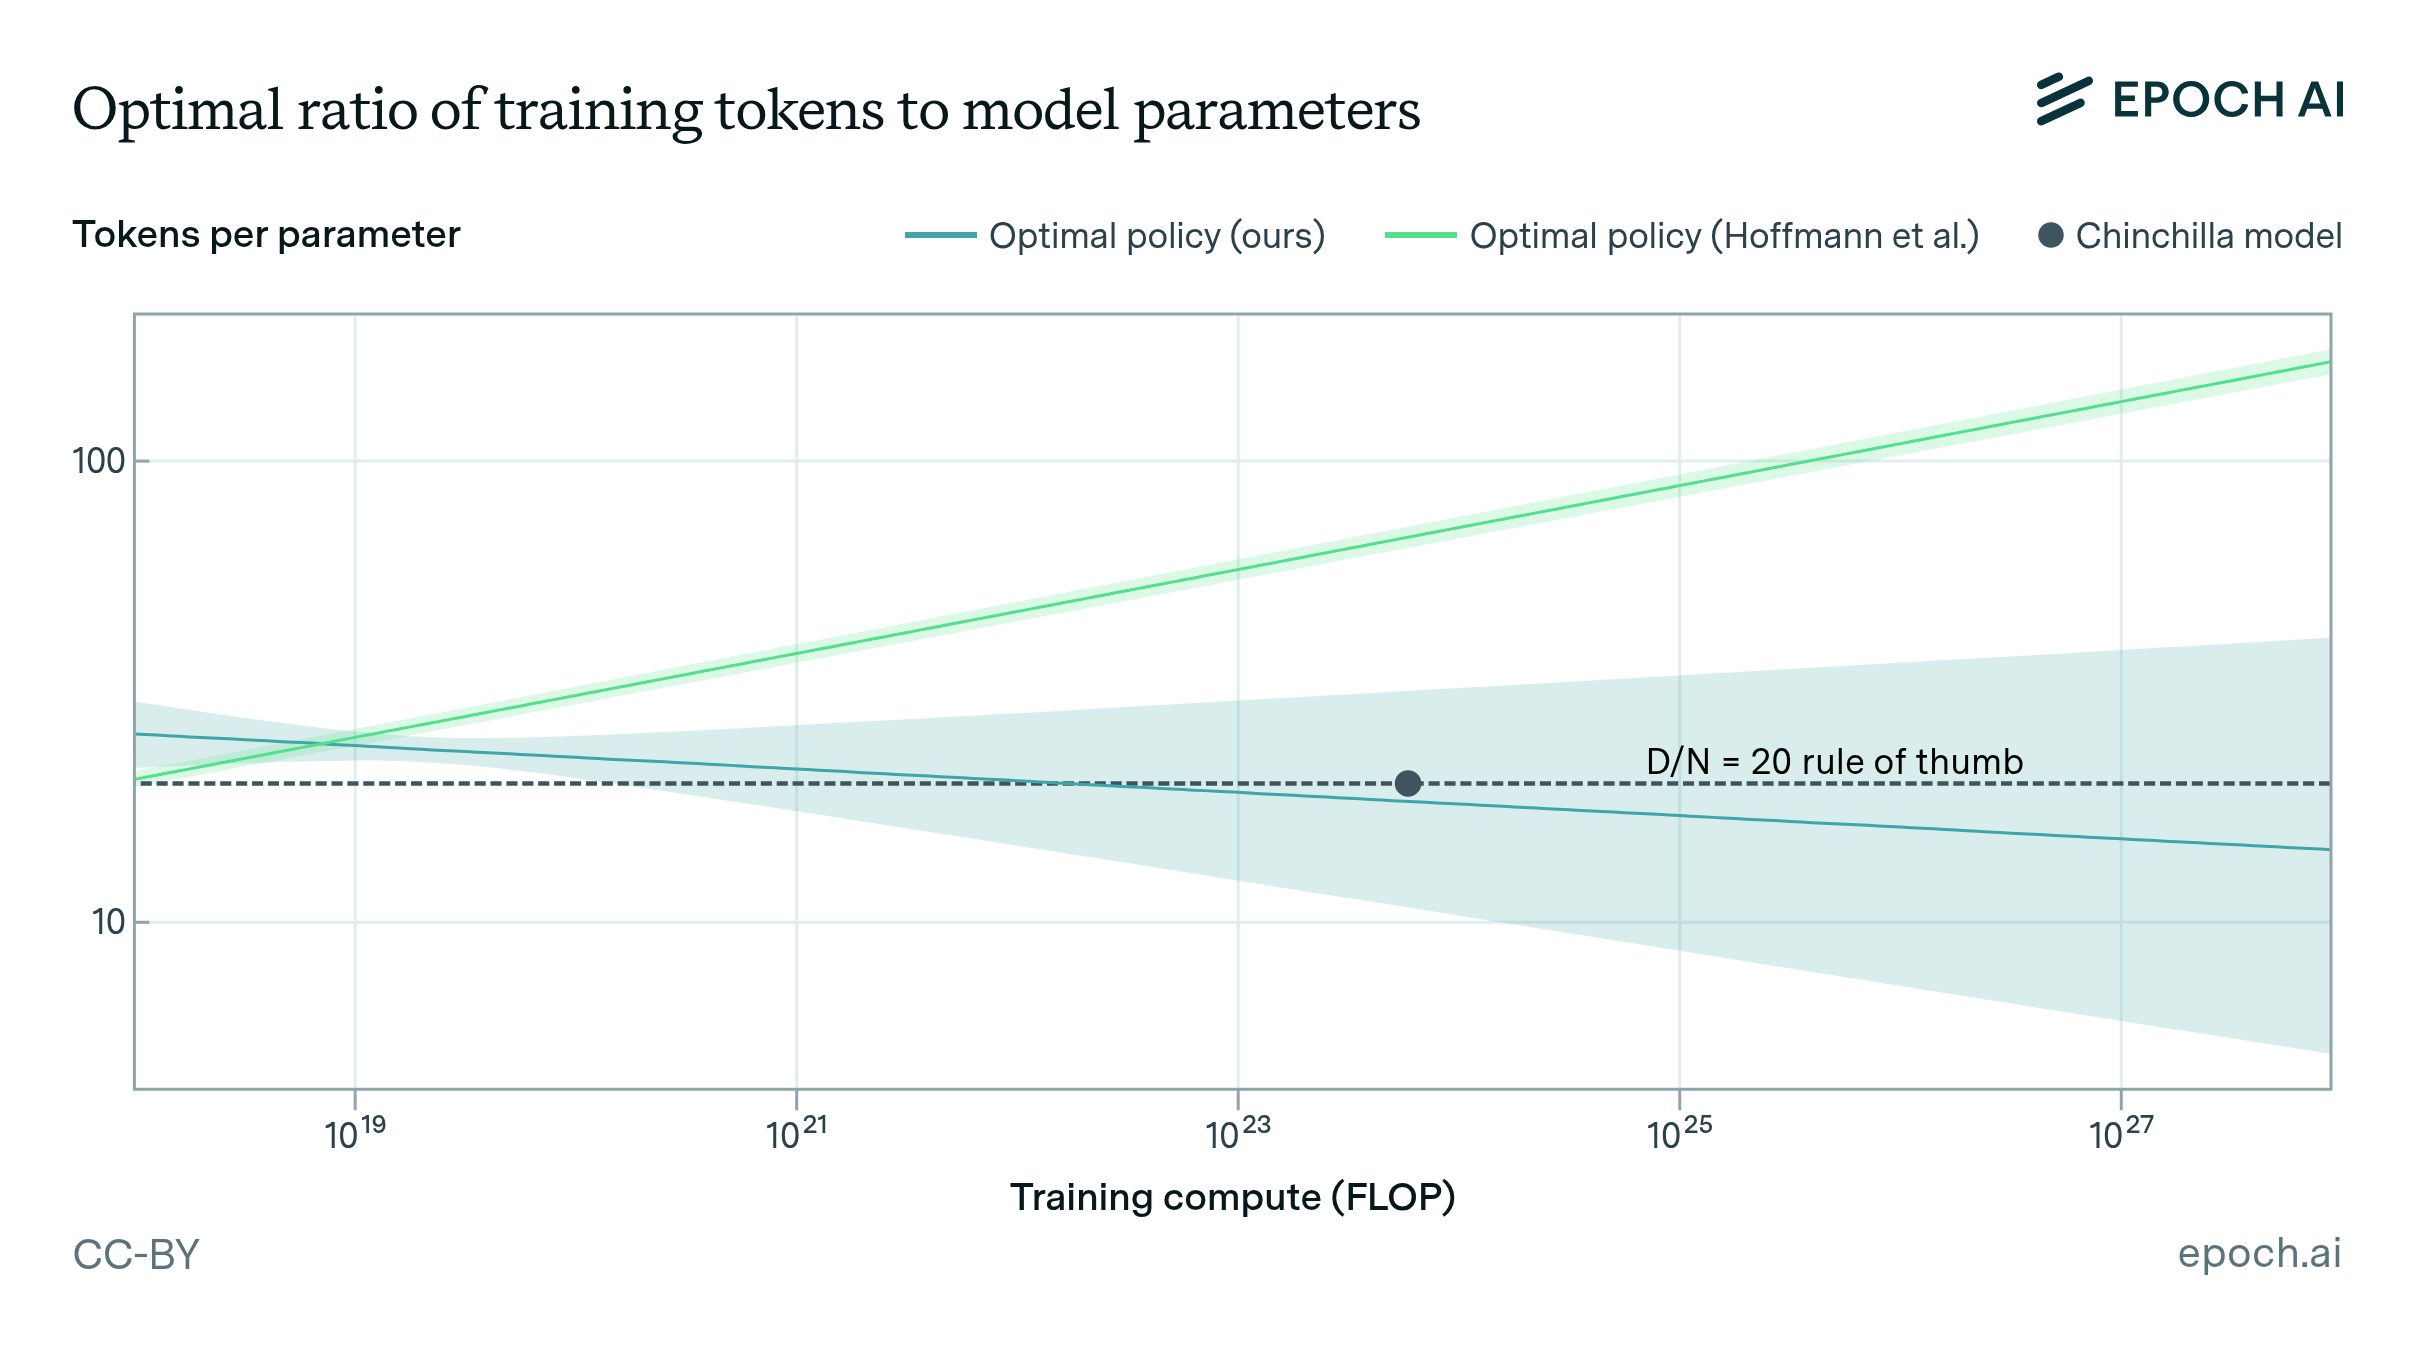
Hoffmann et al. trained over 400 models and concluded parameters and training tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → should scale equally; Chinchilla, a 70B model, was trained on 1.4 trillion tokens, about 20 tokens per parameter.
Rebuilding part of the data from the paper's plots, Epoch found the published parametric fit matches it poorly, even allowing for reconstruction noise and excluding outlier models.
The original confidence intervals are implausibly tight for roughly 400 data points; Epoch says intervals that narrow would need hundreds of thousands of observations.
Epoch's refit raises the data-scaling exponent and irreducible loss, L = 1.8172 + 482.01/N^0.3478 + 2085.43/D^0.3658, and unlike the original fit it agrees with the paper's other methods and the 20 tokens-per-parameter rule.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.