TREK: A Travel Reasoning and Evaluation Kit for LLM Agents in Complex Trip Planning
Source
arxiv.org
Author
Jinhu Qi, Wentao Zhang, Siu Man Ng, Feiyang Xu, Yanyu Chen, Yaoman Li, Irwin King
Date
Why it matters
An AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition →benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → graded deterministically instead of by an LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition → judge, with a human gold plan that provably scores 1.0 and 267 tasks that are infeasible by construction — so refusal, not just output quality, is measurable.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
 articleTangent: An Empirical Study of Testing Practices for LLM-Based Agent ApplicationsRangeet Pan, Tyler Stennett, Divya Sankar, Bridget McGinn, Alessandro Orso, Raju Pavuluri, Saurabh Sinha, Maja Vukovic
 articleKNOWPLAN: Knowledge-Driven AI Agents for Smart Degree Pathway PlanningShuheng Cao, Weijia Zhang, Jiaqi Wu, Xiyun Hu, Yat Yang, Juqy Chen, Zhaoxiang Feng
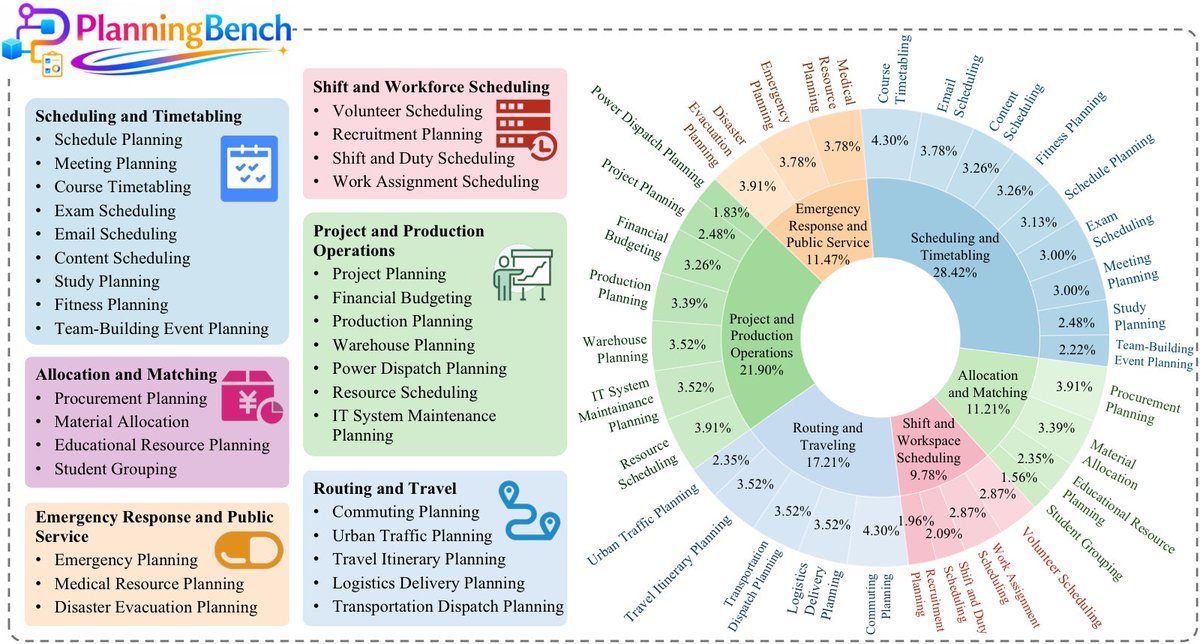 postPlanningBench puts LLM planning under automated verificationTencent Hy