PlanningBench puts LLM planning under automated verification
- Source
- x.com
- Date

Planning is where LLMs move from “saying” to “doing.” Tencent Hy, in collaboration with the Gaoling School of Artificial Intelligence at Renmin University of China, is excited to open-source PlanningBench - a scalable, verifiable framework for evaluating and training LLM planning capabilities. With PlanningBench, you get: ✅ 30+ real-world planning tasks ✅ Automated verification ✅ Evaluation and training support See how top-tier LLMs perform on PlanningBench 👇 Resources: arXiv: https://t.co/N5xTRdo9KR GitHub: https://t.co/XftHZrKGyB HuggingFace: https://t.co/nBbddXnEDx #PlanningBench #TencentHunyuan #OpenSource 📷

Context
PlanningBench tests whether a can assemble a complete plan that satisfies several requirements at once. The announced by Tencent pairs each text problem with verification checklists covering constraints and objectives, so a plan that reads plausibly can still fail the checklist. Dataset documentation.
Problems are built by a generation framework over planning families, task types and constraint categories, then passed through automatic filtering and human quality review. The announcement describes the framework as usable for and training, but the dataset card says the 467 synthetic instances released are intended as test data, not training data. Construction and release scope.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
 postExplorationBench tests how models explore, with exactly verifiable grading
 postHy Image3.5 preview is live. 🚀 Professional-grade image generation, +30% win…
 postTencent Hunyuan's EvolveScaler trips up frontier models on evolving facts
 postTencent Hunyuan open-sources AuK, a unified speech generation and editing model
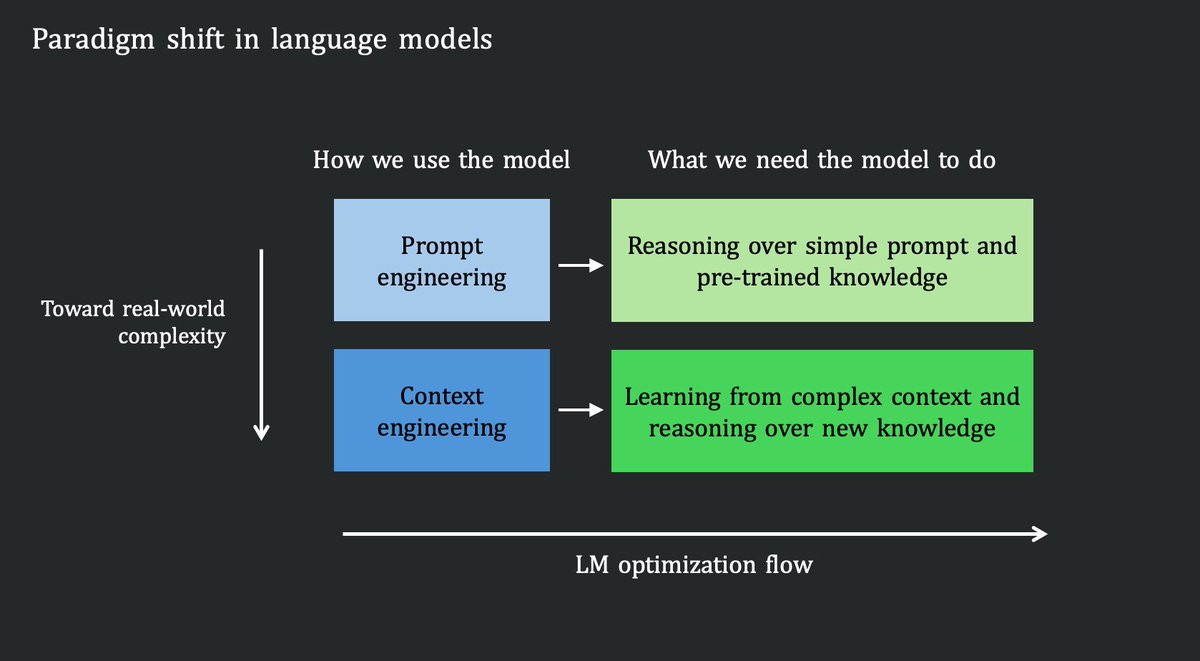 postCL-bench: frontier models solve just 17.2% of in-context tasksTencent Hy
- postExplorationBench tests how models explore, with exactly verifiable gradingTencent Hy
 articleTREK: A Travel Reasoning and Evaluation Kit for LLM Agents in Complex Trip PlanningJinhu Qi, Wentao Zhang, Siu Man Ng, Feiyang Xu, Yanyu Chen, Yaoman Li, Irwin King
Checking sign-in…
Loading comments…