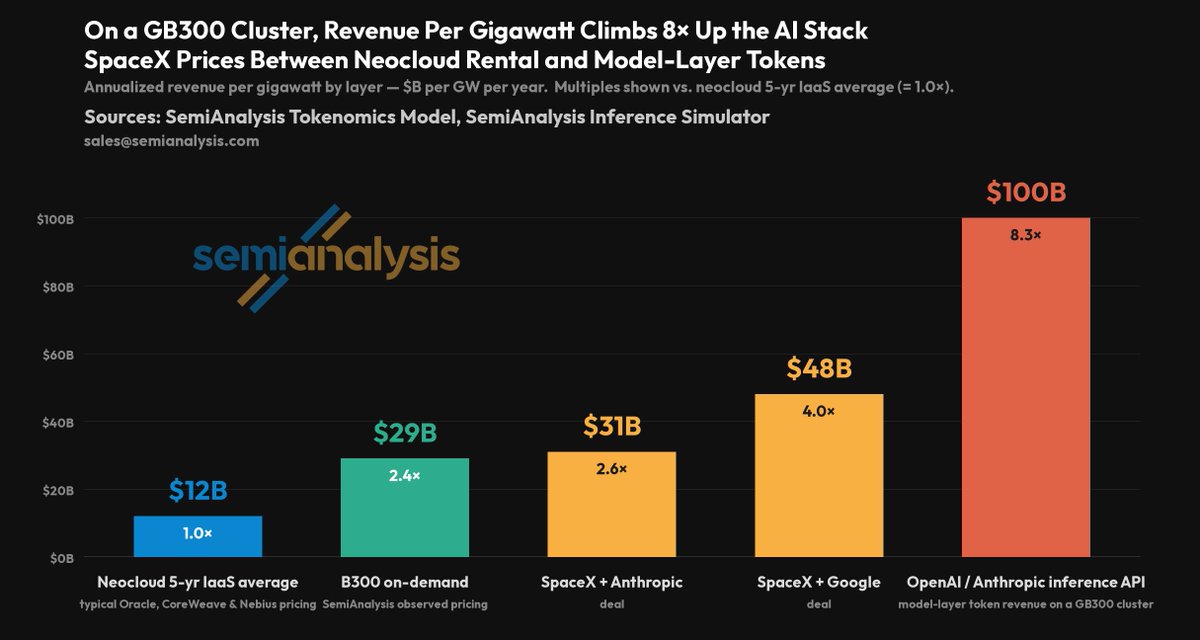
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Why it matters
Gives investors and operators a rigorous, quantitative framework for GPU rental economics and long-term cluster ROI, an area with little serious public modeling despite huge capital flows into AI infrastructure.