Recursive Self-Improvement for Agents: 7-Check Persistence Gate
- Source
- alphasignal.ai
- Author
- AlphaSignalAI
- Date
Context
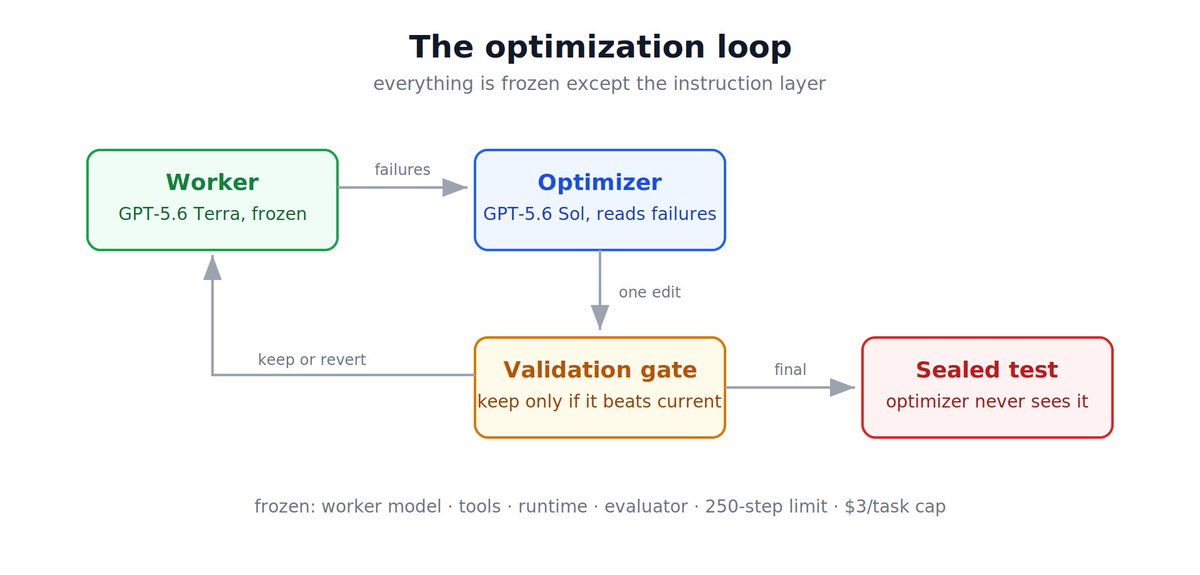
An 's improvement becomes persistent when something it produces changes how later runs operate. AlphaSignal's Persistence Gate article distinguishes a better individual answer from a retained change to instructions, tools or surrounding code. In the latter case, future tasks inherit the change even if the underlying model stays the same.
The article proposes treating that inheritance as a release decision with a defined scope. A change might be suitable for offline replay yet remain unsuitable for live actions that modify production systems. This frames self-improvement as a question about what persists, what evidence supports it and where it is allowed to operate.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
“Weco reports that AIDE2 executed 100 consecutive harness rewrites over 8 unattended days, retaining 7 successive versions under a fixed evaluation budget.”
Adham Khaled
“Recursive self-improvement begins when an artifact produced at generation t changes how generation t+1 is produced, judged, selected, or executed.”
Adham Khaled
“My read is narrower than "RSI has arrived." Current systems show that fixed models can sit inside loops that retain useful software changes, while the evaluator and promotion authority remain outside the editable system.”
Adham Khaled
“Under a matched 5-rollout budget, sequential refinement reached 91.8 pass@5 versus 86.2 for harness evolution, while the disjoint harness gain averaged only 0.6 points.”
Adham Khaled
“In the same setting, a one-run rule credited a neutral mechanism about 60% of the time and reported a false gain of at least three percentage points about 25% of the time.”
Adham Khaled
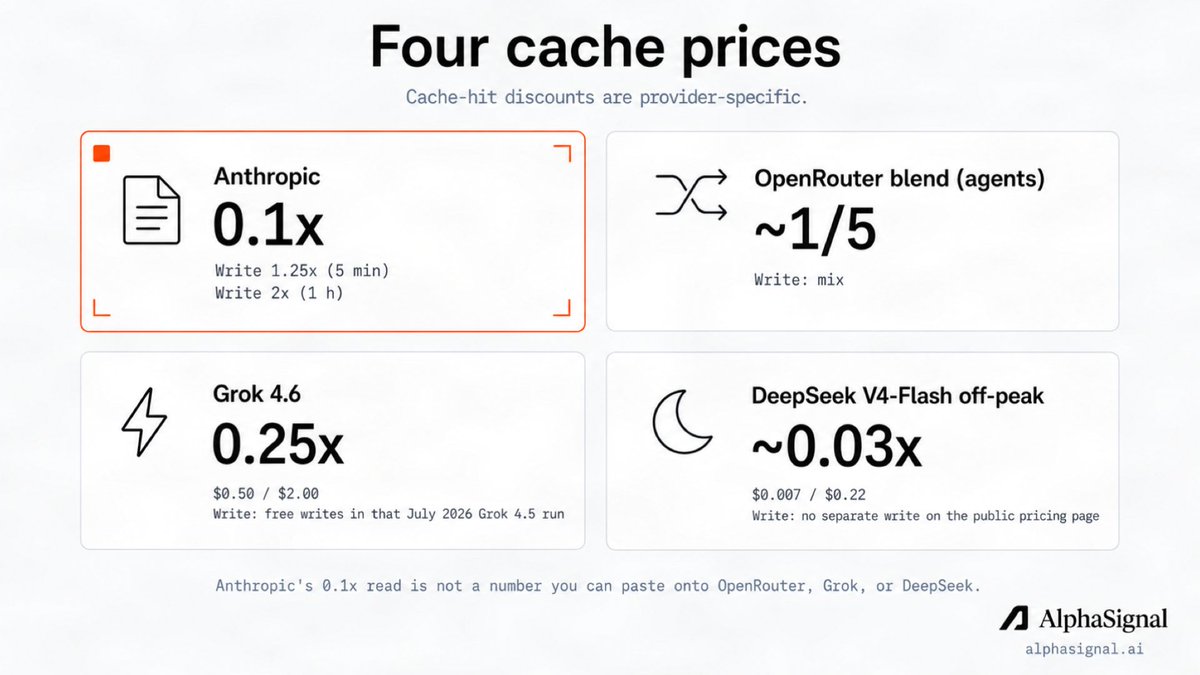 postPrompt cache TTL is a hidden cost in long agent sessions
 articleFull breakdown: Claude-only apps often wait until the host speaks the new revisi
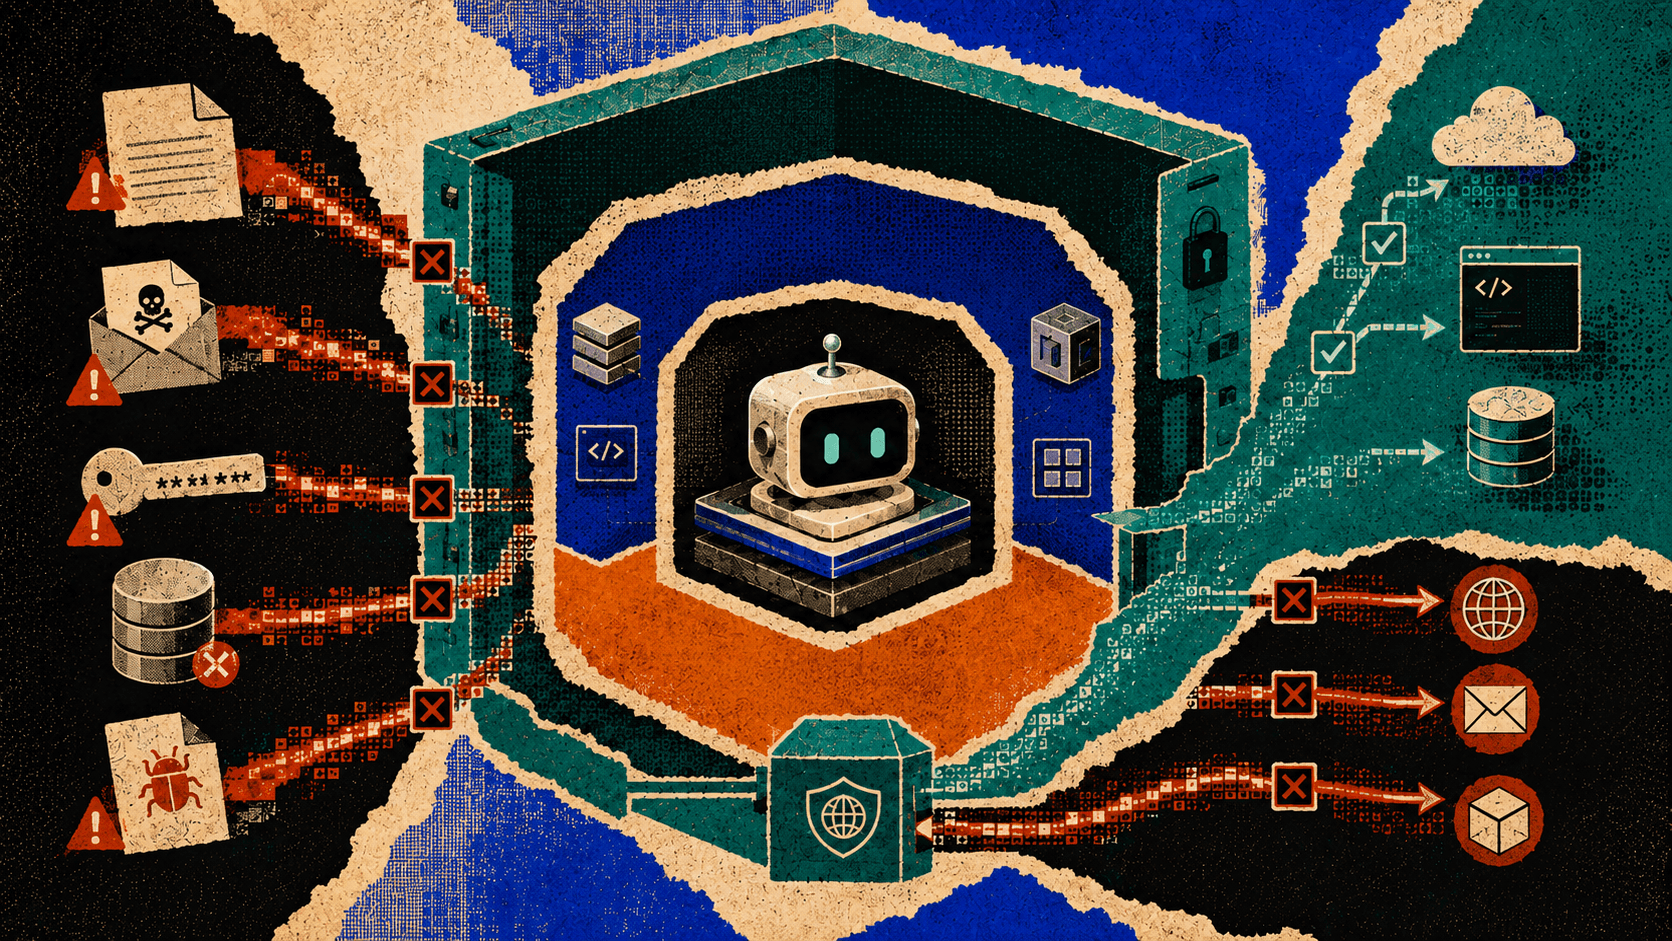 articleDo not ask whether the agent follows the rule. Ask what stops it when it does no
 articleFull Breakdown: When can a change ship unread? When something cheap and hard to
Checking sign-in…
Loading comments…