Validation gains that vanished on sealed SWE-bench tasks
- Source
- x.com
- Date

A self-improving agent can look better in validation and still fail to improve where it counts. Tested GPT-5.6 Sol as an optimizer for two already-engineered SWE-bench agent harnesses. The optimizer read failures, diagnosed recurring problems, and rewrote the worker’s instructions. One edit looked like an obvious success. It doubled its validation score. Then it hit tasks the optimizer had never seen. No net improvement. Another edit looked much less convincing during validation, yet performed better on the sealed test. That changes the problem. > How do you separate real improvement from a lucky gate? > How do you catch regressions hidden behind a higher score? > How much evidence should an agent need before its own edit becomes permanent? The edits did change how the agent approached problems. They pushed it toward different code paths and different fixes. But a better-looking validation result did not reliably tell which behavior should ship.

Self-improving agents are really two systems: One generates changes. The harder one decides what survives. Full experiment and what it means for building self-improving harnesses: https://t.co/WSG6KIMJGH
It reframes self-improvement as two systems, one that proposes changes and a harder one that decides which survive, and shows the usual validation gate is not that decider.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
 articleRecursive Self-Improvement for Agents: 7-Check Persistence GateAlphaSignalAI
 articleOne Recipe, Many Harnesses: What Self-Evolution Encodes Across Languages and ModelsSiqi Yang, Qianlan Yang, Yu-Xiong Wang, Saurabh Pujar, Martin Hirzel
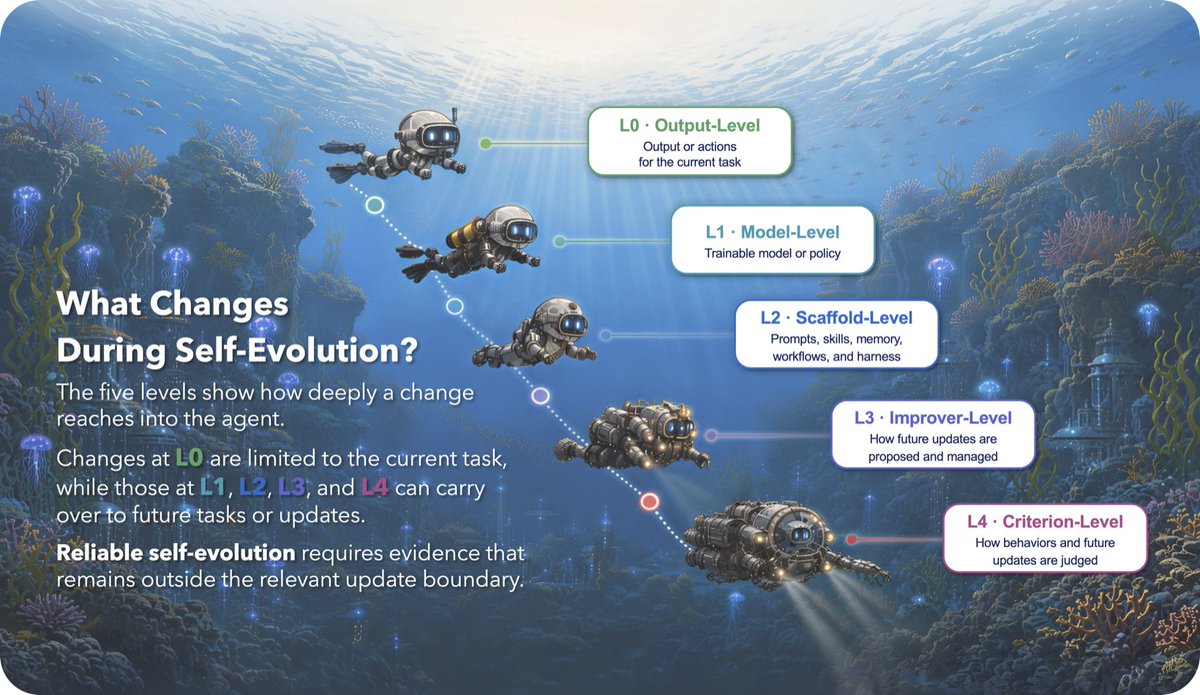 post📄New Research on Self-Evolving Agents: When AI agents modify themselves, how…Tencent Hy
Checking sign-in…
Loading comments…