PaddleOCR-VL: Boosting Multilingual Document Parsing via a 0.9B Ultra-Compact Vision-Language Model
- Source
- unknown
- Date
Context
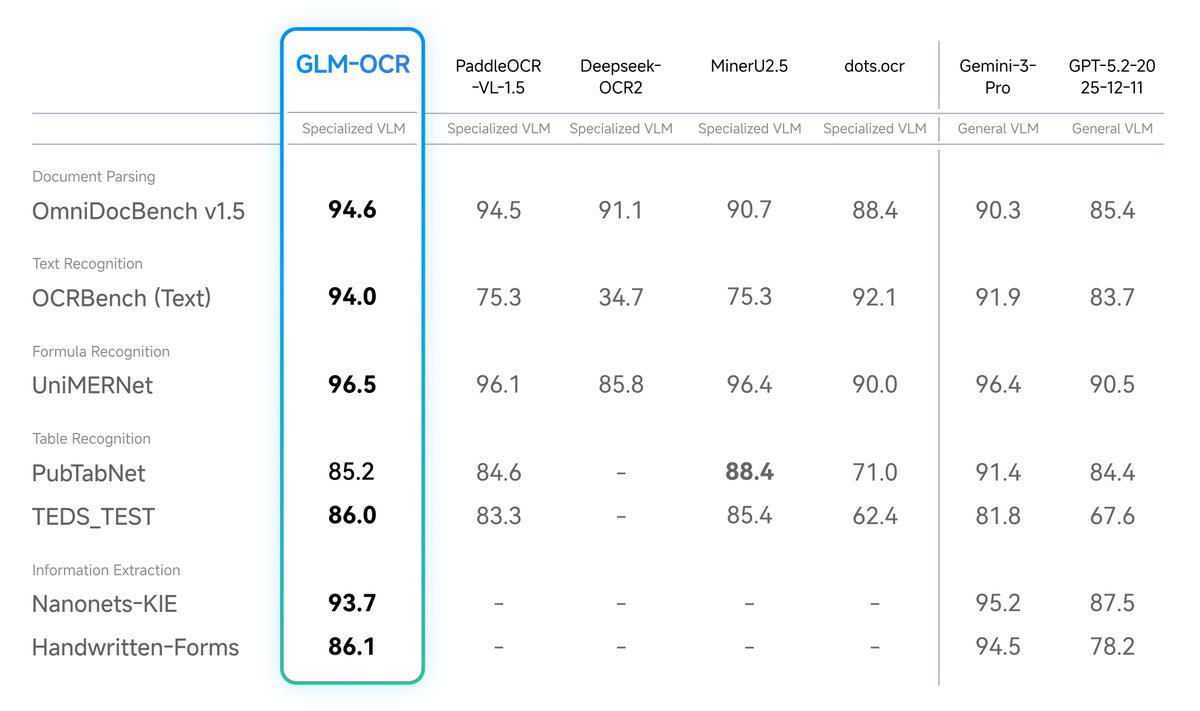
PaddleOCR-VL recognizes several kinds of content within document images, including text, tables, formulas and charts. Baidu's release article describes a 0.9-billion-parameter system combining an image encoder that handles varying resolution with a small . The visual component processes the page's appearance, while the combined model performs document-element recognition.
The release reports support for 109 languages. That breadth makes the system relevant to collections containing different scripts and mixed document elements, where recovering words alone would leave tables and mathematical content unaddressed. The announcement establishes the intended parsing scope; its broad performance claims do not provide a single accuracy figure that applies to every language and document type.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
Checking sign-in…
Loading comments…