Only two labs occupy the Time per Task Pareto frontier: all frontier models unde
- Source
- x.com
- Date

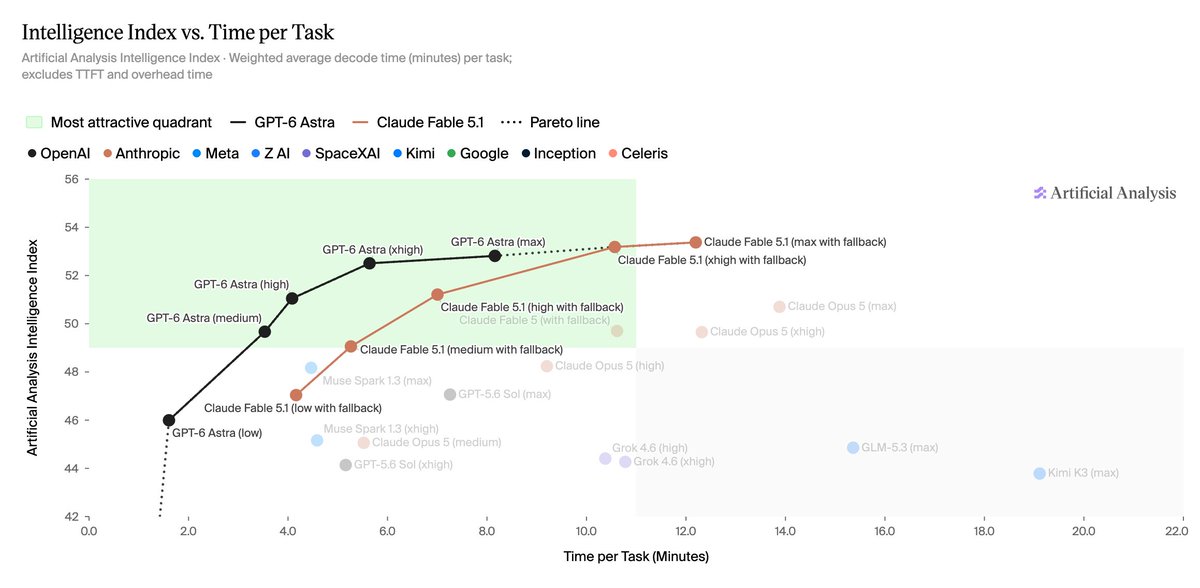
Only two labs occupy the Time per Task Pareto frontier: all frontier models under two minutes are from OpenAI, and four of the six above are from Anthropic We show the tradeoff between the Artificial Analysis Intelligence Index and how long it takes models to complete a representative task in the Index. We calculate Time per Task as the number of output tokens divided by output (decode) speed. Contributors to Time per Task include inference optimizations such as speculative decoding, and model architecture factors (number of active parameters, amount of reasoning). All the models on the frontier under two minutes per task are from OpenAI - but above this, four of the six are Anthropic models. Kimi K3 (max) has a notably high ~11 minutes per task, driven by a low output speed on Moonshot AI’s first party API. Note, the chart only shows models scoring above 25 on the Artificial Analysis Intelligence Index

Context
Artificial Analysis charted how long models take to finish a task against how well they score, and its August 5 chart shows only two labs on the best tradeoff line. A model sits on that line, the Pareto frontier, when no other plotted model is both faster and higher-scoring. Every frontier model that finishes a typical Intelligence Index task in under two minutes is from OpenAI; above two minutes, four of the six frontier models are from Anthropic.
Time per Task is calculated rather than timed. Artificial Analysis divides the number of output a model produces by its output speed, so the figure grows when a model reasons or writes at length and shrinks with faster serving. The evaluator names , the number of active parameters and the amount of reasoning as contributors. The chart labels the figure a weighted average of decode time that excludes the wait for the first token and other overhead.
That makes the result depend on where a model is served as well as on the model. Kimi K3 (max) takes about 11 minutes per task, which Artificial Analysis attributes to low output speed on Moonshot AI's own API. The chart shows only models scoring above 25 on the index. For interactive work, it is a guide to waiting time at each provider's current output speed, and by the formula a faster host would cut a model's time without changing its score.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.




Checking sign-in…
Loading comments…