Synthetic Personas for Market Research: Where LLM Agents Break
- Source
- youtube.com
- Author
- AI Engineer
- Date

Context
Generating more AI survey respondents does not, by itself, provide more evidence about real customers. This presentation on synthetic personas explains that repeated responses can reveal a model's answer distribution more precisely while leaving its mismatch with human behavior unchanged.
The proposed check is comparison with actual human responses, including how answers vary rather than only their average. A model could reproduce the average rating while missing disagreement between customers. For market research, that makes human data the reference for judging a simulated audience, and makes extra model responses useful for examining the simulation rather than enlarging the human sample.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
“I like to say if it's a poorly grounded persona, it's a little like the LLM is playing improv with you.”
Ishan Nand
“They are not people, they are forecasts, and we should treat them accordingly.”
Ishan Nand
“You cannot use statistical synthetic personas to boost statistical significance.”
Ishan Nand
 videoHow to Write Your First AI Eval - SallyAnn DeLucia, Arize AI
 videoBuild Your Own Team of Managed Agents - Jack Wotherspoon, Google DeepMind
 videoHow to Build an AI Code Review Agent - Daksh Gupta, Greptile
 videoHow to Build Voice Agents That Don't Fall Apart When You Interrupt - Jesse Hall, LiveKit
 articleWhen Synthetic Users Fail: A Cross-Domain Benchmark of LLM-Simulated Human Survey ResponsesZihan Chen, Di Zhu, Lei Nico Zheng
 articleMatrAIx: Simulating the World with 8.3 Billion Persona AgentsXiaomin Li, Yuexing Hao, Jianheng Hou, Jintao Huang, Qianfeng Wen, Shirley Huang, Yifan Liu, Xiaoyi Liu, Yilan Fan, Yijun Wang, Koutian Wu, Ruoqi Gao, Muhammad Ahmed Mohsin, Jing Tang, Brihi Joshi, Heming Liu, Zheyuan Deng, Zonglin Di, Sankalp Jajee, Jiuyao Lu, Zhiwei Zhang, Saksham Kapoor, Ishan Gupta, Yunhan Zhao, Chanwoo Park, Yucheng Lu, Bing Hu, Weihang Xiao, Aravind Mohan, Hanwen Xing, Runyu Zhang, Mihir Kulshreshtha, Yuanda Xu, Qianyu Zhu, Dianzhuo Wang, Yuxin Xiao, Bowen Jiang, Yongye Su, Wenhao Chai, Zuxin Liu, Lawrence Yunliang Chen, Xuandong Zhao, Ethan Ye, Shivam Patel, Jason Xie, Alex Martin Richmond, Weixiang Ding, Emre Okcular, Diya Mathew, Ziheng Wang, Rana M. Shahroz Khan, Zhejian Peng, Fang Wu, Fan Nie, Xinyang Han, Yubin Kim, Jiawei Zhang, Zhenting Qi, Huangyuan Su, Xu Pan, Abinitha Gourabathina, Hyewon Jeong, Hemanth Neelgund Ramesh, Kumail Alhamoud, Kimia Hamidieh, Zidi Xiong, Samuel Schmidgall, Pengrui Han, Yepeng Huang, Yongheng Wang, Bowen Yang, Alex Gu, Yuchu Wang, Akshay Paruchuri, Brenna Li, Hejie Cui, Jiayuan Ding, Chaosheng Dong, Jiahao Wang, Yixuan He, Chi Wang, Pamela Bhattacharya, Tianyi Peng, Paul Pu Liang, Mitchell Gordon, Yilun Du, Marinka Zitnik, James Zou, Prasanna Tambe, Philip Torr, Emily Fox, Asu Ozdaglar, Dawn Song
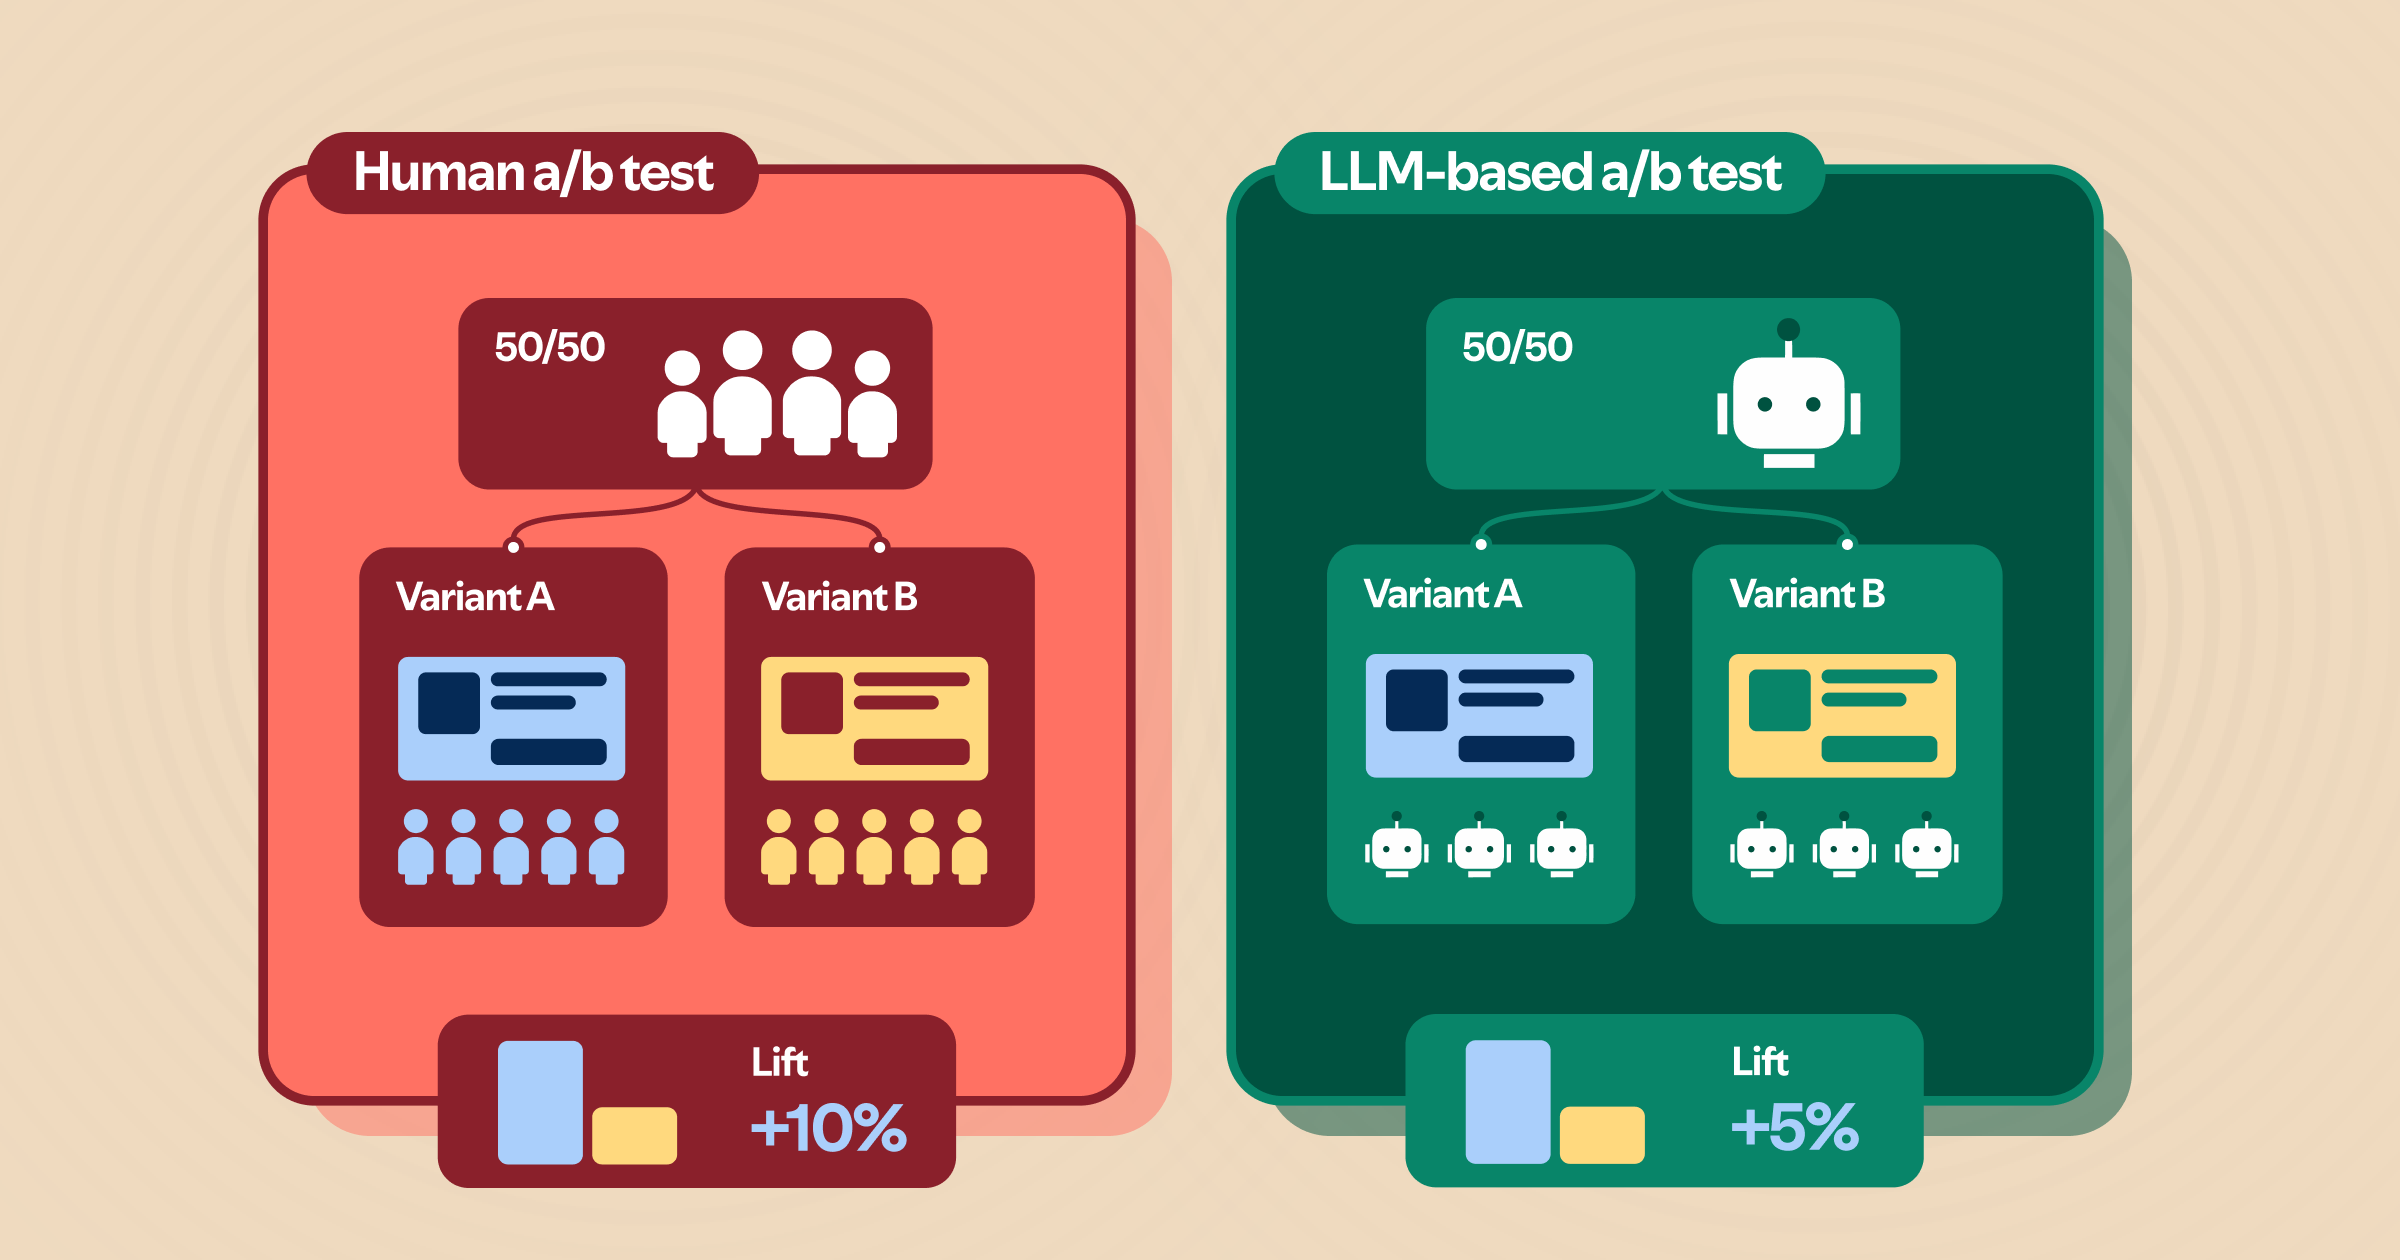 articleWhen Can LLMs Replace Humans in A/B Tests?Spotify Engineering
Checking sign-in…
Loading comments…