← All IntelIntel / article
Introducing Sakana AI’s Security Research Group
- Source
- unknown
- Author
- Sakana AI
- Date
Why it matters
Frontier AI is increasing the volume of disclosed vulnerabilities (NIST reports CVE submissions up 263% from 2020 to 2025). Sakana AI is staffing a group to publish benchmarks and guidelines on AI-driven defense and AI security.
Key takeaways · AI-distilled
- Sakana AI argues faster patching alone will not cut risk: CISA's FY2024-2025 review found attackers mostly use well-known weaknesses, led by input validation and memory safety flaws. The group puts its long-term weight on product quality and system design.
- An FBI FLASH from November 13, cited by Sakana, says threat actors weaponized ARTEX, an open-source -driven pentest platform, for multi-target intrusions. Listed initial-access weaknesses include SSRF, IDOR, missing API auth and injection; no CVE is named.
- Sakana frames security as must-be quality in the Kano model: users do not notice it when present but are strongly dissatisfied when it is missing, so it tends to drop out of quality definitions unless specified as a requirement from the start.
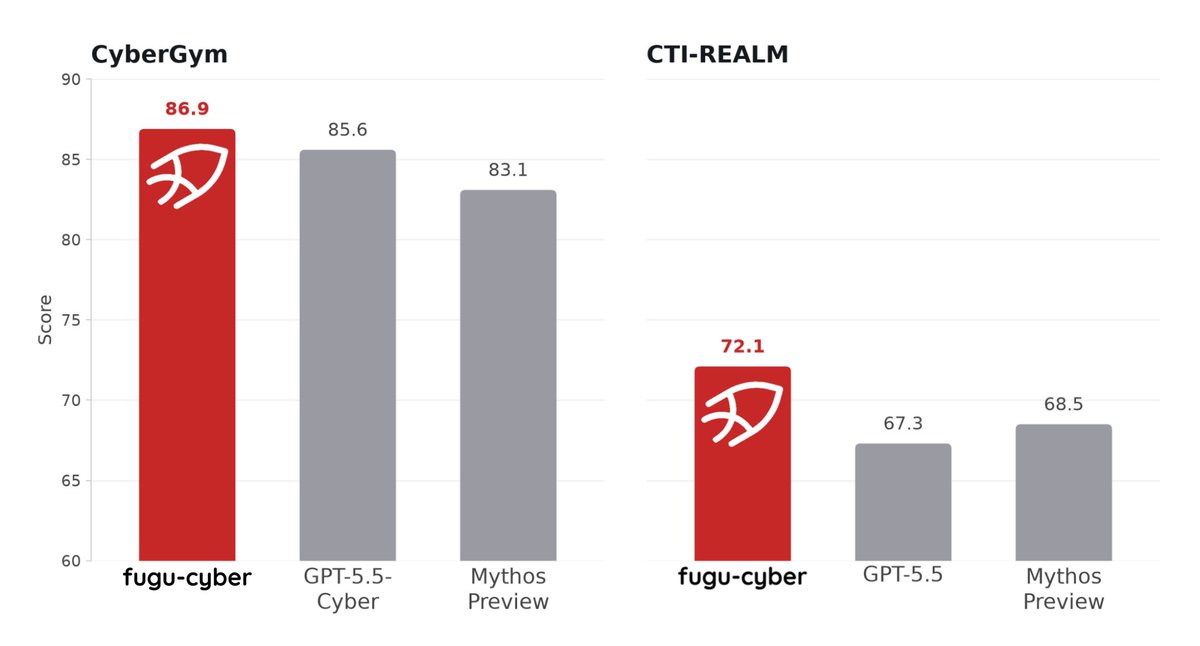
- Sakana reports its Fugu-Cyber orchestration of specialized models scored 86.9% on CyberGym and 72.1% on CTI-REALM, but gives no baselines or setup, and lists the gap between scores and real enterprise environments as an open research question.
- The group says it will publish white papers, benchmarks and defensive playbooks but withhold actionable exploit material, and will test Sakana's own systems under the same reproducible conditions as outside tools, publishing compute budgets and harnesses as needed.
Terms in this piece · Glossary
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- multi-agent — Using several AI agents on one problem — splitting work in parallel, checking each other, or filling different roles like planner and reviewer.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Source link unavailable.unknown
More from Sakana AI
Recommended reads
 articleSakana ships Fugu-Cyber, a gated orchestration endpoint for security workSakana AI
 articleAI Security Priorities: A Field-Wide AgendaGil Gekker, Rachel Steratore, Everett Smith, Asher Brass-Gershovich, Varun Gandhi, Nicole Nichols, Vijay Bolina, Buck Shlegeris, Lisa Einstein, Dan Lahav, Omer Nevo, Sella Nevo
article[AINews] AI Cybersecurity becomes top of mindLatent Space
Comments
Checking sign-in…
Loading comments…