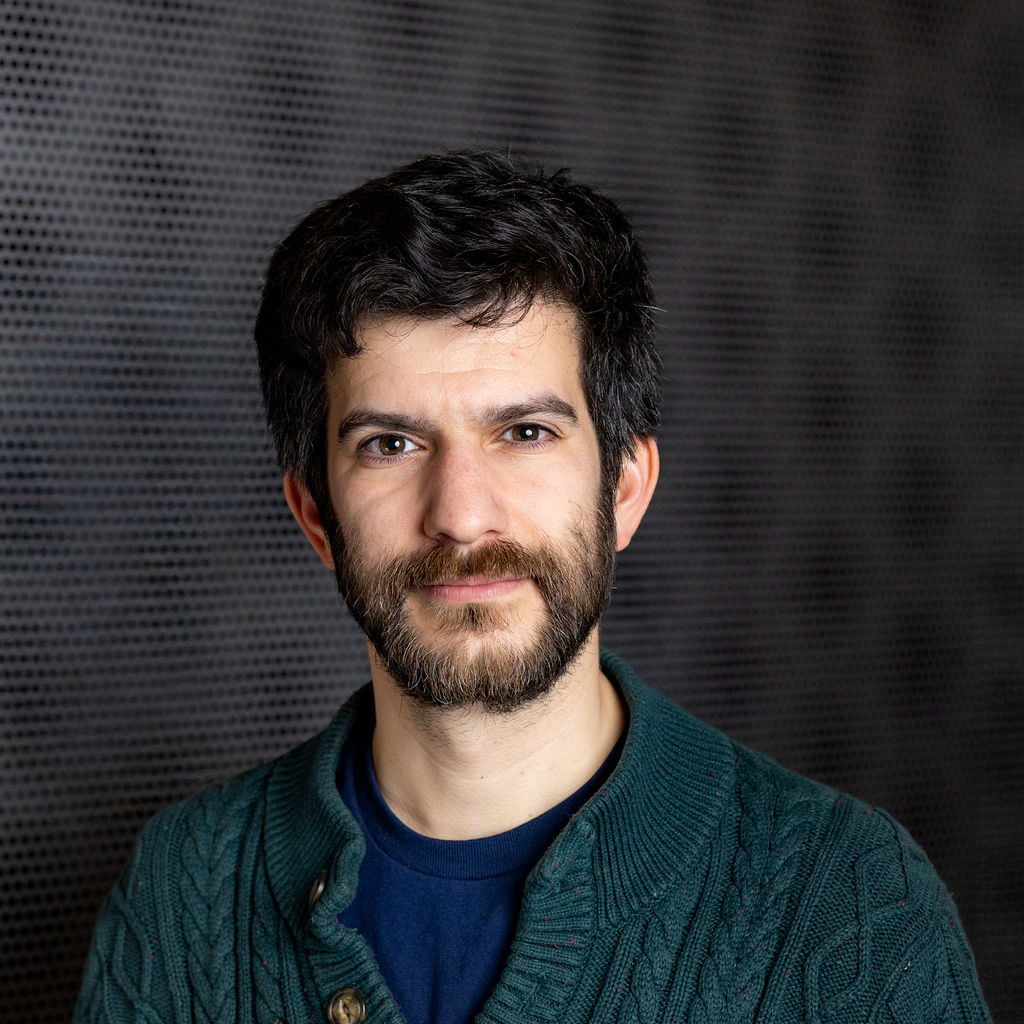
Greg Burnham is head of benchmarks at Epoch AI. He develops evaluations and writes about what benchmark results can reveal about AI capability, learning and the automation of real work.[1][2]
Start with 9 Big questions benchmarks can help answer →
 X
Career
Before Epoch AI, Burnham worked at Elemental Cognition and Bridgewater Associates. He holds a BA in mathematics from Princeton. His current work brings that mathematical background to the design and interpretation of AI evaluations.[1]
Contributions
Evaluating work by its own standards
With Kelly Hong, he co-authored Epoch’s automation report, which gives models tasks drawn from the organization’s actual work. Employees grade outputs against task-specific rubrics, combining objective checks with judgments about clarity and research quality. Examining the agents’ trajectories helps explain why an output failed. The study distinguishes reliable completion of well-defined steps from the judgment needed to choose topics, design experiments and follow through on an open-ended task.[3]
Spatial reasoning in a practical setting
His co-authored Furniture Assembly Benchmark work asks models to find mistakes in photos of partially assembled furniture. The task tests visual and spatial reasoning in a setting connected to physical repair and assembly. It provides a concrete domain to track over time, while the connection to useful real-world assistance remains a question to investigate rather than something established by a score alone.[4]
Ideas
Burnham argues that a benchmark should help answer a larger question than whether a model can complete one narrow task. His examples include whether systems improve through repeated experience, how performance generalizes across domains and whether an agent can complete a messy job rather than a self-contained assignment. He treats measurement as a way to investigate the forces behind AI’s impact, with realism and evaluation cost constraining what can be tested.[2]
Tools, writing & talks
Writing, research & talks
Start here
9 Big questions benchmarks can help answerepochai.substack.comA framework connecting benchmark design to questions about learning, generalization and economic impact.
Begin with the first question about tasks versus whole jobs, then choose one of the nine questions to follow. It requires no technical setup and helps explain why different evaluations measure different things.
Author[2]Original source- Can AI automate Epoch?epoch.ai
An evaluation of models on realistic internal work, graded by the organization’s own standards.
Co-author with Kelly Hong[3] An evaluation of visual and spatial reasoning through photos of partially assembled furniture.
Co-author with Aiden Ament[4]