Jasper Dekoninck is a computer-science PhD student at ETH Zurich studying how to evaluate mathematical reasoning in language models. He leads MathArena and researches problems ranging from competition answers to research-level and formal proofs.[1][2][3][4]
Start with Beyond Benchmarks: MathArena as an Evaluation Platform for Mathematics with LLMs →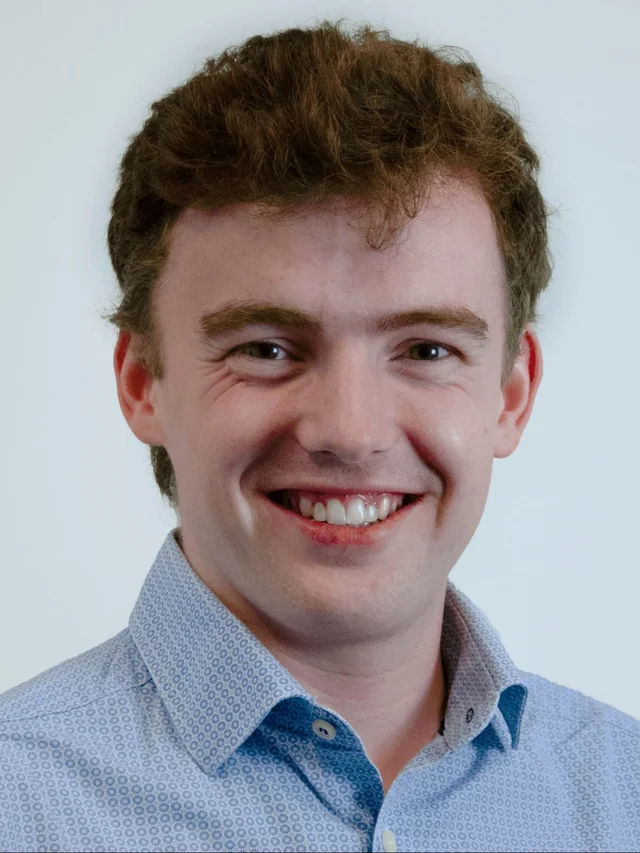
Education

Links
ETH profile X · j_dekoninck
 GitHub · JasperDekoninck
Background
Dekoninck studied mathematics and physics at KU Leuven from 2018 to 2021, then completed a data-science master’s at ETH Zurich from 2021 to 2023. He began his computer-science doctorate in November 2023 in the Secure, Reliable, and Intelligent Systems Lab. His research combines mathematical problem design with the practical question of what a model’s score actually measures.[2]
Contributions
The 2026 MathArena paper broadens the original competition benchmark into a maintained evaluation platform. It brings together final-answer problems, proof-based competitions, research-level questions and formal Lean proofs. A consistent protocol makes results easier to compare, while new tasks keep the evaluation challenging as older tests saturate. Dekoninck is first author of this platform paper and a coauthor of the earlier MathArena benchmark.[1][3]
Ideas
His research portfolio also includes BrokenMath, which probes sycophancy in theorem proving, and work evaluating proof quality beyond correctness. These projects distinguish generating a plausible mathematical response from satisfying the task’s actual requirements. The broader program asks how benchmarks can reveal failures that disappear when evaluation is reduced to a single final-answer score.[1]
Tools, writing & talks
Writing, research & talks
Start here
A maintained platform covering several kinds of mathematical reasoning tasks.
Start with the task categories and evaluation protocol. Basic familiarity with model evaluation helps; the overview explains why final answers and full proofs require different checks.
First author[3]MathArena gave four frontier agents 48 hours and a $500 key to write a publishable blog post. Two GPT-6 variants and GLM-5.3 produced off-topic or weak output, while Opus-5.5 built UnBrokenArXiv with usable findings.
Catalog workOriginal source- MathArena research portfoliosri.inf.ethz.ch
Papers and project links on mathematical evaluation, proofs and benchmark reliability.
Researcher and coauthor of the listed work[1]