Can LLMs write interesting and novel blog posts for MathArena?
We give four agents 48 hours and a $500 API key to create an interesting MathArena blog post.
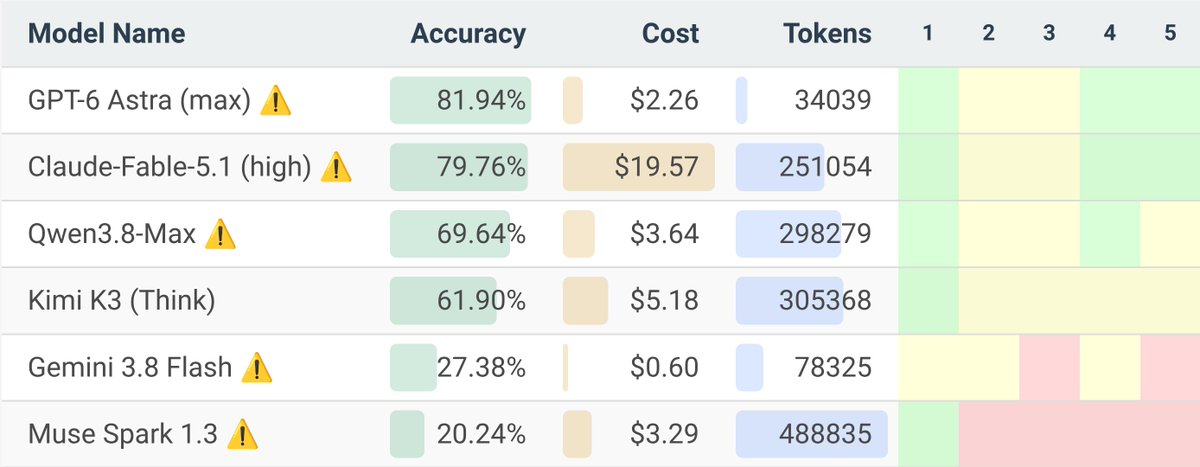
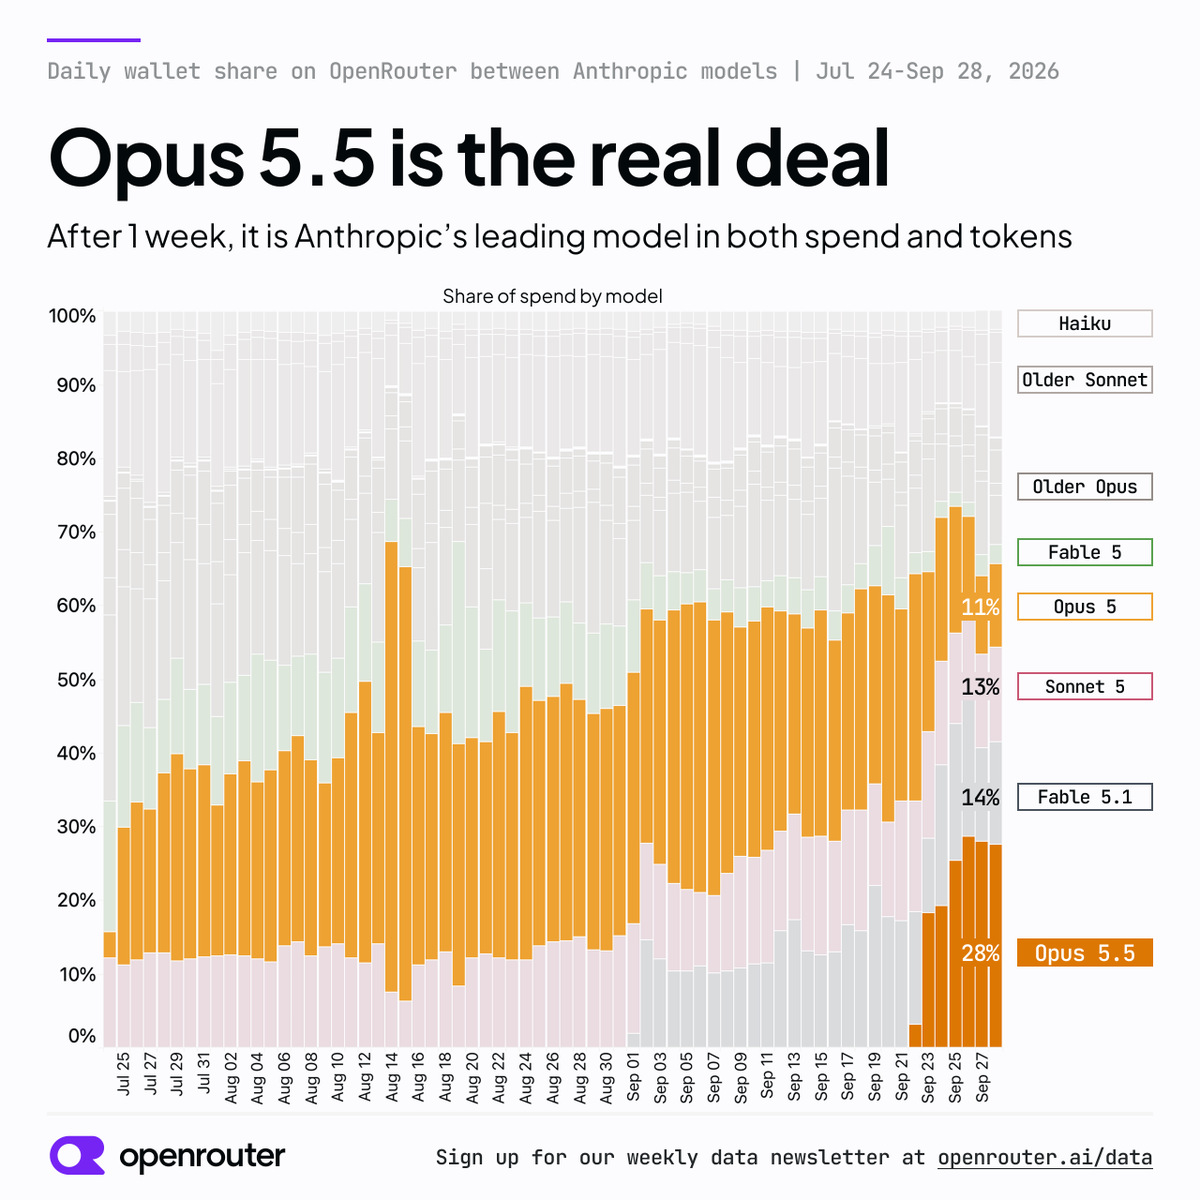
GPT-6 Astra, GPT-6.1 Sol, and GLM-5.3 produced slop. Opus-5.5 created a good blog post with interesting conclusions.
Offers an open-ended, budget-capped benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → for long-horizon AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → research work, with a concrete finding that only one of four frontier agents produced a usable post.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.