Shreya Shankar is a computer scientist who builds systems for reliable, economical processing of documents with language models. She is a Visiting Assistant Professor at Carnegie Mellon and developed DocETL during her Berkeley PhD. She also teaches AI evaluation with Hamel Husain.[1][2]
Start with DocETL →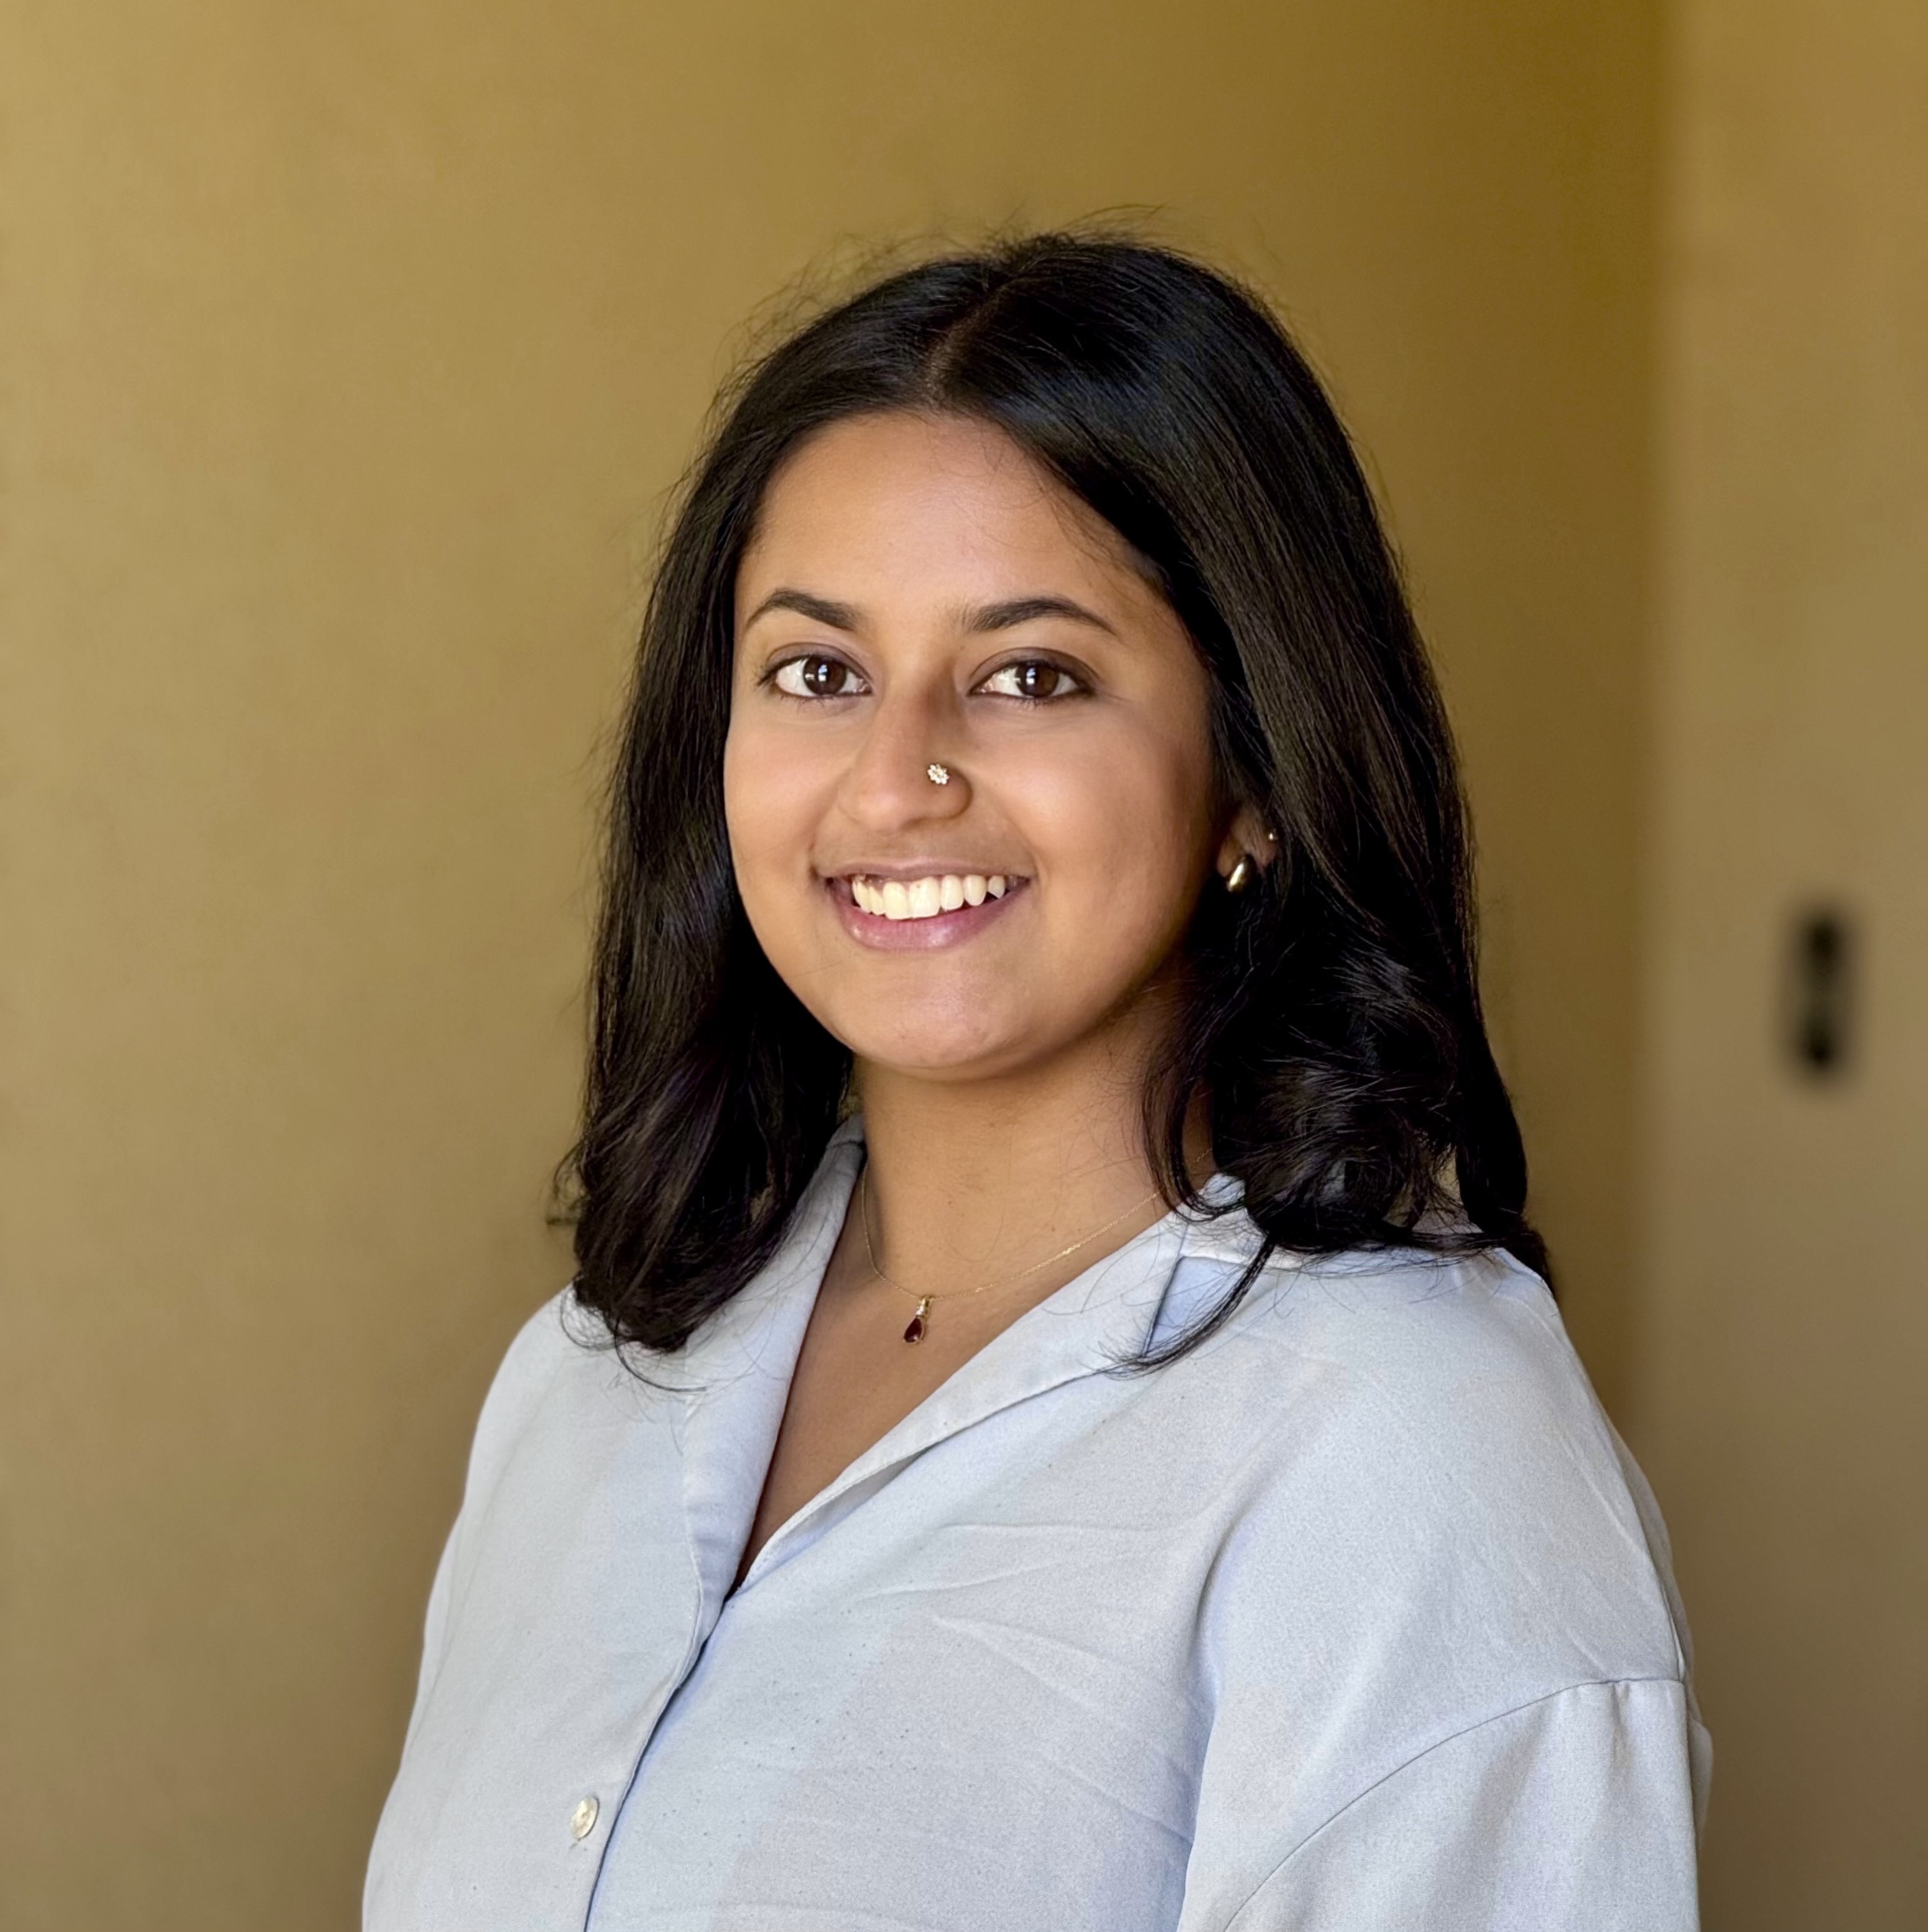
Education
Links
Website GitHub
 X Google Scholar
Visiting Assistant Professor · Carnegie Mellon University
Career
Shankar’s academic work combines data management with the practical difficulties of using imperfect model outputs. Her CV records a Berkeley EECS PhD from 2021 to 2026, a part-time Stanford computer science MS from 2018 to 2020, and a Stanford CS BS from 2015 to 2019. She became a Visiting Assistant Professor at Carnegie Mellon in July 2026; her tenure-track Assistant Professor appointment is scheduled for July 2027.[2]
Contributions
Changing the plan, not only the prompt
DocETL addresses document tasks that remain difficult even after careful prompting. A model asked to extract every relevant clause from a long document may miss material; the system can instead split the document or decompose the task and combine the results. Shankar and her co-authors define rewrite directives and an agent-guided search that compares alternative processing plans. The paper evaluates the approach on four document-analysis tasks. Its central contribution is making the pipeline itself something the system can optimize for accuracy.[3]
From documents to tables
The open-source DocETL stack lets a user specify operations such as mapping, filtering, and reducing in natural language, then orchestrates model calls over structured or unstructured data. It can return tables for later querying. DocWrangler adds an interactive interface for refining prompts and inspecting results. The repository connects these tools to the research papers and credits the Berkeley groups that developed them, giving users both an implementation and the rationale behind its behavior.[4]
Evaluations begin with the actual errors
With Hamel Husain, Shankar teaches a course on evaluation for people building AI products. It covers inspecting failures, creating task-specific tests, using model judges, and collecting useful human feedback. The course focuses on processes that transfer across vendors and on multi-step systems where a final failure can originate in several different components. It is aimed at people already building an application rather than an introduction to prompting.[5]
Research and teaching beyond DocETL
Her personal site links work on interactive debugging for retrieval-augmented generation, cost-aware semantic data processing, and benchmarks for data agents. It also announces Evals for AI Engineers, an O’Reilly book co-authored with Husain. These projects share a practical concern: helping people inspect, measure, and improve an AI system rather than judging it from a small set of convincing demonstrations.[1]
Tools, writing & talks
Tools
Start here
DocETLgithub.comA declarative system that orchestrates and optimizes language-model document-processing pipelines.
Start with the repository’s support-ticket example to see natural-language operations produce a table. Running it needs Python and a model-provider key; the paper explains why decomposing a task can improve extraction.
Writing, research & talks
- [Paper Club] DocETL: Agentic Query Rewriting + Eval for Complex Document Processing w Shreya Shankaryoutube.com
A paper club walks through DocETL, which gives formal operators for LLM document pipelines and uses agentic query rewriting plus evaluation to raise accuracy on complex extraction tasks.
Catalog workOriginal source - [Lightning Pod] Evals: How to Improve AI Consistently — with Hamel Husain and Shreya Shankaryoutube.com
Hamel Husain and Shreya Shankar discuss why AI products stall beyond demos and how error analysis and systematic evals provide a path for measuring and improving LLM applications.
Catalog workOriginal source - Why AI evals are the hottest new skill for product builders | Hamel Husain & Shreya Shankaryoutube.com
Two eval experts lay out a lightweight process for evaluating AI products: open-code real traces with a single trusted domain expert, avoid committee overhead, and treat evals as an actionable improvement loop.
Catalog workOriginal source - DocETL research paperarxiv.org
Explains agent-guided query rewrites and evaluation for complex document analysis.
First author with four co-authors.[3] A course on failure analysis, task-specific tests, model judges, and human feedback for AI applications.