Claude Opus 5.5 Intelligence, Performance and Price Analysis (Max)
Source
artificialanalysis.ai
Author
theanonymousone
Date
Context
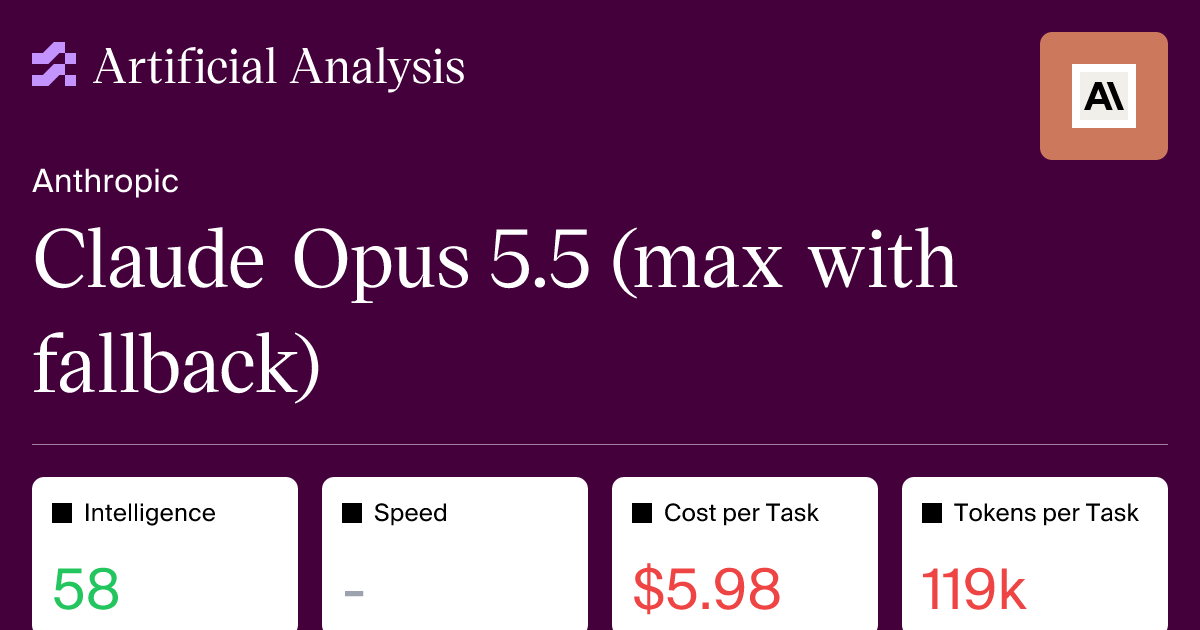
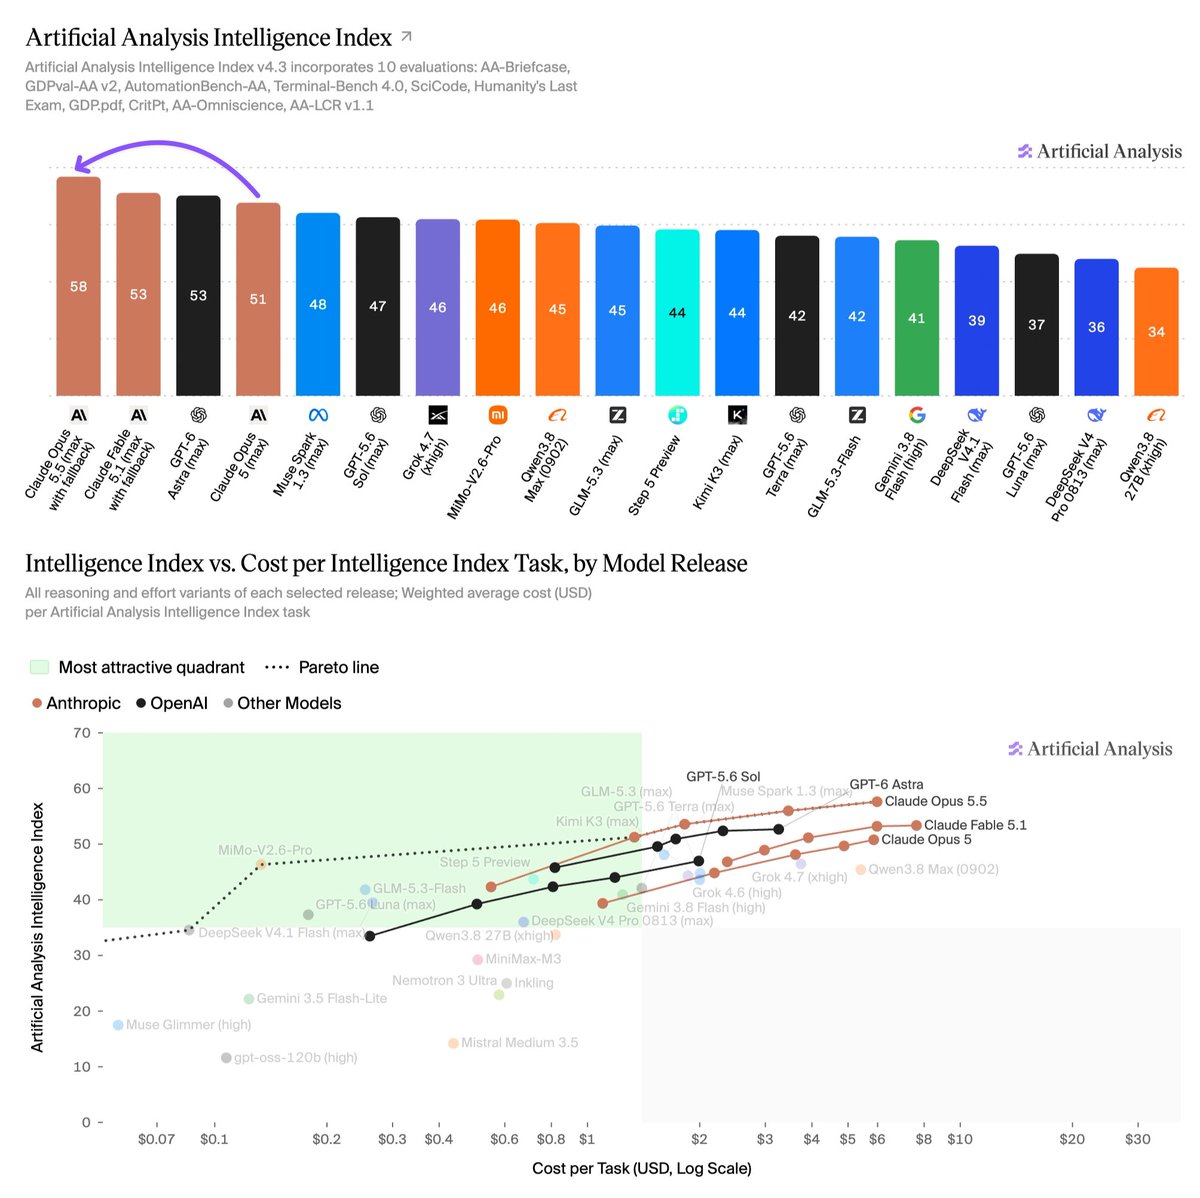
Artificial Analysis evaluates Anthropic's Claude Opus 5.5 at its Max setting on two separate questions: how well it performs and what it costs to run. Its evaluation page reports an Intelligence Index score of 58, a composite of multiple tests. The cost figure is built from the model's prices and the amount it processes and generates across those tests, counting new input, cached input, reasoning and answers. A model's bill therefore depends on how much work it produces before answering, not only on the price of a fixed amount of text.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.