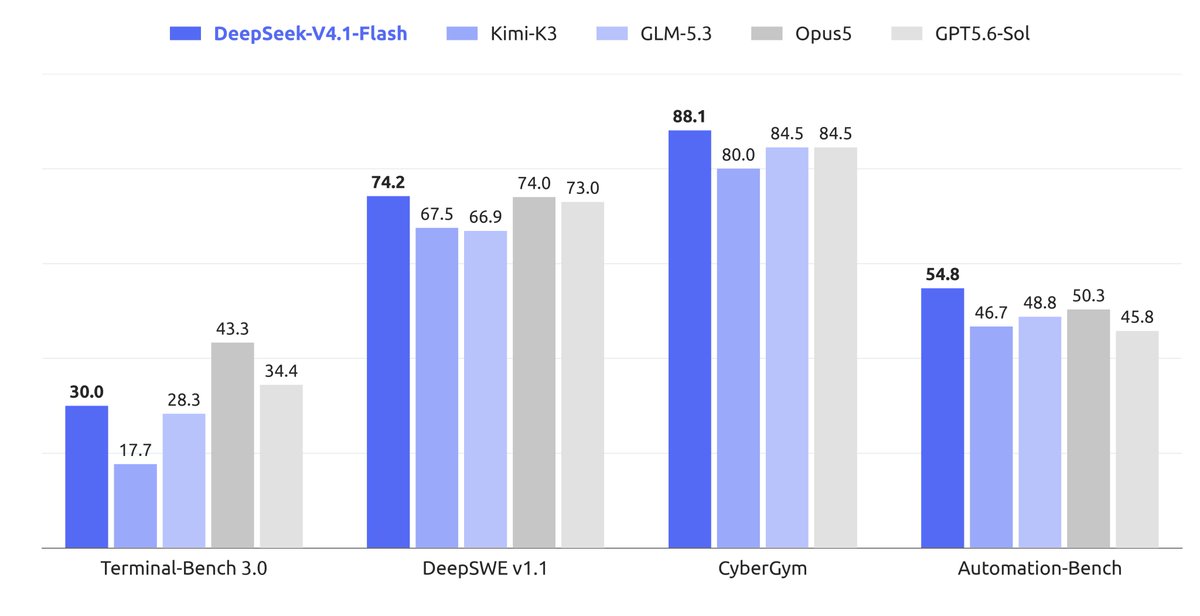
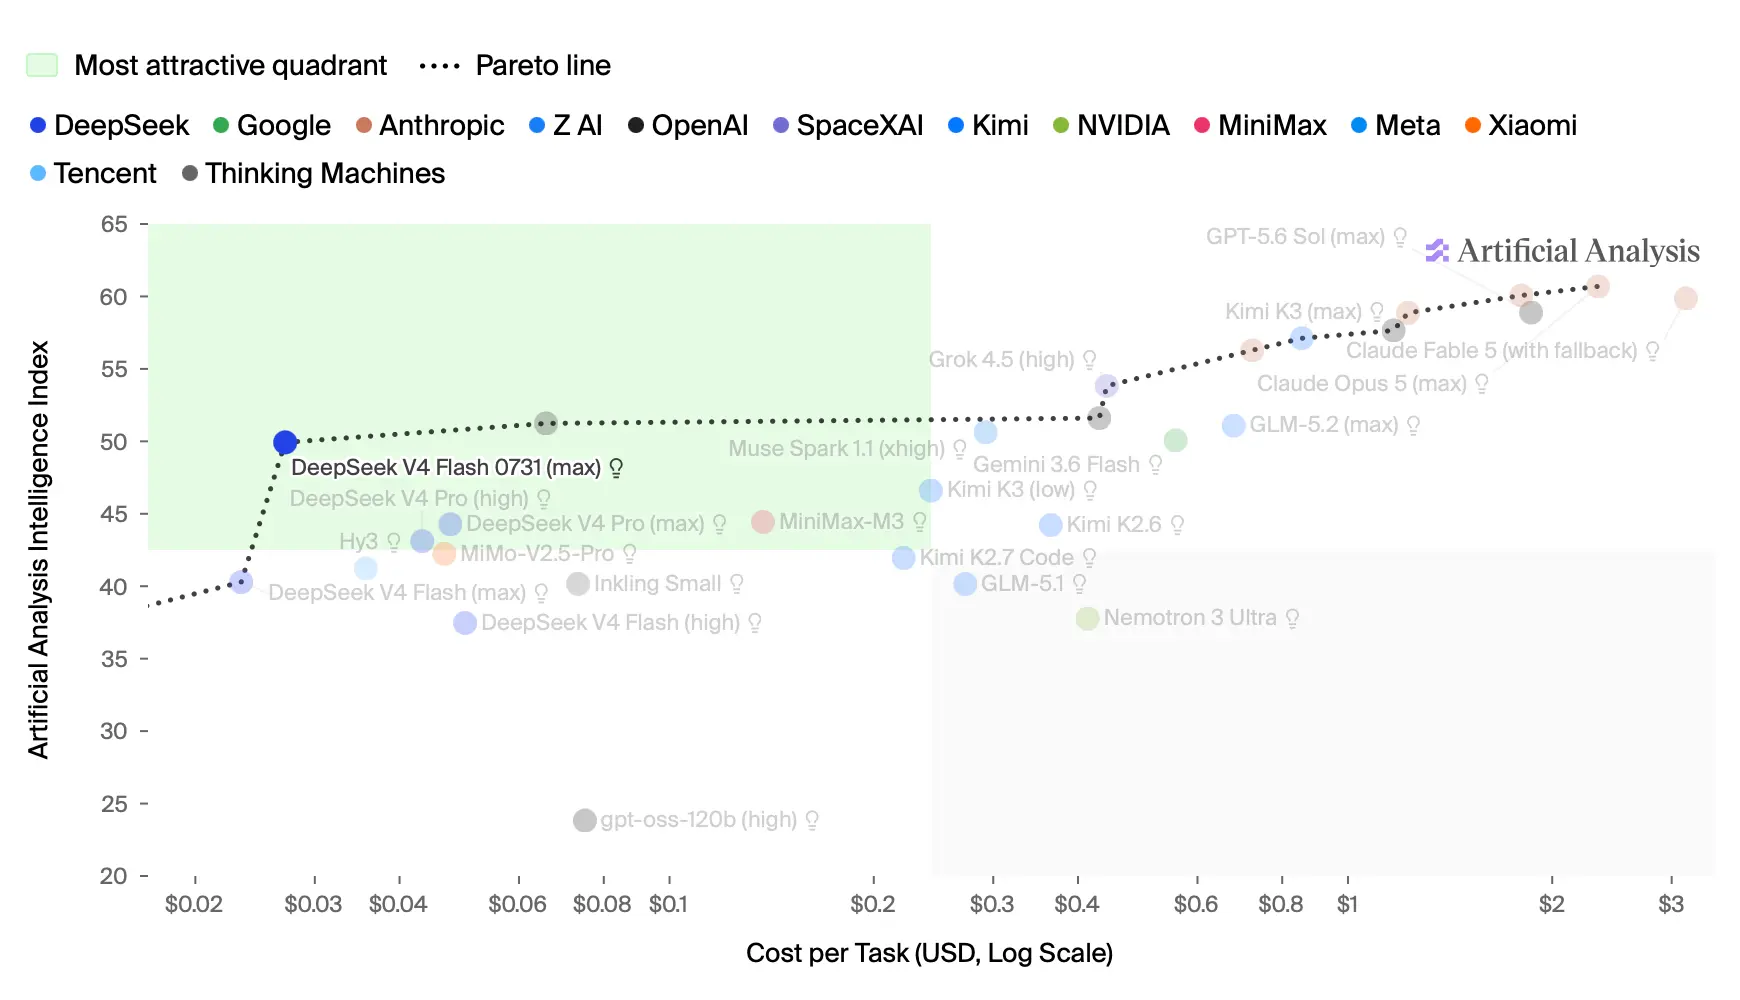
A cheap 1M-context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → model aimed at coding and computer-use agents, with compressed KV cacheThe memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.Full definition → that lowers cost on long agentic runs.
Terms in this piece · Glossary
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.