Copilot Fusion nears Opus 5.5 coding scores at half the cost per task
- Source
- x.com
- Date

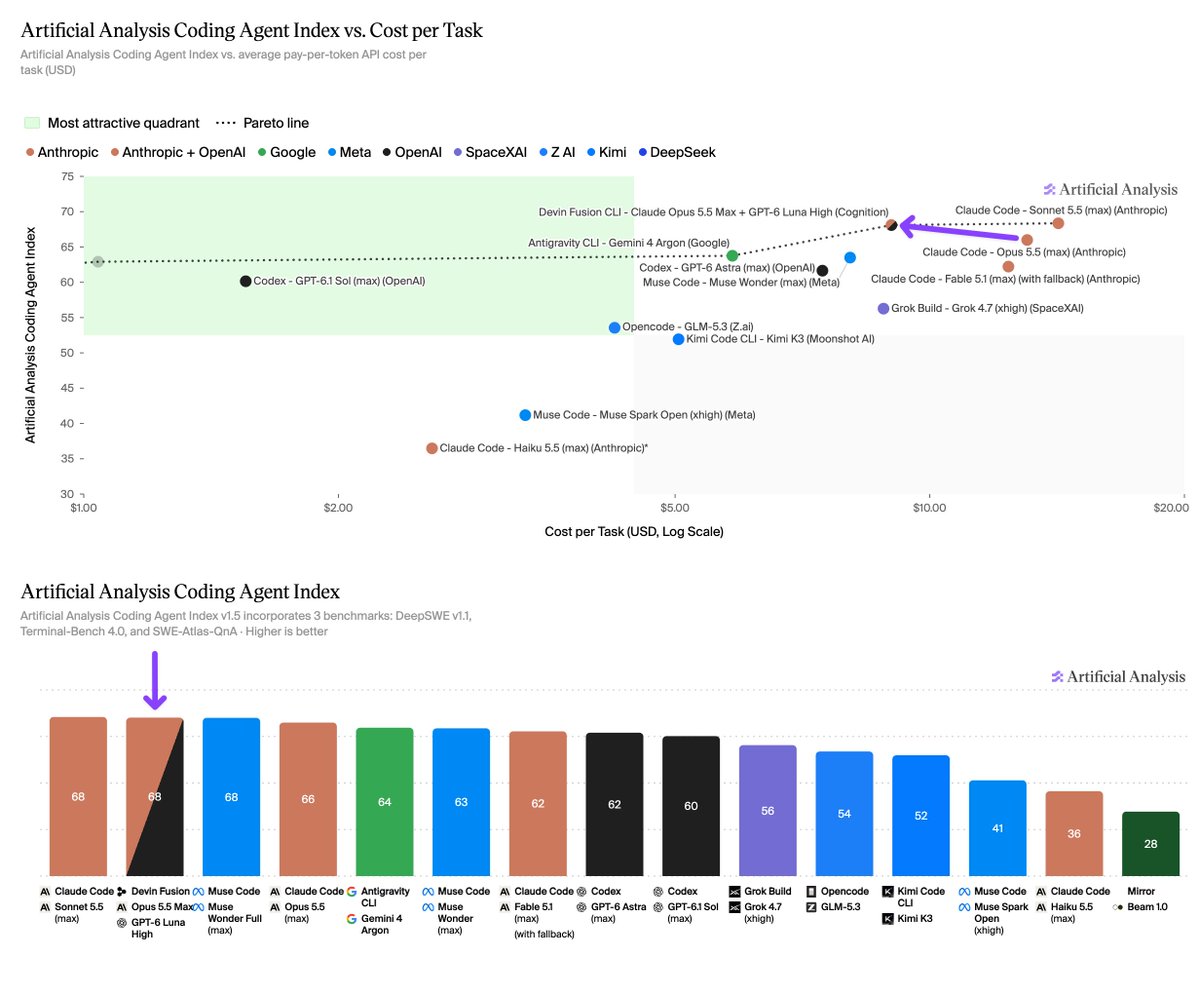
GitHub has released Copilot Fusion in GitHub Copilot, which orchestrates between Anthropic and OpenAI models. It scores 2 points below Opus 5.5 in Claude Code at half the Cost per Task in the Coding Agent Index GitHub describes Copilot Fusion as a runtime orchestration system, which selects and coordinates models to optimize performance, cost, and latency for each task. Copilot Fusion chooses between a number of models from Anthropic and OpenAI, including Claude Opus 5.5, Claude Sonnet 5.5, GPT-6 Astra, and GPT-6 Sol. We benchmarked its max setting in GitHub Copilot CLI in the Artificial Analysis Coding Agent Index v2.0. Token costs are charged based on the underlying models used to complete a request. Key takeaways: ➤ Cost-efficient for near-frontier performance: Copilot Fusion in GitHub Copilot costs $5.59 per task, versus $11.42 for Claude Code with Opus 5.5 (max). Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) scores 62 at $8.00 per task. ➤ Slight lead in Terminal-Bench 4.0: The Coding Agent Index v2.0 weights its three constituent benchmarks equally. Copilot Fusion in GitHub Copilot leads Terminal-Bench 4.0 with a score of 71. It ranks third on FrontierCode in the…

Context
GitHub's new Copilot Fusion spreads coding work across several Anthropic and OpenAI models instead of running one, and on Artificial Analysis's Coding Index it lands 2 points below Claude Code running Claude Opus 5.5 at half the cost per task. In Artificial Analysis's test of Fusion's max setting in GitHub Copilot CLI, it cost $5.59 per task against $11.42 for Claude Code with Opus 5.5 at max effort.
GitHub describes Copilot Fusion as a runtime orchestration system: for each task it selects and coordinates models to balance performance, cost and latency. The models it can choose from include Claude Opus 5.5, Claude Sonnet 5.5, GPT-6 Astra and GPT-6 Sol, and users are charged for the of whichever underlying models handle the request. Fusion also used far fewer tokens: 7.2 million tokens per task, about half of what Opus 5.5 used in Claude Code and 30% less than Devin Fusion, an earlier multi-model agent that pairs Opus 5.5 with GPT-6 Luna and scores 62 at $8.00 per task. Devin Fusion's arrival on the index was covered in September, and GitHub's own documentation of Fusion's routing and critique patterns is also in Intel.
The near-parity overall hides an uneven profile. Version 2.0 of the index weights its three benchmarks equally, and Fusion leads only one of them: it tops Terminal-Bench 4.0 with 71. On FrontierCode it ranks third at 51, behind Claude Code with Opus 5.5 (56) and Devin Fusion (54), and on SWE-Atlas-QnA-AA it lags at 57, between GPT-6 Astra in Codex and Gemini 4 Argon in Antigravity CLI. Artificial Analysis benchmarked only the max setting, and because Fusion chooses its models task by task, the per-task cost in other workloads depends on which models it routes to. GitHub's release post was not part of the evidence here, so the description of how Fusion works is GitHub's account as relayed by Artificial Analysis.




Checking sign-in…
Loading comments…