Devin Fusion matches top coding agents at lower cost per task
- Source
- x.com
- Date

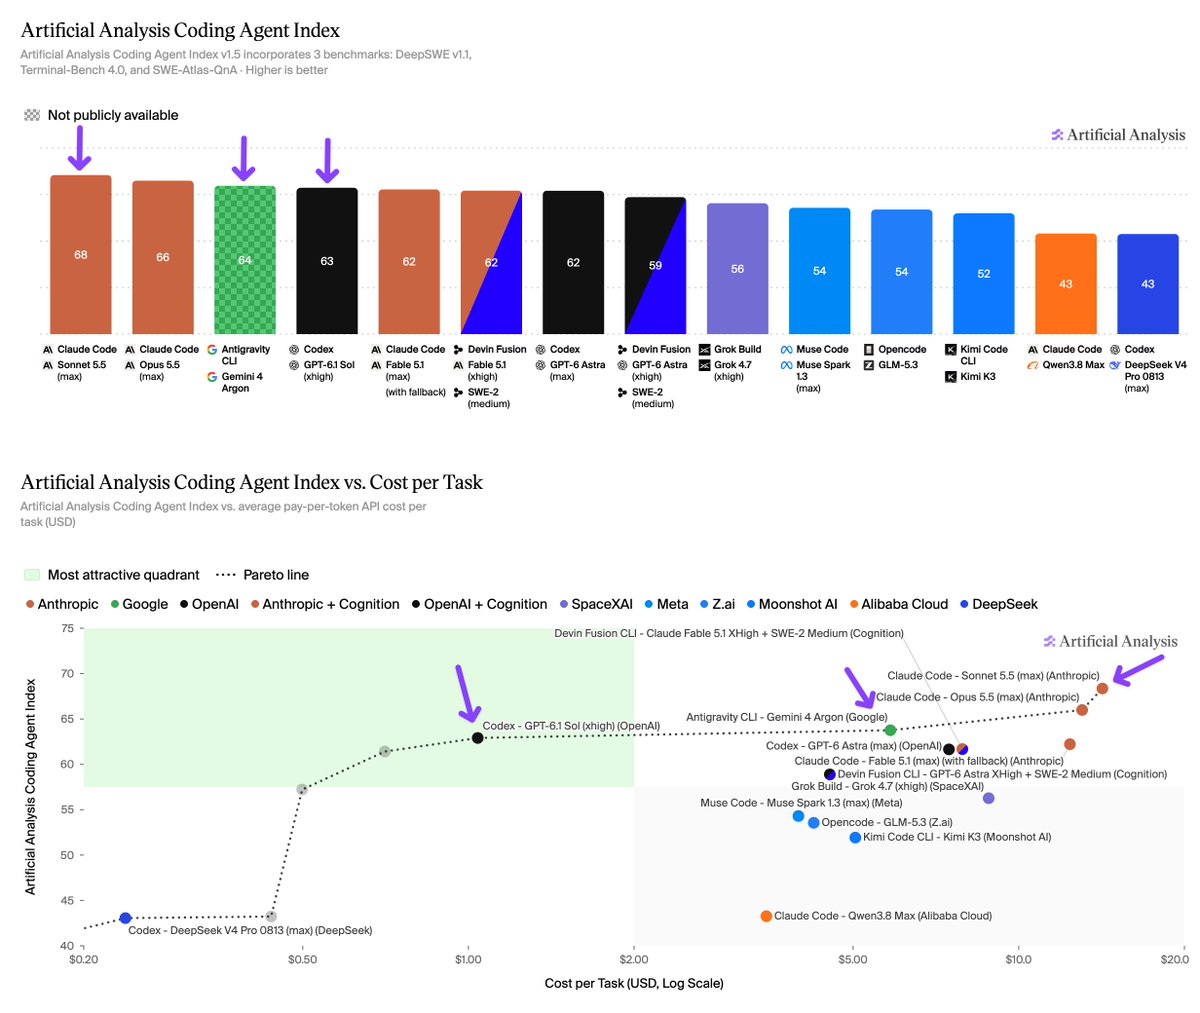
Devin Fusion with Claude Opus 5.5 (max) and a GPT-6 Luna (high) sidekick scores 68 on the Coding Agent Index, 2 points above Claude Code with Opus 5.5 (max) at 31% lower cost per task @cognition's Devin Fusion runs a frontier lead model alongside a lower-cost sidekick model. The two work in parallel with their own context and tools, with the lead keeping planning, delegation and final review. We benchmarked Devin Fusion CLI with Claude Opus 5.5 (max) + GPT-6 Luna (high). It scores 68.1 on the Artificial Analysis Coding Agent Index, closely matched at the top with Claude Code with Claude Sonnet 5.5 (max) at 68.4 and Muse Code with Muse Wonder Full (max) at 68.0. Against Claude Code with Claude Opus 5.5 (max) at 66.0, it costs $9.01 vs. $13.04 per task and averages 55 vs. 65 minutes per task. Across the three benchmarks, the Fusion configuration scores higher on DeepSWE v1.1 (72.6% vs. 68.4%) and SWE-Atlas-QnA (69.6% vs. 66.4%) and slightly lower on Terminal-Bench 4.0 (62.1% vs. 63.1%). Its results reflect both models working together, including their combined API cost. Costs are pay-per-token API costs, not subscription prices.

A lead-plus-sidekick configuration scored 68.1 versus 66.0 for plain Claude Code on Opus 5.5, at $9.01 versus $13.04 per task. Splitting work across a frontier and a cheaper model can cut agent cost without losing accuracy.
- Devin Fusion runs a frontier lead model and a cheaper sidekick in parallel, each with its own and tools, while the lead keeps planning, delegation and final review. Artificial Analysis tested Claude Opus 5.5 (max) leading GPT-6 Luna (high).
- The pair scored 68.1 on the Coding Index, closely matched with Claude Code on Sonnet 5.5 (max) at 68.4 and Muse Code at 68.0, and averaged 55 minutes per task against 65 for Claude Code on Opus 5.5 (max).
- The gain is uneven: Fusion beat Claude Code on Opus 5.5 on DeepSWE v1.1 (72.6% vs 68.4%) and SWE-Atlas-QnA (69.6% vs 66.4%) but trailed on Terminal-Bench 4.0 (62.1% vs 63.1%). Reported costs are combined pay-per- API costs, not subscriptions.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.

Checking sign-in…
Loading comments…