Vals AI Launches Terminal-Bench 4.0 With Stricter Pass/Fail Grading
- Source
- x.com
- Date
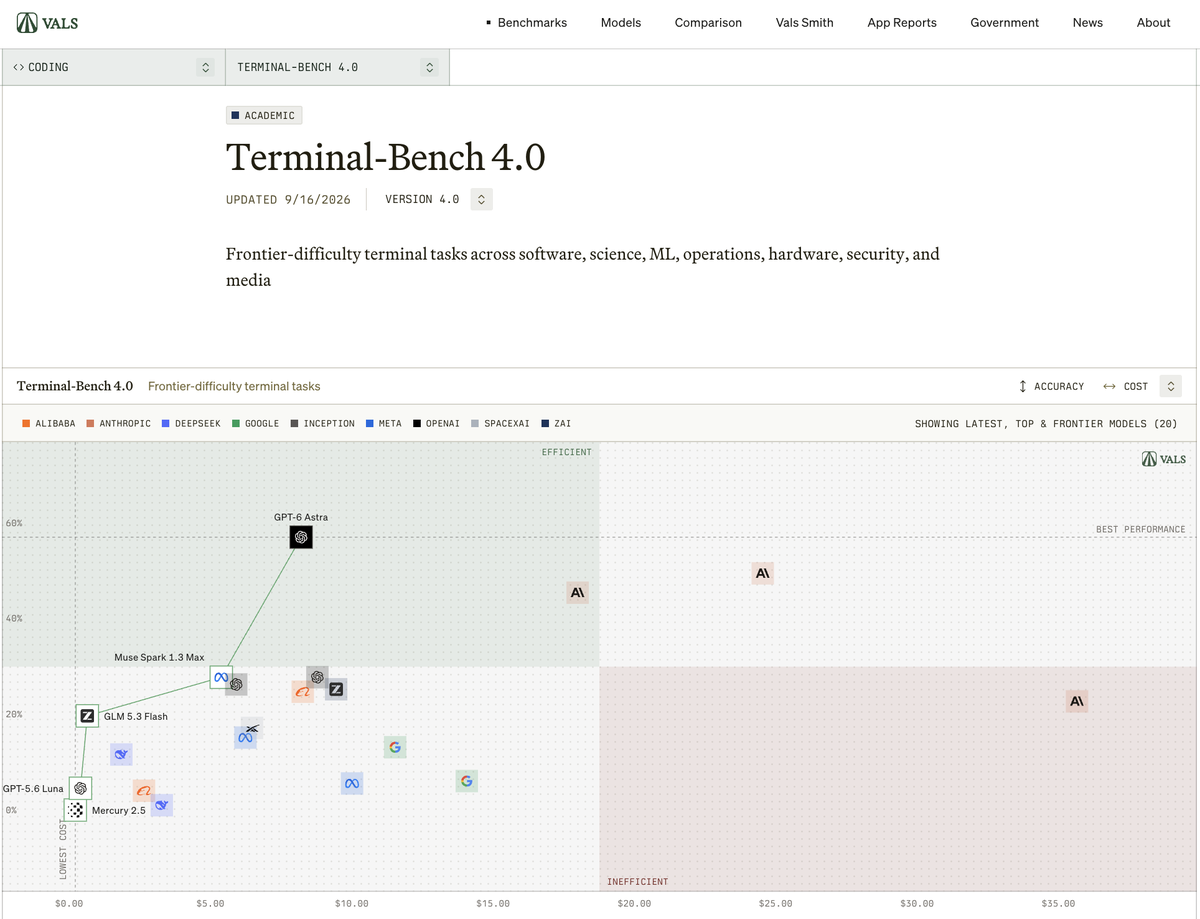
Vals AI launched Terminal-Bench 4.0, a harder version of its terminal task benchmark for coding agents. The new suite adds 66 tasks such as shipping a working service, proving a theorem, and training a GPU kernel, each estimated at roughly four hours of expert human work to complete. Grading is strict pass or fail through full verifier suites rather than partial credit, and each task runs three times with the score averaged across runs to reduce noise from lucky attempts. Earlier terminal benchmarks often rewarded partial progress or single lucky runs, which let agents post strong scores without reliably finishing real engineering work end to end. The stricter format is designed to close that gap and give a more realistic signal of whether an agent can complete multi hour tasks without human intervention. For teams evaluating coding agents, a benchmark built around longer, all or nothing tasks is a better proxy for production reliability than shorter single turn tests, though it also means scores will likely look lower across the board than on earlier, more forgiving versions of the benchmark.

Terminal-Bench 4.0 is now live on Vals. It is a benchmark of 66 new tasks that ask an agent to do real terminal work from start to finish, like shipping a working service, proving a theorem, training a GPU kernel, or writing a forensic report. The median task is estimated at 4 hours of expert work, and grading is strict, so a model either clears the full verifier suite or scores nothing. Every score is avg@3: three pass@1 runs, averaged.
Context
Vals AI launched Terminal-Bench 4.0, a set of 66 new tasks that ask an to complete real terminal work end to end, such as shipping a working service, proving a theorem, training a GPU kernel, or writing a forensic report. Vals AI's post says the median task is estimated at about 4 hours of expert human work, and grading is strict: a model either passes the complete verifier suite for a task or scores nothing on it, with no partial credit for getting most of the way there. Each model's reported score averages three separate pass/fail attempts rather than a single run, reducing the chance that one lucky attempt inflates the result.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
 postStanford Releases Terminal-Bench-Science for AI Research AgentsStanford AI Lab
 articleLong-Horizon-Terminal-Bench 2.0: Automating Diverse Task Construction and Measuring Sustained Agent ProgressZongxia Li, Zhongzhi Li, Yucheng Shi, Ruhan Wang, Junyao Yang, Chengsong Huang, Zhichao Liu, Xiyang Wu, Anhao Li, Yue Yu, Ergan Shang, Fuxiao Liu, Tong Zheng, Ninghao Liu, Lichao Sun, Haitao Mi, Leowei Liang
 postWe asked @TencentHunyuan authors why generating a harder coding task keeps…AlphaSignal
Checking sign-in…
Loading comments…