tokenizers v1: encode, decode and scaling, measured
Source
huggingface.co
Date
Context
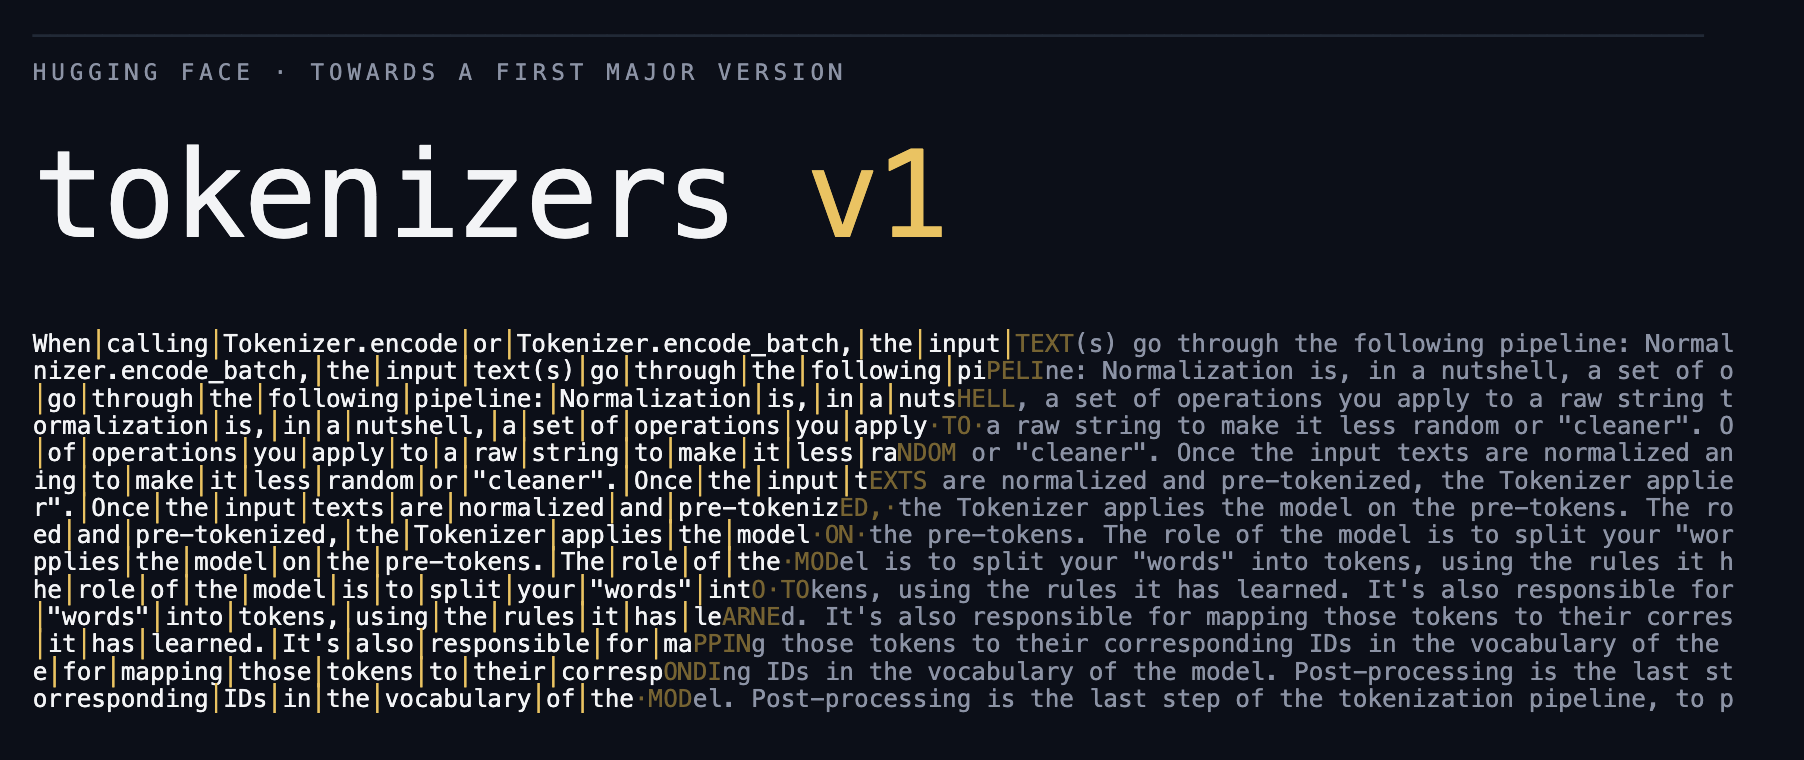
The tokenizers v1 release candidate accelerates the conversion of text into the numbered text units a model reads, while preserving the resulting IDs. It saves work by caching repeated text pieces and reusing temporary memory during encoding. Those changes target the CPU preparation stage that can otherwise leave an AI accelerator waiting for input. The release report explains the implementation and measurements.
The authors report single-thread encoding speeds between 3 and 30 times those of v0.23 across ten tested model families on an M4 Max. These are Rust-library measurements, excluding Python call overhead. They measure text preparation rather than an equivalent acceleration of an entire model request.
Key takeaways · AI-distilled
The speedup comes from 'bitcannon': a hand-written splitter using SIMD bitstream operations (covering GPT-2, cl100k, o200k, Tekken, DeepSeek patterns) replaces the regex engine used to find pre-tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → boundaries, deciding 64 bytes per register operation.
A thread-local word cache maps each pre-token's bytes to its finished token IDs so a repeated word is merged only once; the benefit scales with how many pre-tokens actually repeat in the input, so it helps less on inputs with few repeats.
The merge loop was rewritten around a caller-owned scratch buffer and an intrusive doubly-linked list, avoiding per-call allocator hits; each candidate pair is packed into one 64-bit value so 'no merge here' becomes a branchless integer comparison.
Across ten model families, v1 encodes 3 to 30 times faster than v0.23 single-threaded on an Apple M4 Max (t5-base slowest, gpt2 fastest), scaling at 76% of linear across eight workers, while producing byte-identical token IDs to the old release.
Training support is behind a default-on Cargo feature that pulls in a C++ dependency; encode-only users can drop it with 'cargo add tokenizers --pre --no-default-features --features http' to avoid that dependency entirely.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.