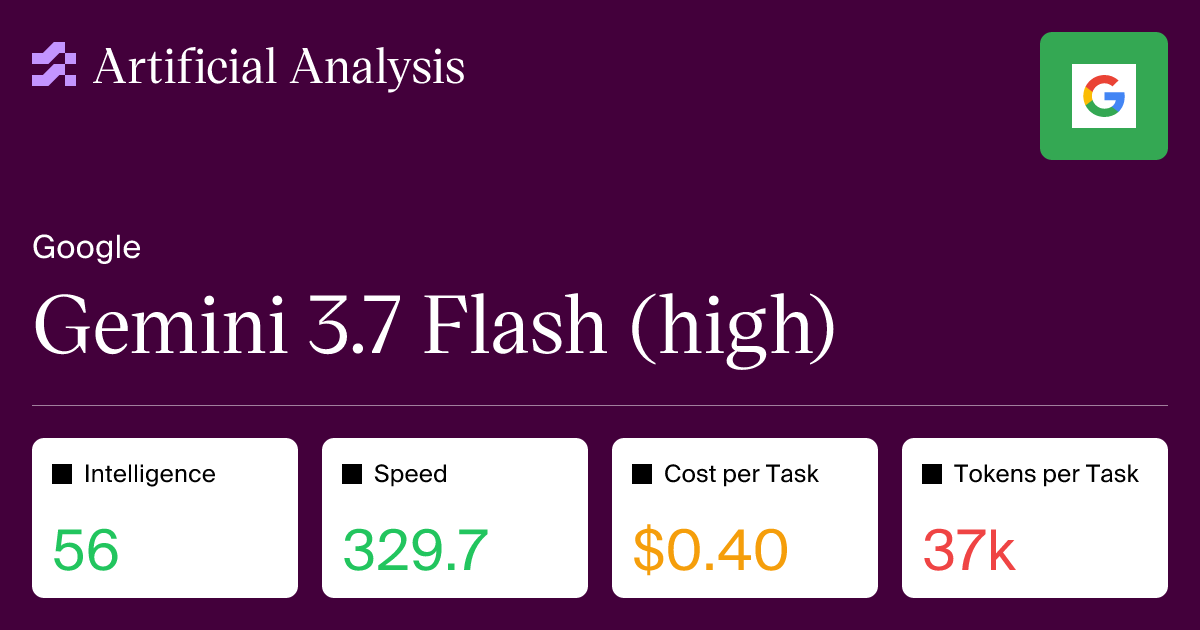
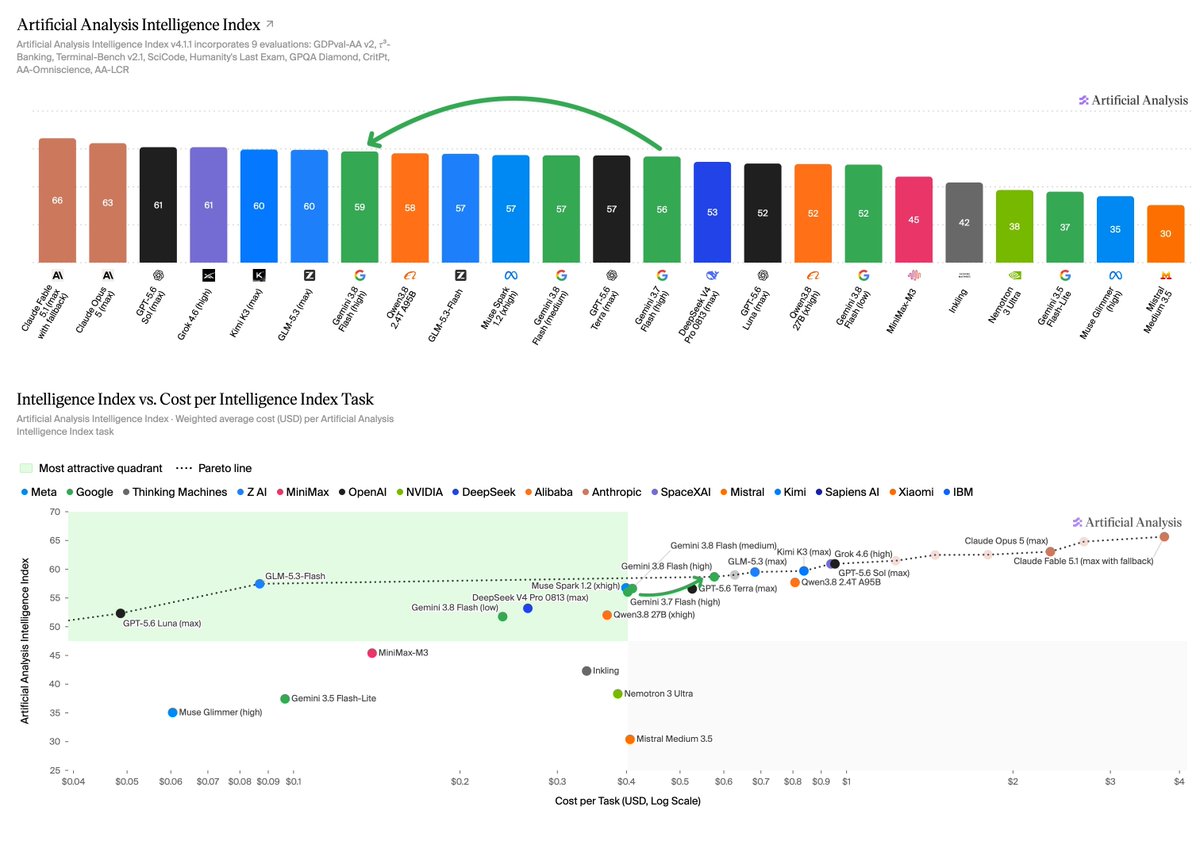
Gemini 3.7 Flash's analysis page separates answer quality from delivery speed. Viewed on October 12, 2026, Artificial Analysis reports an Intelligence Index score of 39 and output speed of 313.6 tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → per second for the high-reasoning configuration. Its measurement definitions specify that output speed measures generation after output begins, so it does not describe the entire wait for an answer.
On that date the page labels the model deprecated and says only its default 10,000-input-token workload continues to receive performance updates. The figures therefore need their measurement date and workload attached when comparing them with another model.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.