DeepSeek V4.1 Flash lands on AA-AgentPerf with NVIDIA and AMD results
- Source
- x.com
- Date
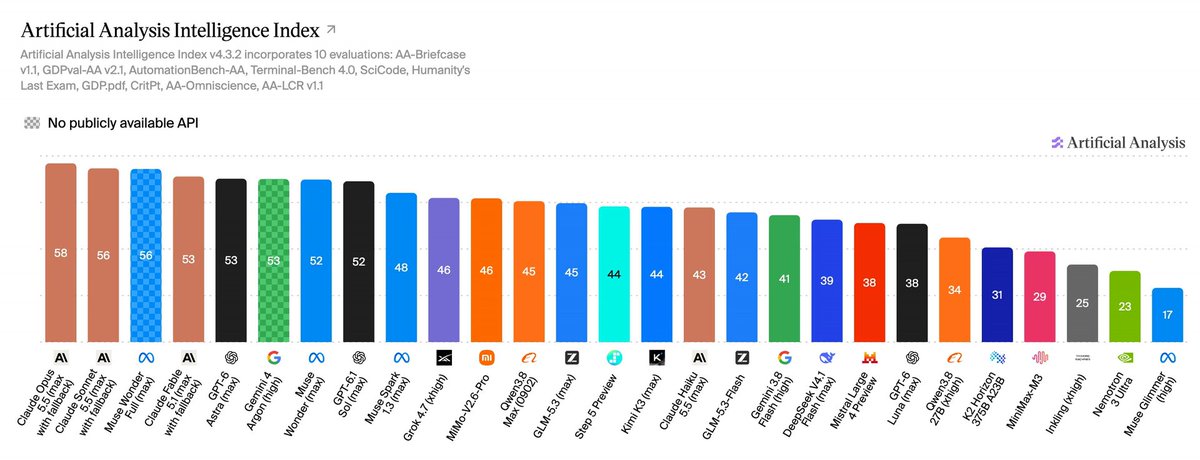
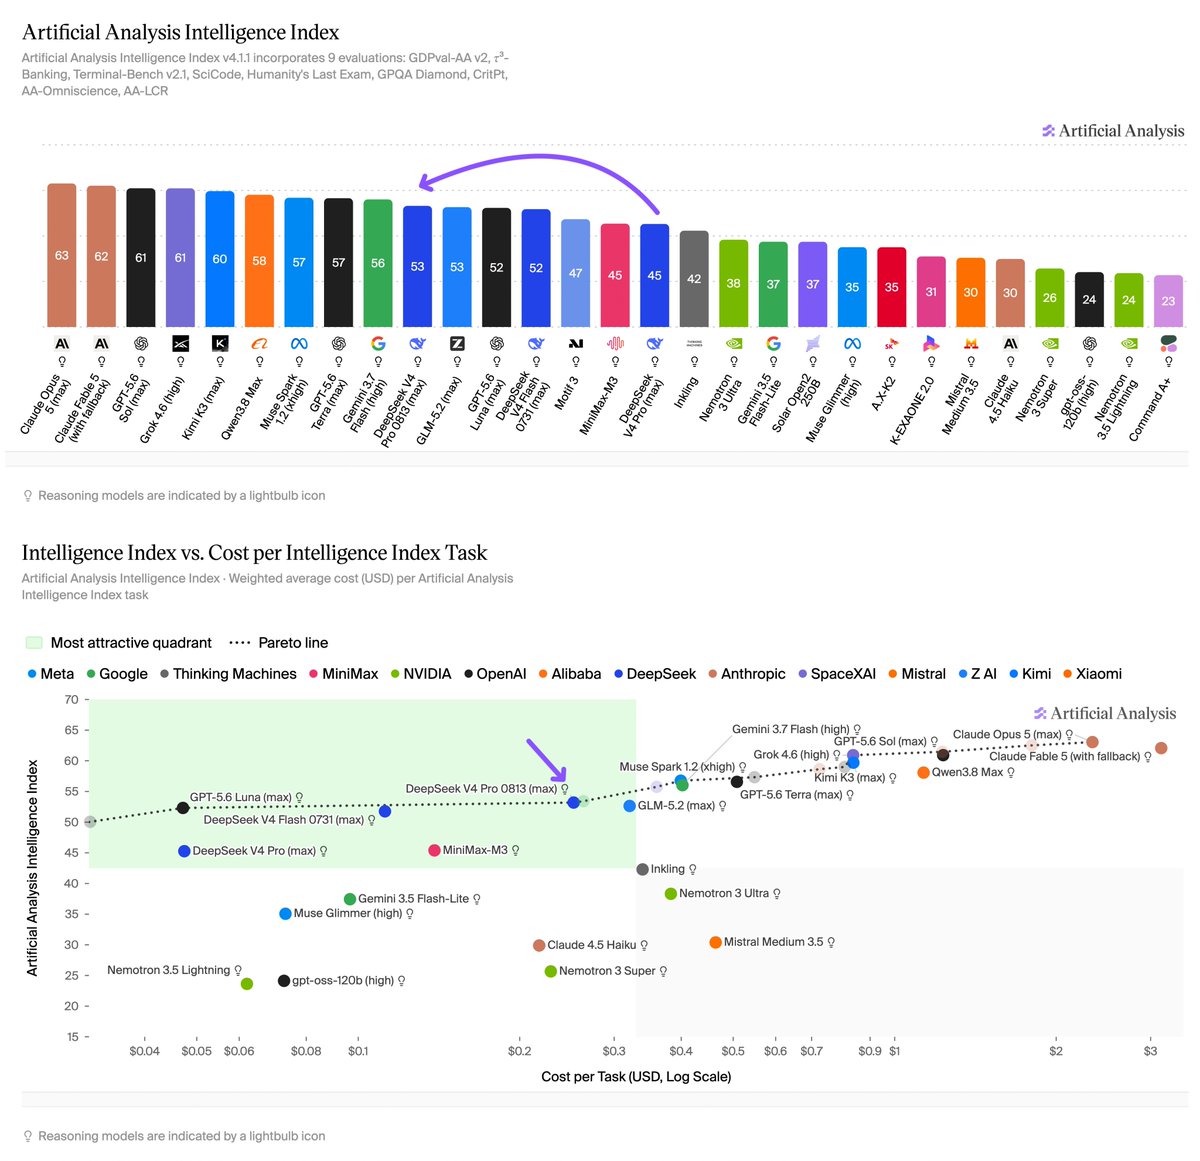
We’ve added DeepSeek V4.1 Flash to AA-AgentPerf, with results for NVIDIA and AMD hardware. At 100 tokens/s per user, NVIDIA GB300 is in first place with throughput up to 261M tokens/s per MW. AA-AgentPerf is our agentic inference performance benchmark. It replays real agentic coding sessions, including prompt caching and tool-call delays, to give a realistic measure of inference performance in day-to-day agentic workloads. We measure total system throughput per megawatt of runtime power, and per-agent output speed at varying concurrency levels, to show the trade-off between system utilization and individual user experience. DeepSeek V4.1 Flash joins the leaderboard today. It brings the leaderboard to four featured models, joining DeepSeek V4 Pro 0813, Kimi K3, and GLM-5.2/5.3. We are evolving the featured models as popular new open-weights models release, and will feature day-0 results for major future releases. Background on DeepSeek v4.1 Flash: ➤ It scores 39 on the Artificial Analysis Intelligence Index, ahead of DeepSeek’s earlier V4 Pro 0813 at 36, with about a third of the parameters (552B ‘backbone’ and 16B active, against 1.6T and 49B) ➤ It is built on a new…
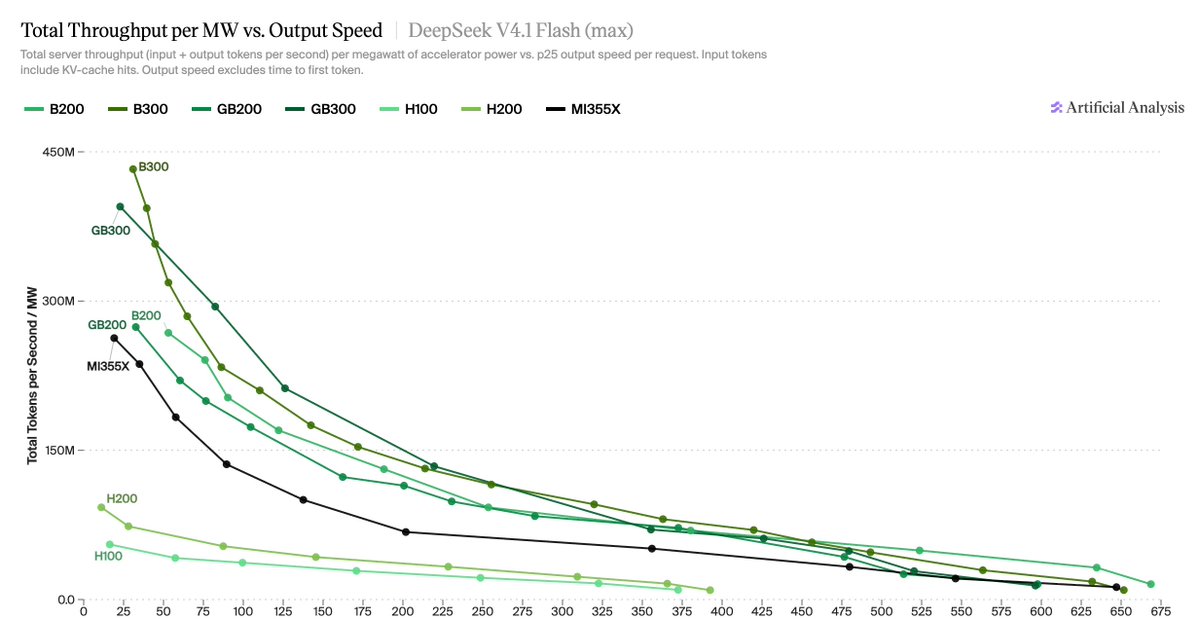
AA-AgentPerf replays real agentic coding sessions, including prompt caching and tool-call delays, and reports throughput per megawatt. This gives concrete hardware and cost data for serving open-weights models to agents.
- Artificial Analysis says DeepSeek V4.1 Flash scores 39 on its Intelligence Index, above V4 Pro 0813 at 36, with about a third of the parameters: a 552B backbone and 16B active versus 1.6T and 49B.
- The architecture is a causal encoder-decoder that activates 8B parameters per input token and 16B per output token, plus 196B of Engram n-gram memory that can live in host memory instead of on the accelerator.
- Compressed sparse needs roughly a quarter of the earlier V4 Flash per token, which Artificial Analysis says leaves room for more concurrent agents per GPU.
- Because the model runs on as few as 2 GPUs, an 8-GPU B300 node stays within about 20% of rack-scale GB300 NVL72; at 100 tok/s per user GB300 leads at ~261M tokens/s per MW versus ~128M for AMD MI355X.
- AA-AgentPerf replays real agentic coding sessions, including and tool-call delays, and reports throughput per megawatt alongside per- speed to show the utilization versus user-experience trade-off.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- prompt caching — Reusing the model's processed form of a repeated prompt prefix so subsequent calls skip re-reading it, cutting cost and latency substantially.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.


Checking sign-in…
Loading comments…