Ai2 uses psychometrics to audit what LLM safety benchmarks measure
- Source
- allenai.org
- Author
- Ai2
- Date
Context
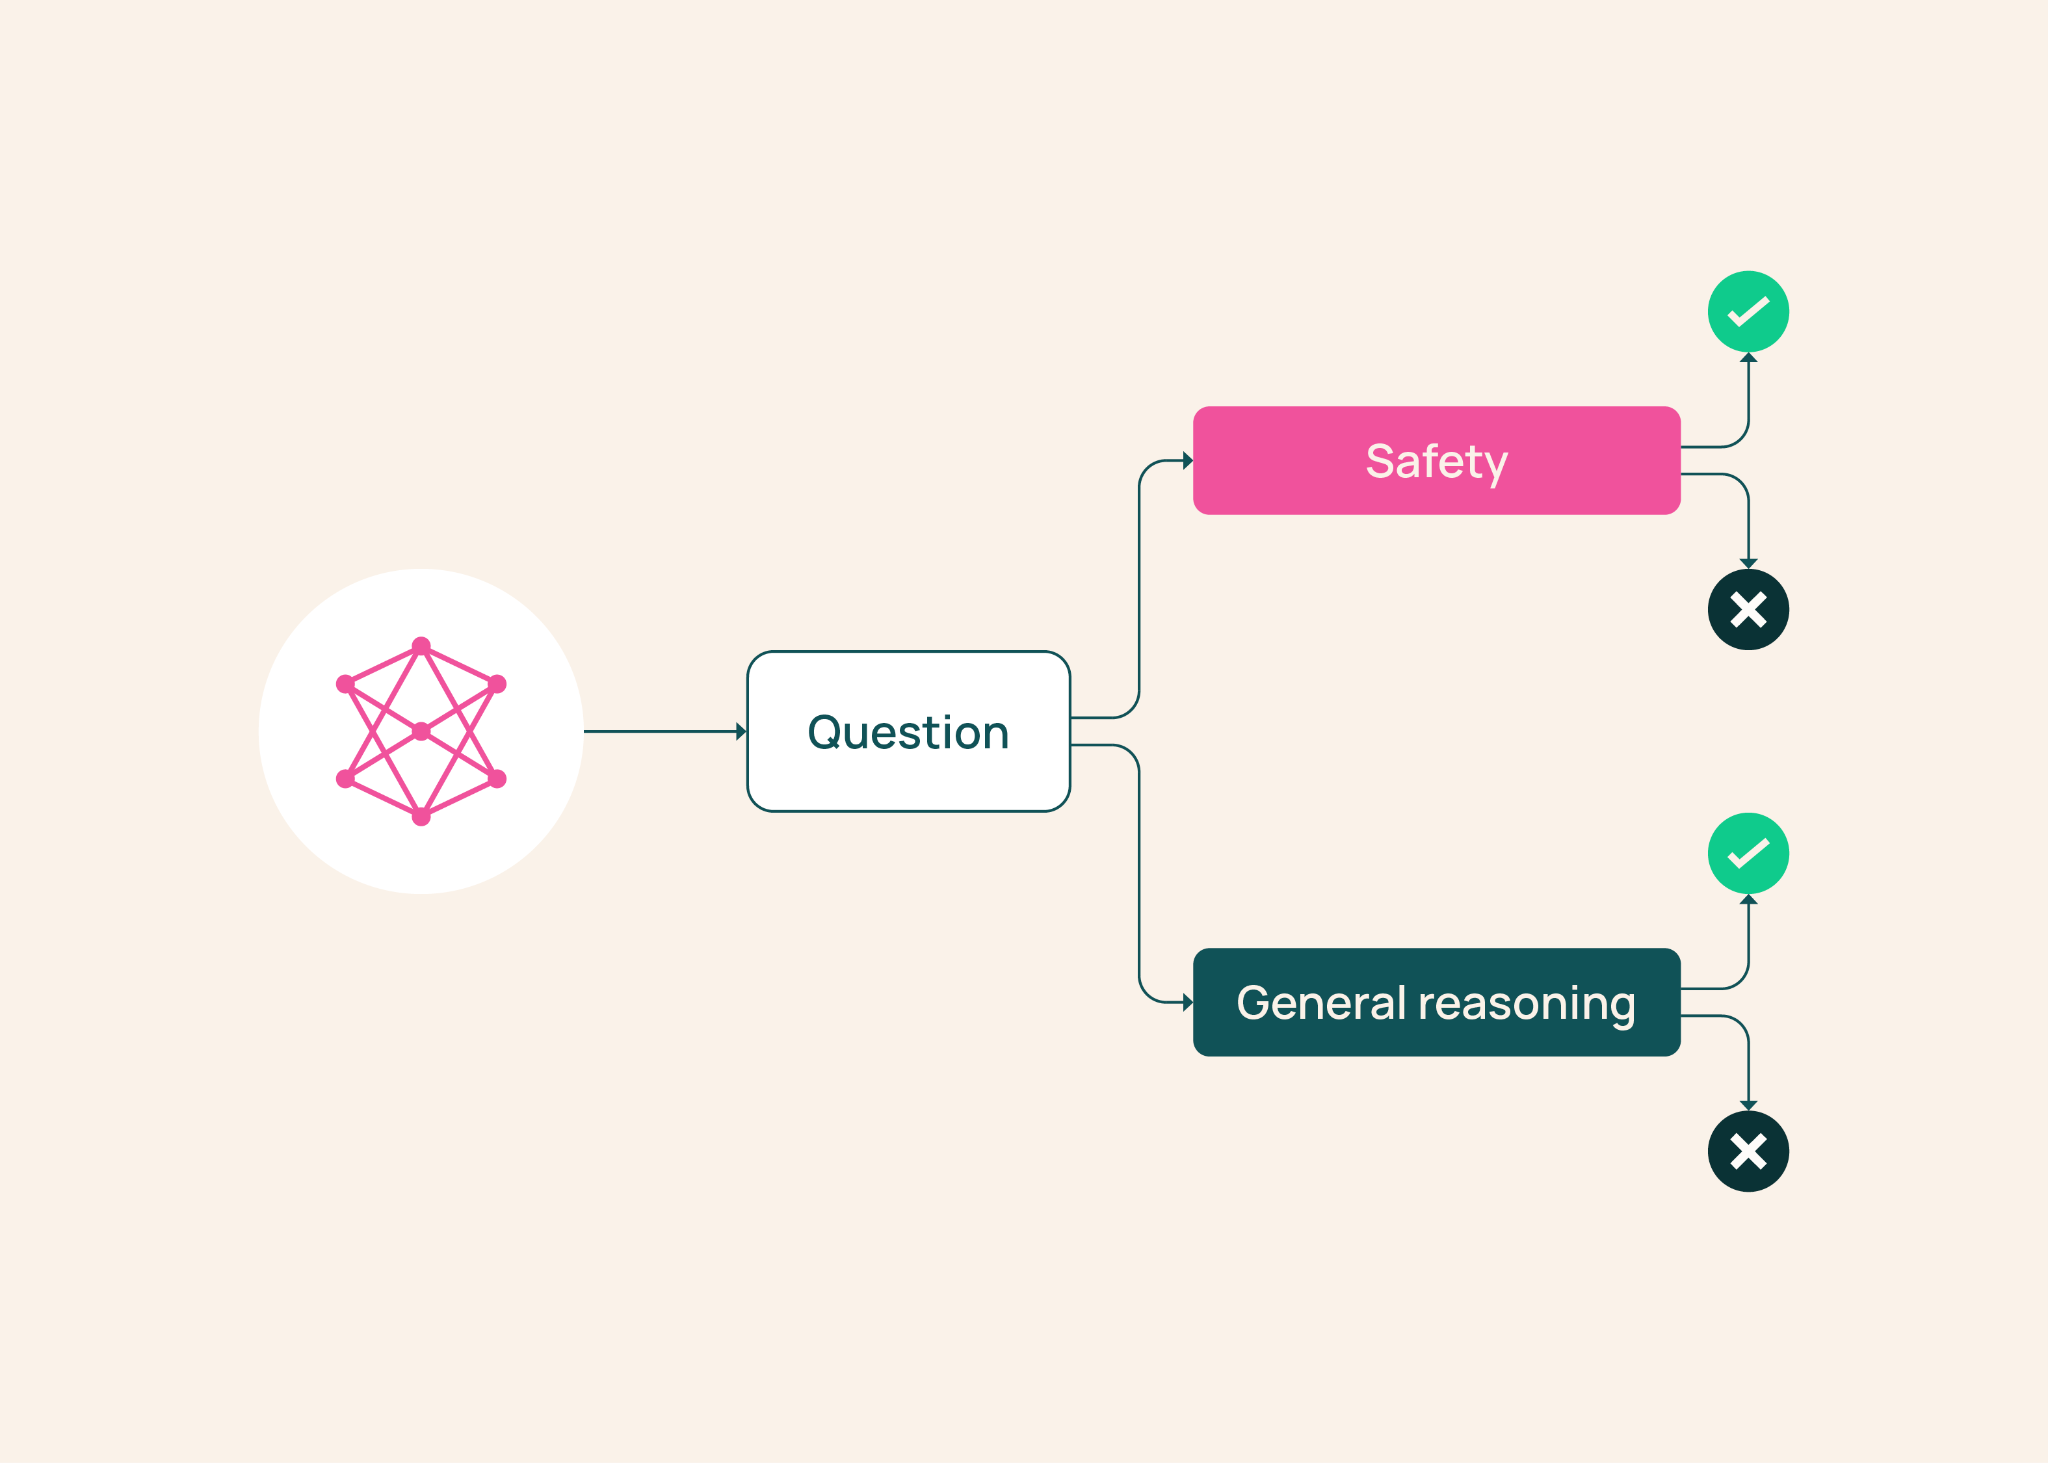
A 's name says what it is meant to test, but its individual questions can depend on other abilities too. Ai2's BenchMIRT checks this by borrowing item response theory from psychometrics, the study of measuring traits from test answers. The idea is that questions differ in how hard they are and in how well they separate stronger test-takers from weaker ones. BenchMIRT's multidimensional version looks at how models perform on each question and estimates which underlying abilities are most closely associated with getting it right.
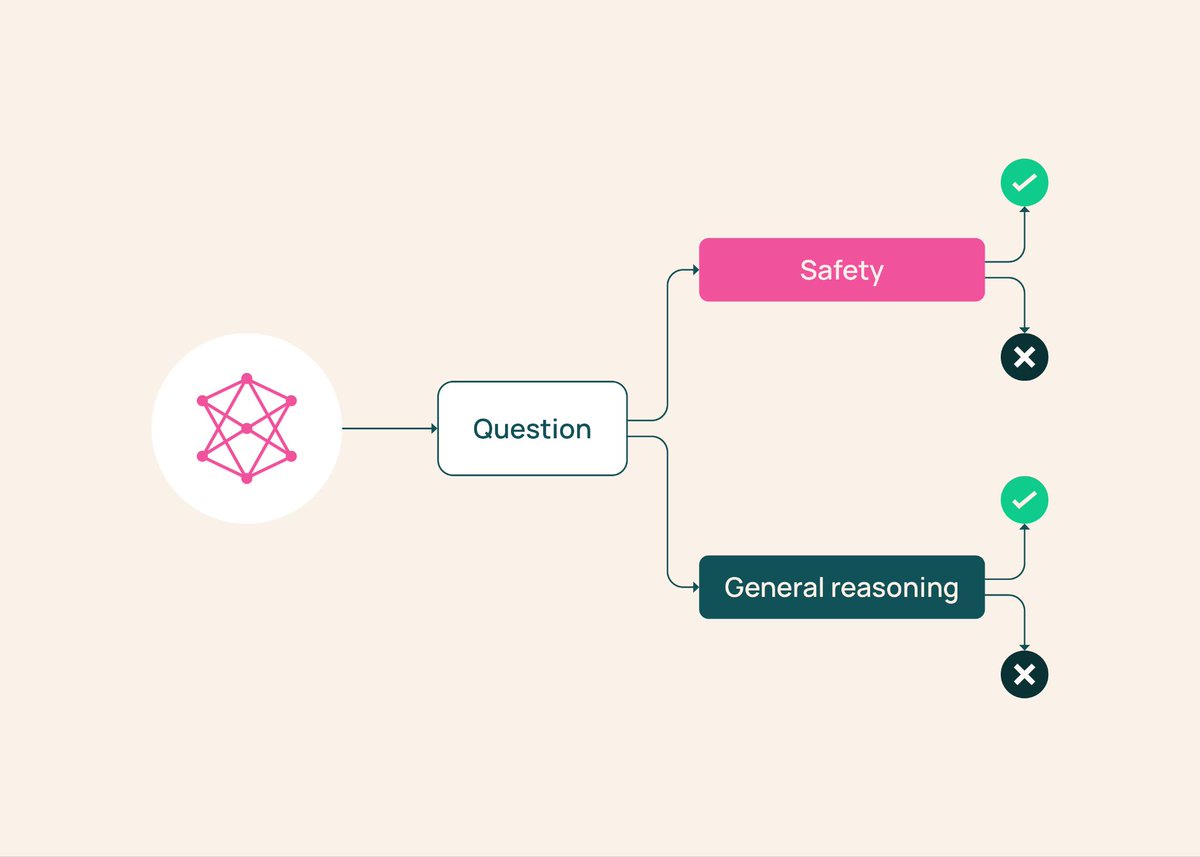
Ai2 fit it to results from 100 language models on more than 34,000 questions across 16 benchmarks, six aimed at general reasoning and ten taken from its Olmo 3 safety suite. It was not told which benchmark was meant to measure what, yet it recovered two main abilities, safety and general reasoning, and the same two emerged each time the analysis was repeated from scratch. Most benchmarks lined up with their stated purpose: reasoning tests tracked reasoning, and and harmful-content tests tracked safety.
BBQ, a social-bias test usually grouped with safety evaluations, did not. Its scores correlated 0.85 with the general-reasoning ability and essentially not at all with safety. One BBQ question about a grandson and grandfather booking an Uber probes age bias, but answering it also requires keeping track of who is who and reasoning from the details given. Ai2 concludes that a low BBQ score may partly reflect trouble reasoning through such questions rather than safety behavior alone, and stresses that this does not necessarily make the benchmark flawed, only that a single score can combine several signals.
Ai2 also states limits. Every model in the study was released by March 2025, and the abilities BenchMIRT finds depend on which benchmarks it is given, so a different collection of evaluations could surface different ones.
 articleBenchMIRT: What are LLM benchmarks actually measuring?allenai.org
 articleFinding Flawed Questions in AI Benchmarks with PsychometricsStanford AI Lab
 articleEvalDetectBench: A Benchmark for Measuring Evaluation Awareness in Frontier Language ModelsXinning Li, Kemunto Ochwang'i, Aryasomayajula Ram Bharadwaj, Alexandra Souly, Robert Kirk
Checking sign-in…
Loading comments…