Inside the vLLM Changes That Multiplied Agentic Inference Throughput
- Source
- x.com
- Date
Shoutout to the cracked team at @vllm_project that implemented recent agentic workload optimizations. (1/5)🧵

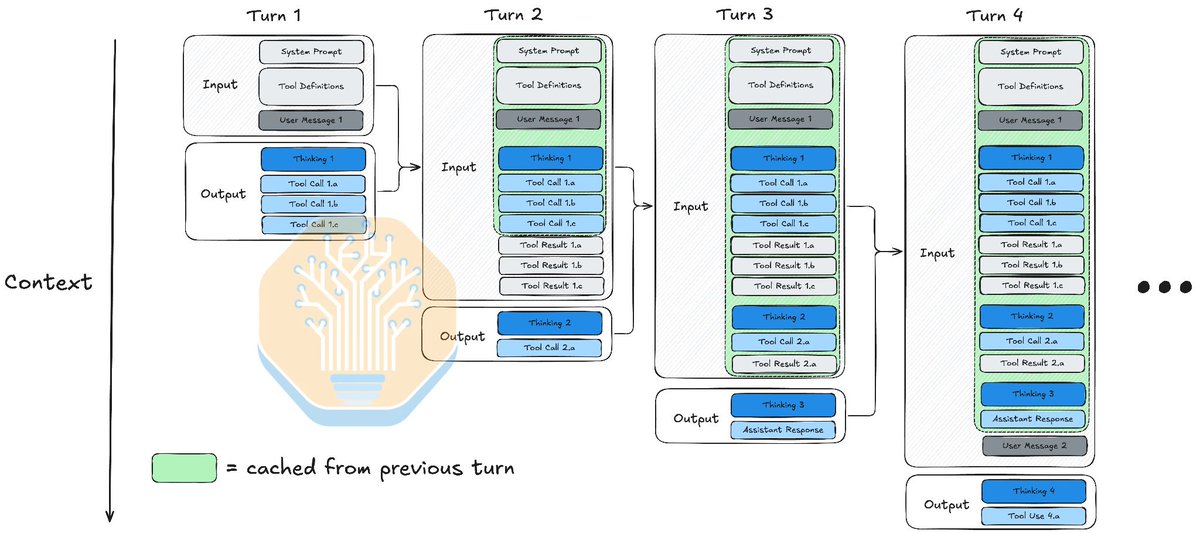
Agents reread their whole history every turn. Reuse the model's cache of it and you skip that work. Saving that cache off-GPU was wasteful: agents each saved their own copy, and every turn re-saved everything from scratch. Now, one save per shared prefix, and each turn writes only what's new. (2/5)

@vllm_project Another optimization lets split-across-machines serving hand over a hybrid model's complete state, so the decode half doesn't start with amnesia. All of this came from replaying real agent traffic. (3/5)

@vllm_project With these and other optimizations, the team at vLLM brought Kimi inference to new heights, increasing high-concurrency throughput by more than 6x in 2 weeks. (4/5)

Context
SemiAnalysis described recent changes the vLLM project made for workloads, where each turn of an agent's loop rereads its entire prior conversation. Reusing the model's cached computation from earlier turns avoids redoing that work, but SemiAnalysis said the previous approach saved each agent's cache separately and rewrote the whole thing every turn. The new approach saves one copy per shared prefix and writes only the new part each turn.
SemiAnalysis also described a second change letting disaggregated serving, where prefill and decode run on separate machines, hand over a hybrid model's complete internal state, so the decode stage does not restart without . Both changes came out of replaying real agent traffic rather than synthetic benchmarks, according to the thread.
With these and other changes, SemiAnalysis said the vLLM team increased high-concurrency throughput for Kimi by more than six times over two weeks, a result it attributes to the project's own testing rather than an outside .
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…