AGENTIC TRAFFIC NOW MAKES UP MORE THAN 70% OF ALL INFERENCE TRAFFIC 🚀
Agentic workloads are characterized by four elements:
🟠 Multi-turn: a session includes tens or hundreds of turns, leading to high potential KV-cache reuse.
🟠 Long context: system prompts, tool definitions, and the large number of turns make context accumulate quickly.
🟠 High prefix reuse: since the conversation progresses linearly, where output from turn n-1 is concatenated to turn n (typically), most context can be served from KV cache rather than recomputed (this depends on the amount of storage available to store KV tensors). As n grows, the ratio of cached input relative to uncached input typically tends towards 1.
🟠 Sub-agent bursts: a session launches multiple short-lived sub-agents with fresh context, which create bursty KV-cache patterns.
SemiAnalysis reports agentic workloads now make up more than 70% of all inference traffic, a shift it attributes to four structural traits distinct from single-turn chat.
Agentic sessions run multi-turn, often tens to hundreds of turns per session, which drives high potential reuse of the KV cacheThe memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.Full definition → since much of the prior conversation stays unchanged between turns.
context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → accumulates quickly in agentic workloads because system prompts, tool definitions, and the growing turn history all stack up, unlike a typical short chat exchange.
Agentic sessions also launch multiple short-lived sub-agents with fresh context, producing bursty KV-cache demand patterns rather than the steadier load of ordinary chat serving, per SemiAnalysis.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
subagent — A separate agent spawned by another to do one scoped piece of work in its own context, returning only the result.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
Why it matters
Quantifies how thoroughly AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → workloads have overtaken single-turn chat, explaining why KV-cache reuse and prefix caching have become the dominant inference-cost lever providers optimize for.


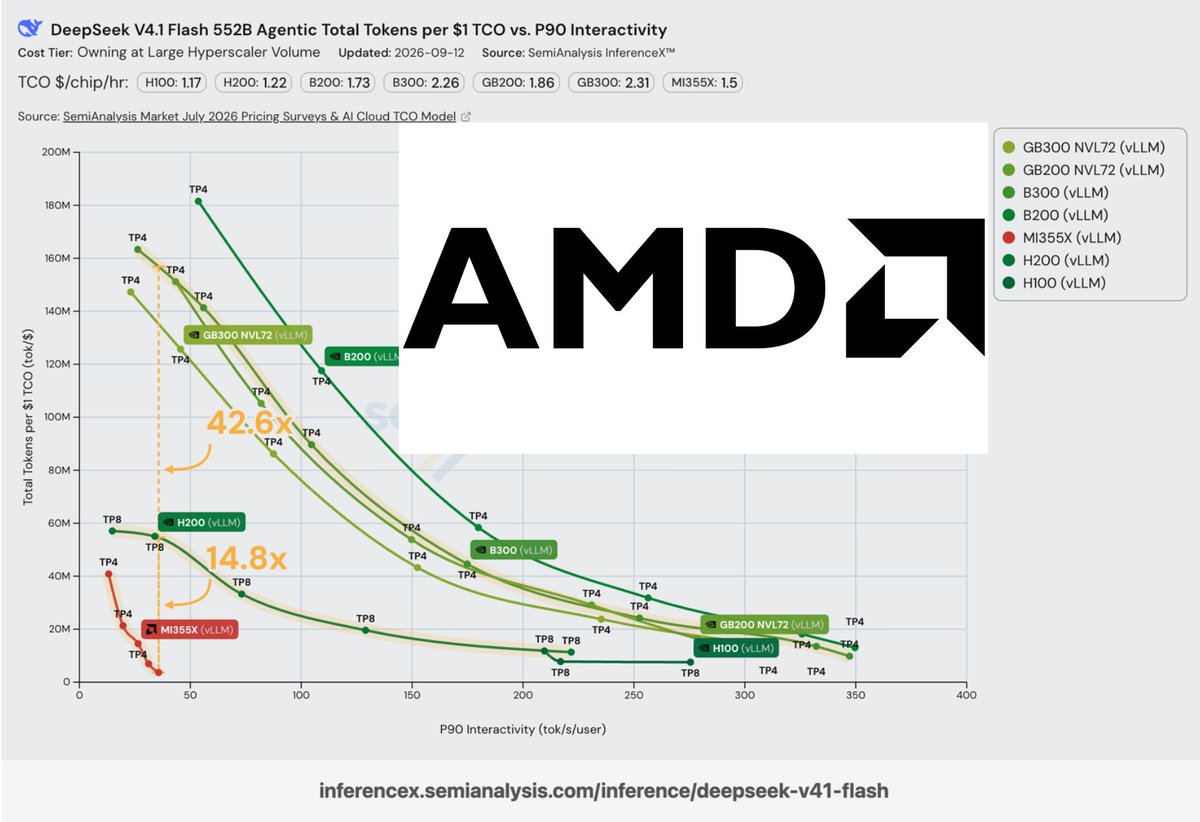 postAMD's Day-Zero DeepSeek Support Still Costs Up to 42x More Than NVIDIA
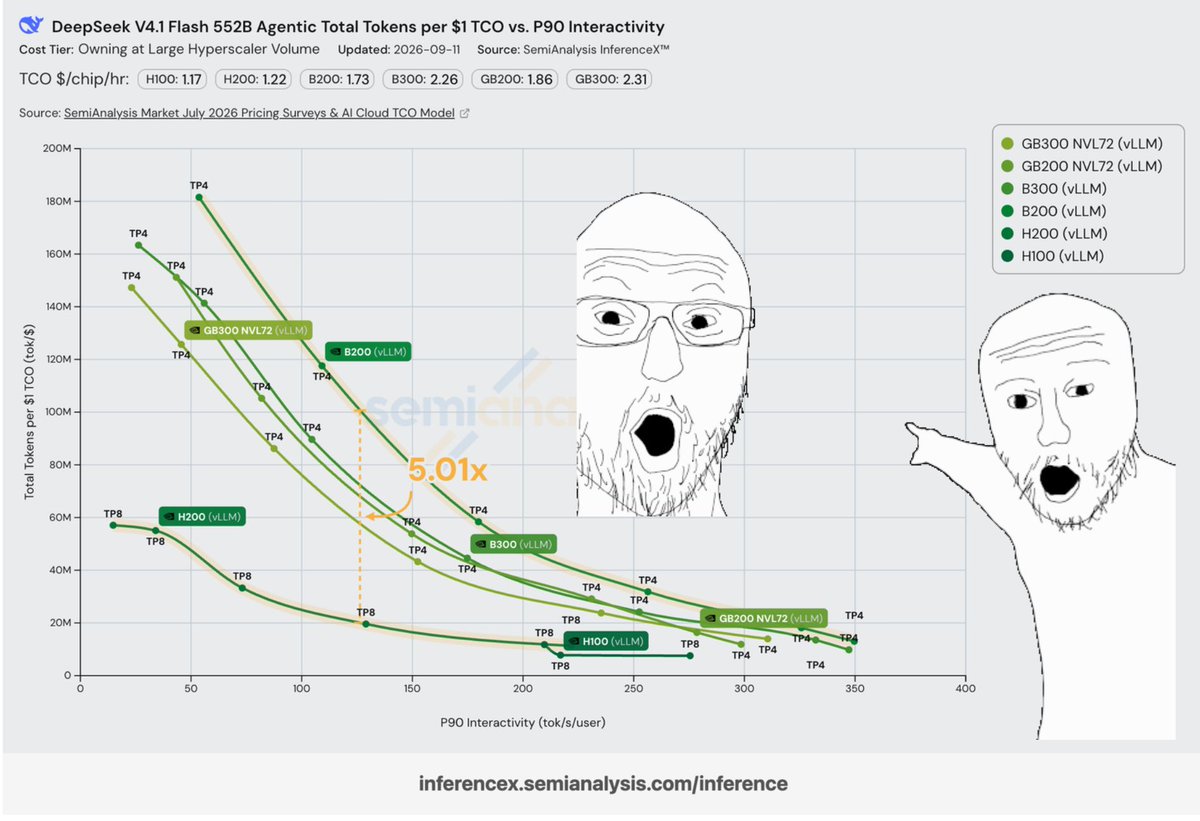 postvLLM Runs DeepSeek v4.1 Flash Day-0 on NVIDIA, Stalls on AMD
 postSemiAnalysis: GPU kernel gains are worth hundreds of millions at OpenAI's scale