Announcing The Artificial Analysis Speech To Speech Index
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
Artificial Analysis built the Speech to Speech Index as a single score for native speech-to-speech models, which take spoken input and answer in speech (artificialanalysis.ai). It weights three datasets equally, and a model needs valid results on all three to be listed. Big Bench Audio tests spoken reasoning with 1,000 questions in categories such as formal fallacies and object counting. A subset of Full Duplex Bench tests conversational dynamics: handling pauses, taking turns, coping with interruptions and backchannels, the short listener cues people give while someone else is talking. τ-Voice tests agentic performance, meaning whether the model completes customer service tasks end to end in airline, retail and telecom scenarios.
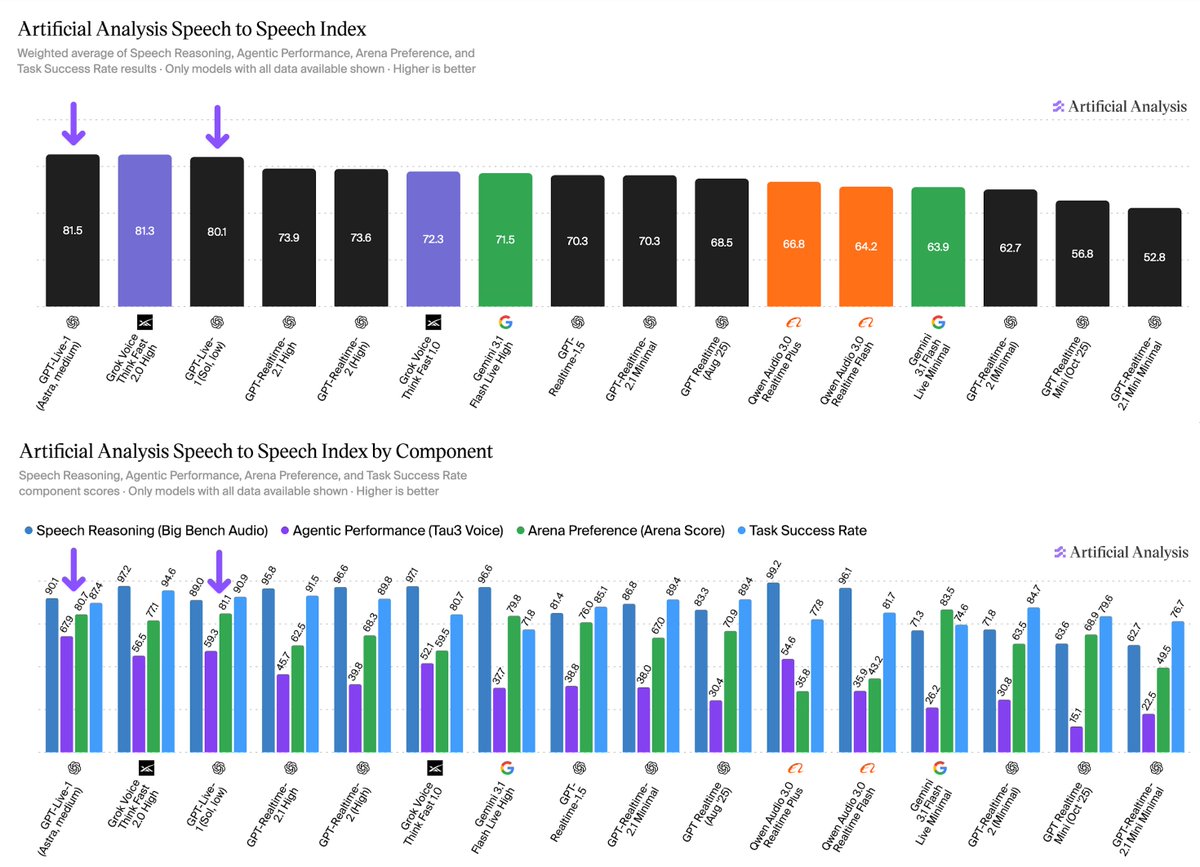
At launch, OpenAI's GPT-Realtime-2 (High) led at 77.2%, followed by xAI's Grok Voice Think Fast 1.0 at 75.7%, GPT-Realtime-1.5 at 72.0% and Google's Gemini 3.1 Flash Live Preview (High) at 69.5%. Spoken reasoning did little to separate the leaders, with scores tightly clustered at the top and Grok Voice Think Fast 1.0 leading Big Bench Audio at 97.1%. The differences came from the other two parts. GPT-Realtime-2 (Minimal) topped conversational dynamics at 96.1%, while the agentic test was the hardest by a wide margin: Grok Voice Think Fast 1.0 led at 52.1%, GPT-Realtime-2 (High) scored 39.8%, and no model reached 53%.
Speed and cost are reported beside the score rather than inside it, and they rank models differently. Deepslate Opal had the fastest average time to first audio at 0.44 seconds but an index score of 62.1%, while GPT-Realtime-2 (High) took 2.33 seconds. Gemini 3.1 Flash Live Preview (Minimal) was cheapest at $1.50 per hour of input audio with a score of 56.6%, against $4.14 for GPT-Realtime-2 (High).
The index has since changed. In an October post announcing Grok Voice 3.0 at 86.9, Artificial Analysis describes the index as averaging Big Bench Audio, τ-Voice, arena preference and task success rate, with Full Duplex Bench no longer listed (x.com), as covered in this later Intel item. Launch scores should therefore not be compared directly with later ones.
- The Speech to Speech Index weights three datasets equally: Big Bench Audio for reasoning, a Full Duplex Bench subset for pauses, turn-taking and interruptions, and tau-Voice for end-to-end airline, retail and telecom service tasks.
- GPT-Realtime-2 (High) led the launch index at 77.2%, ahead of Grok Voice Think Fast 1.0 at 75.7%, GPT-Realtime-1.5 at 72.0% and Gemini 3.1 Flash Live Preview (High) at 69.5%.
- Agentic performance on tau-Voice was the hardest dimension: Grok Voice Think Fast 1.0 led at 52.1% and every model was below 53%, while speech reasoning clustered near the top, led at 97.1%.
- Speed and cost trade against score: Deepslate Opal had the fastest time to first audio at 0.44s with a 62.1% score, and Gemini 3.1 Flash Live Preview (Minimal) was cheapest at $1.50 per hour of input audio with 56.6%.




Checking sign-in…
Loading comments…